TimeSeries-Insight (AI Analysis Engine)
Overview
PlantPulse TimeSeries-Insight is an AI anomaly detection, forecasting, and comprehensive analysis MCP server specialized for manufacturing time series data.
Using IBM Granite TSPulse (anomaly detection) and TinyTimeMixer TTM (forecasting) AI models, it provides intelligent analysis for all of the plant's time series data, including sensor data, OEE, RAM, EMS, alarms, and work orders.
With 39 analysis tools and a feature store, it supports everything from real-time analysis to precomputed comprehensive insights. Starting 2026.10, instead of waiting to be called as a tool, it finds issues on its own and writes them down as "findings," and the copilot picks them up and notifies people → AI Findings and Accuracy
insight-api(:8970) handles tools and data, while model inference (TSPulse·TTM) is
delegated to insight-server(:8980). Since GPU is only needed on the inference side, the two services
can be placed on different machines.
Where you see anomaly detection in the copilot
Equipment anomalies found by the engine appear in the copilot's Proposals › To-do › Unplanned as Anomalies to Check. There's one row per equipment; clicking a row shows the detail view with trend lines · related tags · evidence, where you decide whether to raise as an incident or dismiss (with a reason) → Proposals
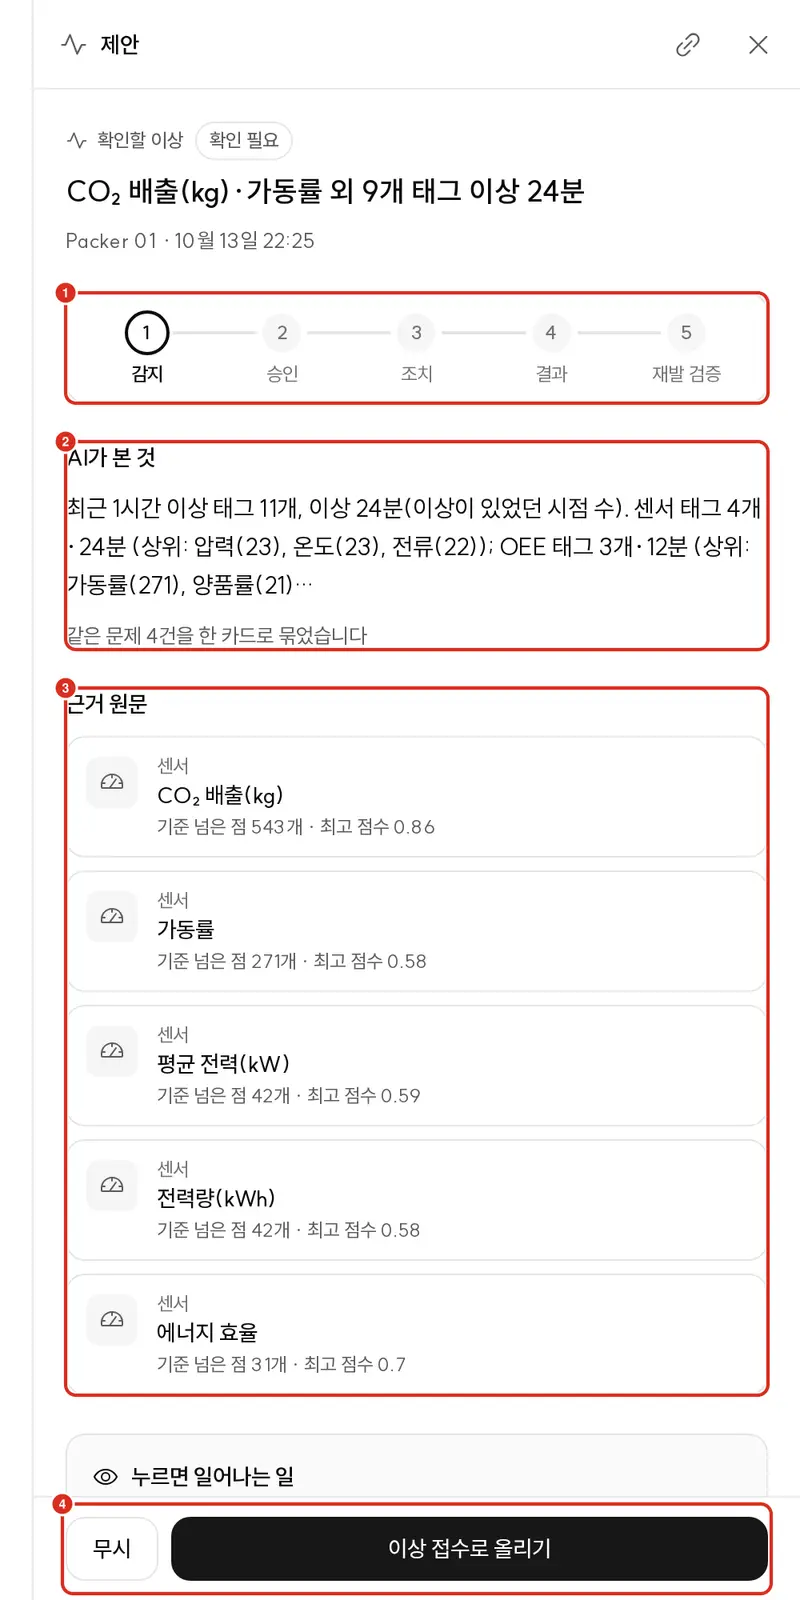
The old "Anomaly Diagnosis" menu and its "Operations Console" are gone; that work is now done in Proposals › Unplanned (the old address /anomaly does not redirect).
| What the old Operations Console did | Now |
|---|---|
| Skim and check anomaly list | Proposals › To-do › Unplanned. Listed by urgency |
| Mark correct/incorrect (AI verdict) | For false alarms, pick a reason in Dismiss → AI Findings and Accuracy |
| Full-scan · targeted "Run" button | No button. The server runs on its own schedule — see below |
| Equipment timeline | On installations with Digital Thread connected, just ask "Show me recent events for this equipment in chronological order" |
Detection runs on two cycles
| What it scans | When (default) | |
|---|---|---|
| Full scan | All equipment | Every 2 hours |
| Targeted detection | Only equipment with a recent alarm | Every 10 minutes |
Cycle · severity criteria · notification channels are documented in Anomaly Detection · Incident Response.
The old per-equipment mute setting and the "Noise Top 10" are not in the new screen.
Newly connected equipment, or equipment that was stopped for a long time, won't produce anomaly scores until a baseline is established per tag. During that period, anomalies that do occur won't appear as Anomalies to Check → AI Findings and Accuracy — Learning · Unverifiable
AI Anomaly Detection
Underlying model: IBM Granite TSPulse
| Target | Tool | Analysis Content |
|---|---|---|
| Equipment sensors | detect_asset_anomaly | Detects abnormal patterns in temperature, pressure, vibration, etc. |
| System resources | detect_system_anomaly | Detects CPU, memory, disk anomalies |
| OEE | detect_oee_anomaly | Abnormal patterns in availability, performance, quality |
| RAM | detect_ram_anomaly | Abnormal patterns in MTBF, MTTR |
| EMS | detect_ems_anomaly | Anomalies in energy consumption, power, carbon emissions |
| Work orders | detect_order_anomaly | Production quality anomalies (OEE/RAM/EMS/composite) |
| Alarms | detect_alarm_anomaly | Abnormal alarm frequency patterns |
Key parameters:
threshold— Anomaly determination threshold. For equipment sensors (detect_asset_anomaly), this applies to the corrected score and defaults to 5.0 — 🔴0is not "automatic"; it treats nearly every point as anomaloustop_k— Number of top anomalous metricslookback_minutes— Analysis time rangetarget_columns— Analysis target (if unspecified, all sensors are automatically queried)
The equipment sensor anomaly score (score_scale: calibrated) uses the segment immediately preceding the analysis window as the baseline, measuring how many times (robust z-score) the reconstruction error deviates from that segment's typical fluctuation (median · MAD).
0 means "normal," 5 is the default threshold.
- State tags (values like run/stop) are excluded from scoring.
- Counter tags (such as cumulative production count) are evaluated not as cumulative values but as the average of 5-interval increments — this catches the increment dropping to 0 when production stops.
- The leading segment that duplicates the model's first window is excluded from scoring.
- The aggregation/smoothing window is 8 / 4 by sensor standard (
aggr_win_size·smoothing_window_size). The previous 32 / 16 smoothed scores over nearly 30 minutes, missing short stoppages.
Domain-side scores like OEE · RAM · EMS are still normalized to 0~1 per call — even with the same threshold
the scale differs.
AI Forecasting
Underlying model: TinyTimeMixer — Granite-TTM R3 (512-96-dec-512-r3, context 512 · forecast 96)
| Target | Tool | Forecast Content |
|---|---|---|
| Equipment sensors | forecast_asset | Future trends of sensor values |
| System resources | forecast_system | CPU/memory/disk usage |
| OEE | forecast_oee | Future trends in availability, performance, quality |
| RAM | forecast_ram | Future trends of equipment reliability metrics |
| EMS | forecast_ems | Forecast of energy consumption, carbon emissions |
| Work orders | forecast_order | Future trends in production quality |
| Alarms | forecast_alarm | Alarm frequency trends, failure prediction |
Key parameters:
prediction_length— Number of forecast stepsenable_bounds— Output confidence interval (upper/lower bounds)
Check model_used in the response — a 200 doesn't mean it was TTM
The forecast response includes what was used to produce it.
| Value | Meaning |
|---|---|
TTM | Produced by the trained model |
NAIVE | Data was insufficient, so it fell back to drift · seasonal-naive. The reason is given in fallback_reason |
NAIVE is also HTTP 200Only when data is insufficient, the engine does not raise a failure and instead falls back to simple extrapolation. If the caller only checks for 200, it will see simple extrapolation where it expected a "TTM forecast."
So read and log model_used. A rising NAIVE is itself the signal.
Columns for which even simple extrapolation fails to produce a value are not filled with 0; instead they are listed and excluded in dropped_columns. If all columns are
excluded, the response is 422.
Other failures are not absorbed — because retrying won't fix them, and they must not be hidden.
| What | Response |
|---|---|
| Fatal CUDA error (GPU died) · inference queue full | 503 + Retry-After |
| Model configuration error (below) · weight loading failure · code defect | 500 |
If you requested a confidence interval (enable_bounds) and it didn't come back, bounds_reason states the reason —
it distinguishes "this equipment can't produce intervals" from "insufficient data was sent."
TS_TTM_MODEL_CLASS — Setting that matches the checkpoint generation to the loader
The forecasting model (TTM) uses a different class to read it depending on generation. Select it via a single environment variable in insight-server (introduced in the build after 2026-09-21 — earlier builds don't have this setting and are fixed to ForPrediction).
| Value | Where used |
|---|---|
| Left blank (default) | Determined by the checkpoint's config.json(decompose) — usually leave it this way |
ForPrediction | TTM R2 checkpoint |
ForDecomposedPrediction | Granite-TTM R3 (decomposed forecast) checkpoint |
The default model baked into the image is R3. R2 is also shipped alongside it as model/ttm-r2, so when rolling back you only change the path line, without touching the class.
TS_TTM_DIR=/app/model/ttm-r2 # R2 로 되돌리기 — 클래스는 그 디렉터리의 config 가 정합니다
R2 and R3 share not a single weight key in common, yet each reads the other's checkpoint without raising an exception. Left as is, this produces a model with all 445 parameters freshly initialized (random), which then answers under the label model_used="TTM".
Now, at load time, if even one parameter is newly created because it's missing from the checkpoint, loading is rejected. The log shows this:
[MODEL_LOAD] TTM dir=… , class=ForPrediction, in_channels=…
[MODEL_LOAD_FAIL] TTM dir=… — 학습된 가중치를 못 읽었다. 무작위 초기화 모델로 대체하지 «않는다».
    reason=[ForPrediction] 체크포인트에 없어 새로 지은 파라미터 445개 (예: …) —
           클래스가 체크포인트 세대와 맞는지 보라(TS_TTM_MODEL_CLASS)
A configuration error does not kill the server — since the same process also serves anomaly detection, a single forecast configuration issue won't halt unrelated functions.
Instead, it surfaces in /health. The response's models carries per-model load status, and if even one fails to load, status is degraded (HTTP is still 200). /ping, used by the container health check, is 503 only when both models have failed — this prevents the container from endlessly restarting when only forecasting has died.
"status": "degraded",
"models": {
  "tspulse": { "loaded": true,  "error": null },
  "ttm":     { "loaded": false, "error": "ModelConfigError: …" }
}
⚠ If /health has no models entry, it's from an earlier build — in that build the health check appears normal, so use the forecast request and startup log below instead. This too varies by build.
| Build | Forecast request | Startup log |
|---|---|---|
| After 2026-09-21 | HTTP 500 | [MODEL_WARMUP_FAIL] TTM ch=… 설정이 체크포인트와 맞지 않는다 — 이 설정으로는 모든 예측이 실패한다 |
| Earlier | HTTP 200 · model_used="NAIVE" | [MODEL_WARMUP_SKIP] TTM ch=… |
In earlier builds, even a configuration error was absorbed into simple extrapolation, so it could run with /health appearing normal · forecast returning 200 · every answer quietly being simple extrapolation. Now, unrecoverable failures (configuration) and transient failures (e.g. insufficient data) are separated, and only the former is surfaced.
🔴 Determine which build you're on by the "log line," not the build number. This month's image tags are rebuilt multiple times with the same date appended (2026.09-<date>-<시각>) — even the same 2026.09 can be a different build.
An incorrect value is not silently dropped to the default — it's rejected on the spot. One of two cases occurs.
| Situation | Message in the log |
|---|---|
| Not a recognized name | TS_TTM_MODEL_CLASS='…' 를 모른다 — ['ForDecomposedPrediction', 'ForPrediction'] 중 하나여야 한다 |
| Name is correct but library version is too old | … 를 골랐는데 이 tsfm_public 판에 그 클래스가 없다 (granite-tsfm 0.3.9 이상 필요) |
Deep Alarm Analysis
| Tool | Description |
|---|---|
get_alarm_stats | Alarm statistics summary — frequency, priority distribution, top alarms, top tags |
analyze_alarm_duration | Alarm duration/MTTA analysis — degradation detection, trend of average acknowledgment time |
analyze_alarm_correlation | Alarm-sensor correlation — which sensor changes trigger alarms |
Equipment Health Index
get_asset_health — Combines sensors + OEE + RAM + EMS + alarms to produce a health score from 0 to 100
Feature Store
Provides fast comprehensive analysis via precomputed features and LLM context.
| Tool | Description |
|---|---|
get_feature_status | Feature store status — scheduler jobs, run times, backfill status |
get_asset_features | Query equipment features — health score, anomaly score, alarms, status, production metrics |
get_asset_context | LLM context — precomputed daily summary analysis text |
analyze_asset | Equipment comprehensive analysis — health score, sensors, alarms, OEE/RAM/EMS, cause hints |
explain_asset_anomaly | Anomaly cause analysis — cause estimation based on anomalous tags, alarms, state changes |
trigger_feature_pipeline | Manually run the feature pipeline |
Feature Store architecture:
- Scheduler: Automatic hourly and daily feature computation
- Embedding: Converts equipment features into vectors to support similarity search
- LLM context: Precomputes daily summary analysis text to maximize response speed
MCP Resources (6)
| Resource URI | Description |
|---|---|
plantpulse://system/info | System information |
plantpulse://domains | Domain list and API endpoints |
plantpulse://metrics/oee | OEE metric descriptions |
plantpulse://metrics/ram | RAM metric descriptions |
plantpulse://metrics/ems | EMS metric descriptions |
plantpulse://metrics/alarm | Alarm metrics and analysis capabilities |
Findings · Watch · Production (2026.10)
Tools that read what the engine has written down on its own, and answer production-related questions. In chat, these appear with the insight_
prefix.
| Tool | Description |
|---|---|
list_findings | Findings the AI discovered on its own — equipment anomalies · order target shortfall · data gaps · data quality · cascading stoppages · failure risk · limit reached · power peaks · AI configuration changes, etc. Severity · urgency · supporting facts · status |
get_attention_ranking | Per-site "equipment to check first today" ranking — watch score (0~100) with three reasons, rank change vs. yesterday |
forecast_order_completion | Whether an in-progress work order will reach its target quantity by planned end — expected good units (P10~P90) · probability of reaching target · shortfall quantity |
get_oee_losses | Why OEE is low — availability · performance · quality loss time, six big losses, stoppage causes |
get_spc_chart | Defect rate control chart (p-chart) by equipment · product — center line · control limits · out-of-control signals |
autonomy_status | Current status of AI's self-driven improvements (normal baseline · scorer) — mode · version in use · shadow · paused |
From 2026.10 re-release (2026-10-20), list_findings · get_attention_ranking are on from the start, so "What should I check first today?" · "Summarize the open findings" get an immediate answer.
The four forecast_order_completion · get_oee_losses · get_spc_chart · autonomy_status arrive turned off, so to use them in Ask an administrator turns them on in
AI Admin Console › MCP Gateway › Tools → MCP Gateway
Equipment·Tag Understanding
When equipment has thousands of tags attached, no human can explain what each one is. The tools below automatically organize the nature of tags using real data statistics and platform metadata.
| Tool | Description |
|---|---|
list_asset_tags | List of equipment tags |
get_asset_profile | Equipment profile — organizes which tags have what nature |
get_asset_tag_relations | Correlation between tags — grouping tags that move together |
Case Search·Comparison
| Tool | Description |
|---|---|
find_similar_assets | Similar equipment search — based on vector embedding cosine similarity |
find_similar_anomalies | Similar anomaly case search — whether a similarly shaped anomaly occurred in the past |
find_fleet_outlier | Fleet outliers — equipment of the same type that behaves differently from the rest |
search_pattern | Pattern search — find segments resembling a specified waveform |
check_failure_precursor | Failure precursor check — whether signals that appeared before past failures are showing up now |
Usage Scenarios
| Scenario | Tools Used |
|---|---|
| Early detection of equipment anomalies | detect_asset_anomaly → explain_asset_anomaly |
| Predictive maintenance planning | get_asset_health → forecast_asset → forecast_ram |
| Daily equipment briefing | get_asset_context → get_asset_features |
| Root-cause analysis of alarm floods | get_alarm_stats → analyze_alarm_correlation → analyze_alarm_duration |
| Comparative analysis of similar equipment | analyze_asset → find_similar_assets |
| Has this anomaly happened before | detect_asset_anomaly → find_similar_anomalies |
| Catching failures before they happen | check_failure_precursor → forecast_ram |
| Same equipment, but only one is off | find_fleet_outlier → analyze_asset |
| Energy anomaly detection | detect_ems_anomaly → forecast_ems |
| Production quality forecasting | detect_order_anomaly → forecast_order |
| Will this order finish on time | forecast_order_completion → get_oee_losses |
| Where to look first today | get_attention_ranking → list_findings |