Admin Console
This is the Operations Console for the data lake node. It allows you to monitor status, metrics, logs, diagnostics, settings, backups, and workers on a single screen via a browser, execute permitted pd commands, and provide a health API to external monitoring systems (Grafana, Prometheus, Zabbix) at the same address.
| Item | Value |
|---|---|
| Backend Module | plantpulse-datalake-admin-api |
| Runtime Environment | Inside plantpulse-datalake container — both Master and Worker nodes |
| Address (TLS) | https://<server-ip>:4950/ |
| Address (Plaintext) | http://<server-ip>:4949/ — same console, same API |
| Login | PP_DATALAKE_ADMIN_USER (Default admin) / PP_DATALAKE_ADMIN_PASSWORD |
| Default Language | English. Append ?lang=ko for Korean |
Documents in This Section
| Screen | Function |
|---|---|
| This Page | General console overview — Access, Login, Layout |
| Batch | Status and history of batch jobs |
| Warehouse | Warehouse loading status |
| Assistant | Natural language queries and approval cards for identifying and resolving issues |
Access
Access via one of the two addresses in your browser. They lead to the same console; only the scheme differs.
https://<server-ip>:4950/?lang=ko      # TLS  — 권장
http://<server-ip>:4949/?lang=ko       # 평문 — 4950 으로 리다이렉트하지 않습니다
Login passwords and session cookies are transmitted in the clear. Always use 4950 on untrusted networks. Port 4949 is kept as a choice, not a mistake, because self-signed certificate warnings can sometimes obstruct operators.
When connecting via TLS, a self-signed certificate warning may appear. Instructions for replacing this with a valid certificate are available in Security Settings.
Login
The login screen displays the node name and its role (Master / Worker). Use this to verify which box you are accessing when working with multiple nodes.
| Variable | Default | Description |
|---|---|---|
PP_DATALAKE_ADMIN_USER | admin | Login name |
PP_DATALAKE_ADMIN_PASSWORD | Default for development in versions installed after 2026-09-05; empty for earlier versions | If empty, the console will not open |
PP_DATALAKE_ADMIN_API_KEY | None | X-API-Key used when a machine calls the log endpoint |
Instructions for changing or initially setting the password are in Web Login Accounts — Admin Console.
This means PP_DATALAKE_ADMIN_PASSWORD is empty. Only the console fails to start; the data lake continues to operate normally. This is a commissioning omission, not a failure. Enter the value and restart.
Layout — Rail and Sidebar
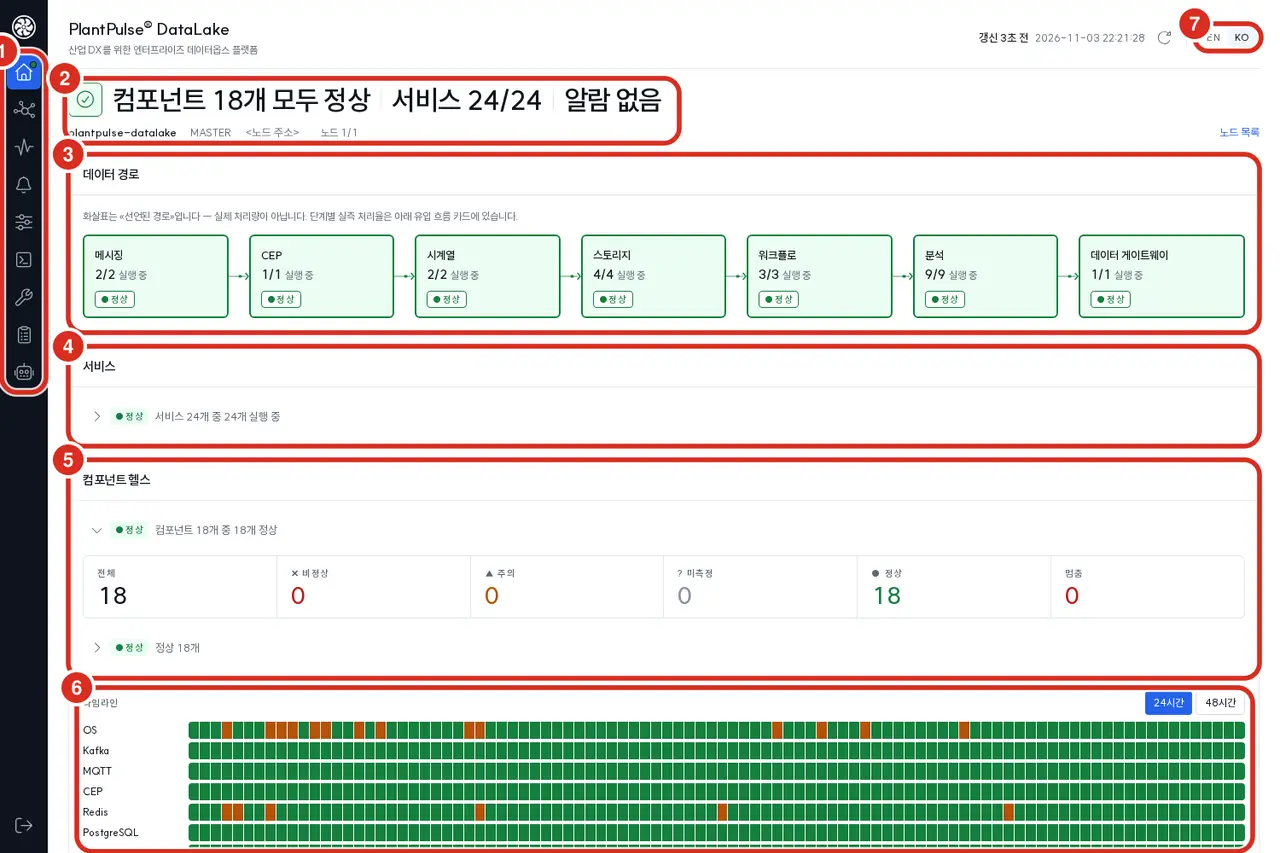
| No. | Item |
|---|---|
| ① | Icon Rail — Navigate between groups. The single dot on the dashboard icon represents the overall health of this node (See below) |
| ② | One-line Summary — «All N components healthy · Service N/N · No alarms». If this line is green, no further action is needed. The line below shows node name, role, address, and node count; [Node List] links to the topology node tab |
| ③ | Data Path — Stages ordered by startup sequence (Messaging → CEP → Time Series → Storage → Workflow → Analysis → Data Gateway) with the number of «Running / Total» services per stage. Arrows indicate the declared path, not actual throughput — real-time throughput is found in the inflow cards below |
| ④ | Services — Expands services belonging to the stages in ③ in the same order. For empty stages like «Messaging 3/4», locate the specific service here |
| ⑤ | Component Health — Total · Abnormal · Caution · Unmeasured · Healthy · Stopped. Unmeasured is not «Healthy» |
| ⑥ | Timeline — Plots health status over time per component (24h / 48h). Hatched areas indicate missing records |
| ⑦ | Language Switch — EN / KO. Appending ?lang=ko to the address has the same effect |
Alarm Cards appear between ② and ③ only when an alarm is triggered (only after exceeding the threshold three consecutive times). If there are no alarms, the card is not rendered. Below ⑥ are the system gauges, inflow, load, storage, and recent events.
The narrow vertical strip on the left is the Rail, containing nine group icons. The rail only displays icons — names appear as tooltips upon hover.
Selecting a group expands its screens into the Sidebar. However, groups with only one screen do not have a sidebar to avoid occupying space unnecessarily.
The rail sequence follows the order of operator inquiry during a failure: «Is there an anomaly?» → «Where?» → «What is the truth?» → «Who to notify?» → «What to change?» → «Command» → «Other screens» → «What happened?».
There are 22 screens in total, across 9 groups.
| Group | Section | Screen | Answer Provided |
|---|---|---|---|
| Overview | — | Dashboard | Is there an anomaly now? |
| Topology | — | Topology (Tabs: Data Flow, Node) | Where in the pipeline is the blockage, and is data flowing elsewhere? |
| Observation | Status | Status, Metrics | Current health assessment and trends from last hour to last week |
| Resource | Storage, Retention | Volume, WAL, replication slots, storage size / what is deleted and when | |
| Activity | Workflow, Event, Log, Diagnostics, Job | Did the nightly job run? What happened? — Event journal, service logs, pd doctor, job history | |
| Alarm | — | Alarm | Who is notified and when? |
| Operation | Config | Settings, API Key, Certificate | Diff between template and render result, template editing/reversion, console-issued API keys, certificates |
| Maintenance | Upgrade, Worker | Versions by module, what needs to be changed for cluster workers | |
| Backup | Backup | Backup sets, schedule editing, execution, recovery | |
| Command | — | Command | Execute permitted pd verbs from the screen |
| Tools | — | Tools | Cards linking to other product web UIs |
| Record | — | Audit | Who changed what in this console? |
| Assistant | — | Assistant | What is the problem, why, and what should be done? — Includes gateway settings and approval cards |
How to Read Rail Dots
There is only one dot on the dashboard icon in the rail. Regardless of the screen, it shows «Is there an anomaly in this node?», and the value is exactly the status of /api/health, the server's aggregated assessment of components. See the dashboard for details.
| Dot | Meaning |
|---|---|
| OK | Server aggregated assessment is healthy |
| WARN | Server aggregated assessment is caution |
| FAIL | Server aggregated assessment is failure |
| UNKNOWN (Grey) | Assessment unreliable — polling stopped, server collector stopped, no response, or unknown assessment |
A grey dot means «Unmeasured», not «Healthy». Other group icons do not have dots; this does not mean the group is healthy, but that group-specific status is not rendered on the rail.
Silence is not health. There are five reasons why an alarm might not sound: muted, rule off, below minimum severity, suppression period, or no channel. The console informs you of each using distinct phrasing.
Screen-Specific Notes
| Screen | Key Note |
|---|---|
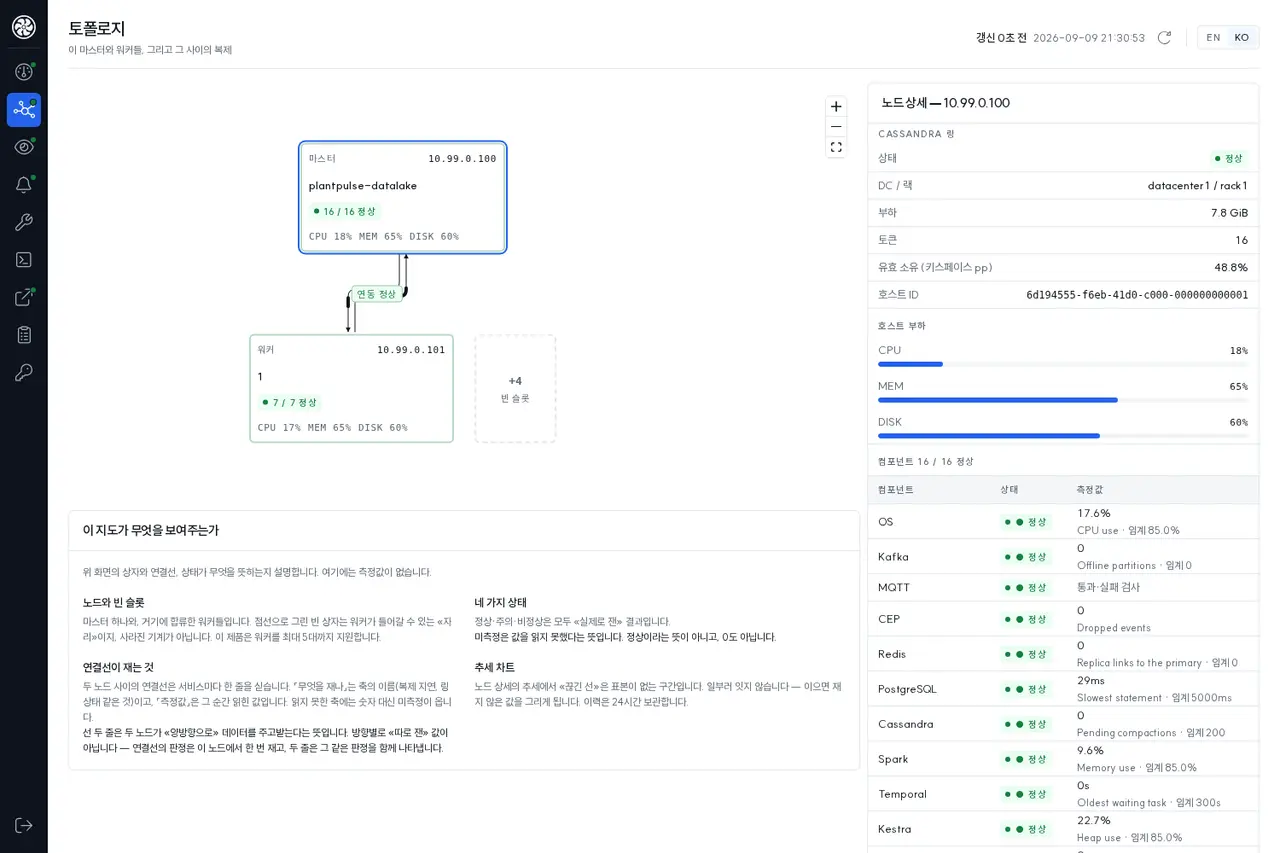
| Topology | Two tabs provide two views of one system — data flow (MQTT → Kafka → Consumer) and nodes (Master, Worker). If the dashboard indicates «Anomaly», use this to identify the affected segment. |
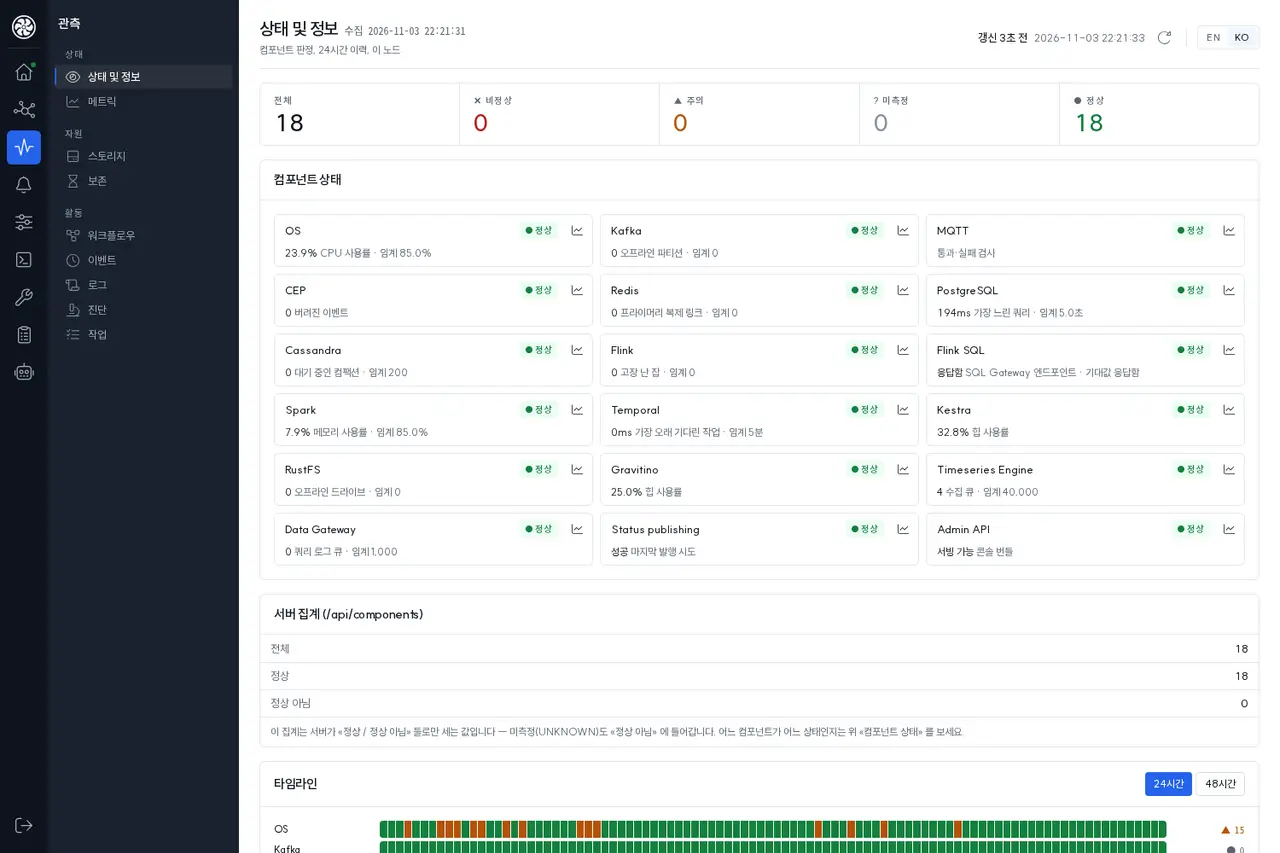
| Status & Info → Component | Clicking a row enters component details. Rows are consistent with the pd status table and refresh every 15 seconds. A «STOPPED» status for the first few dozen seconds after startup is within the expected window. |
| Logs | Displays only files declared by pd logs --list. Logs for app containers (Server, Batch, Warehouse) are not here — use the host's logs.sh. |
| Diagnostics | Results of pd doctor. «Execute Test» runs it again immediately. Only one request is processed at a time; if «busy» appears, retry shortly. |
| Jobs | A single ledger for history of backups, archives, and maintenance jobs. The Backup screen shows backups separately. |
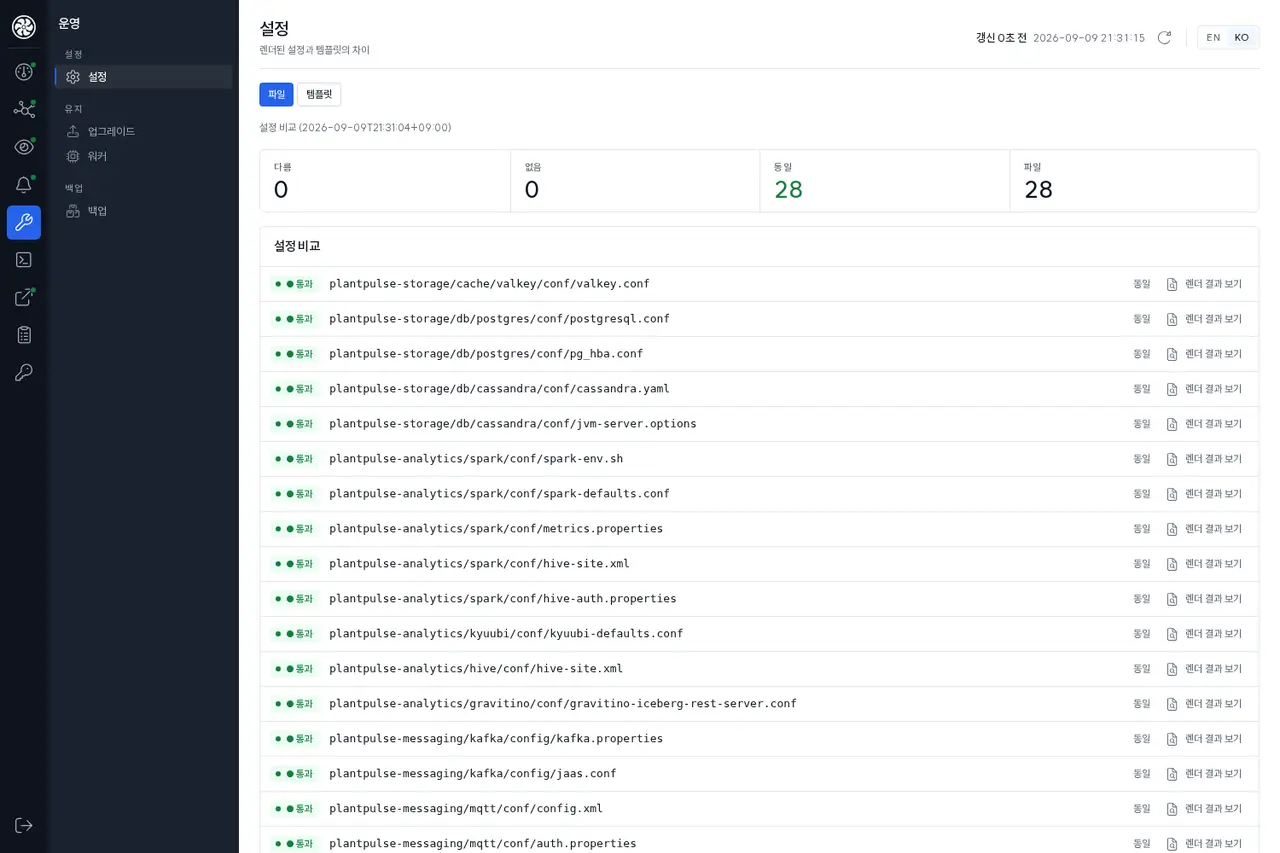
| Settings | Shows «What changes if rendered now» (pd config diff) and «Does my template differ from the image default» (pd config diff --templates). Editing templates on-screen creates revisions for rollback. The master values (passwords, addresses) still reside on the host → Changing Settings. |
| Upgrade | Image tags (/etc/plantpulse-image.env) and versions/revisions by module (/etc/plantpulse-modules.json). Report-only; does not perform upgrades → Below. |
| Worker | Shows commands on what to change for cluster workers, but does not execute them. Execution is performed on the host → Cluster Installation. |
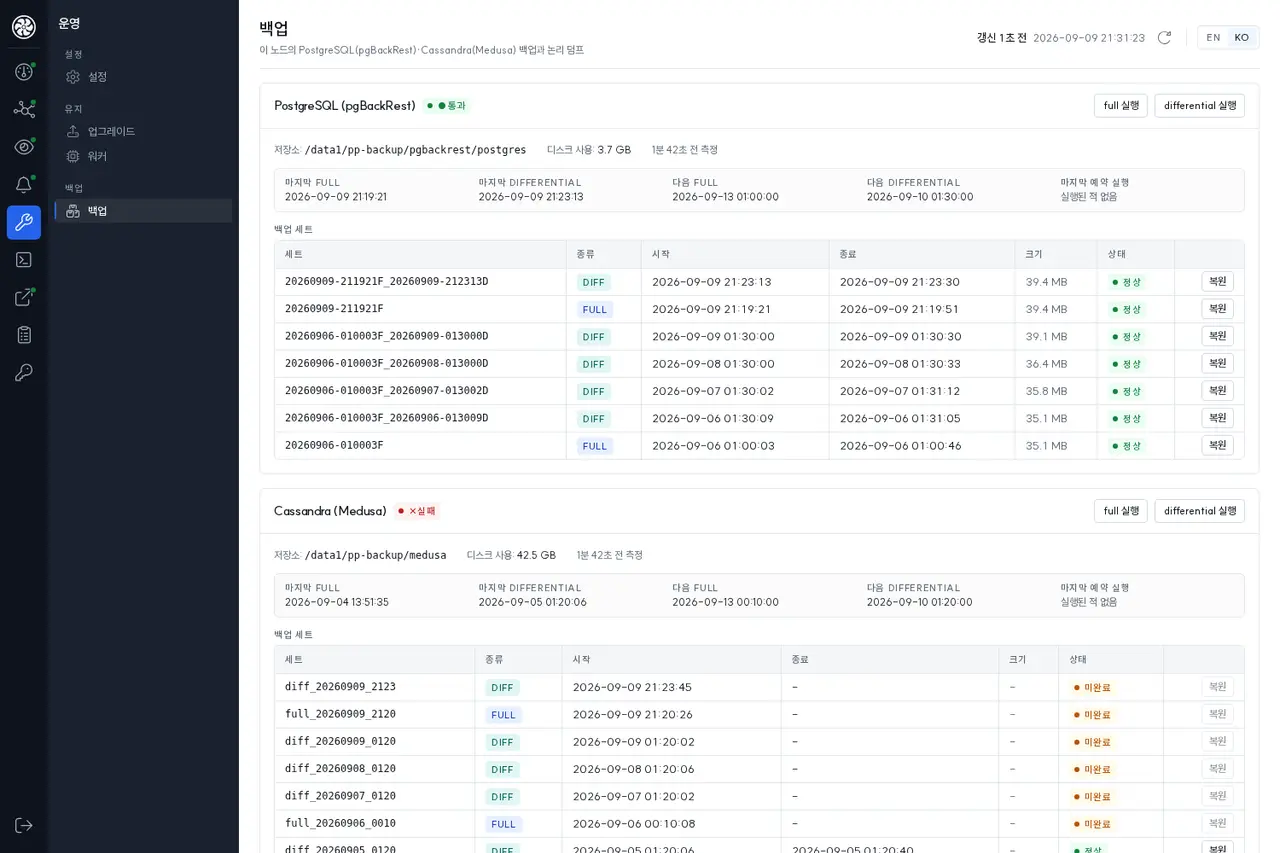
| Backup | Set list, schedules, and current executions. «Schedule editor» invokes pd backup schedule set. Schedules are managed via backup_schedule table + Quartz, not systemd timers → Backup & Recovery. |
| Command | Only pd verbs from the server-defined allow-list are executed (the list is visible on the right). Other commands must be run in the container shell → pd CLI, Below. |
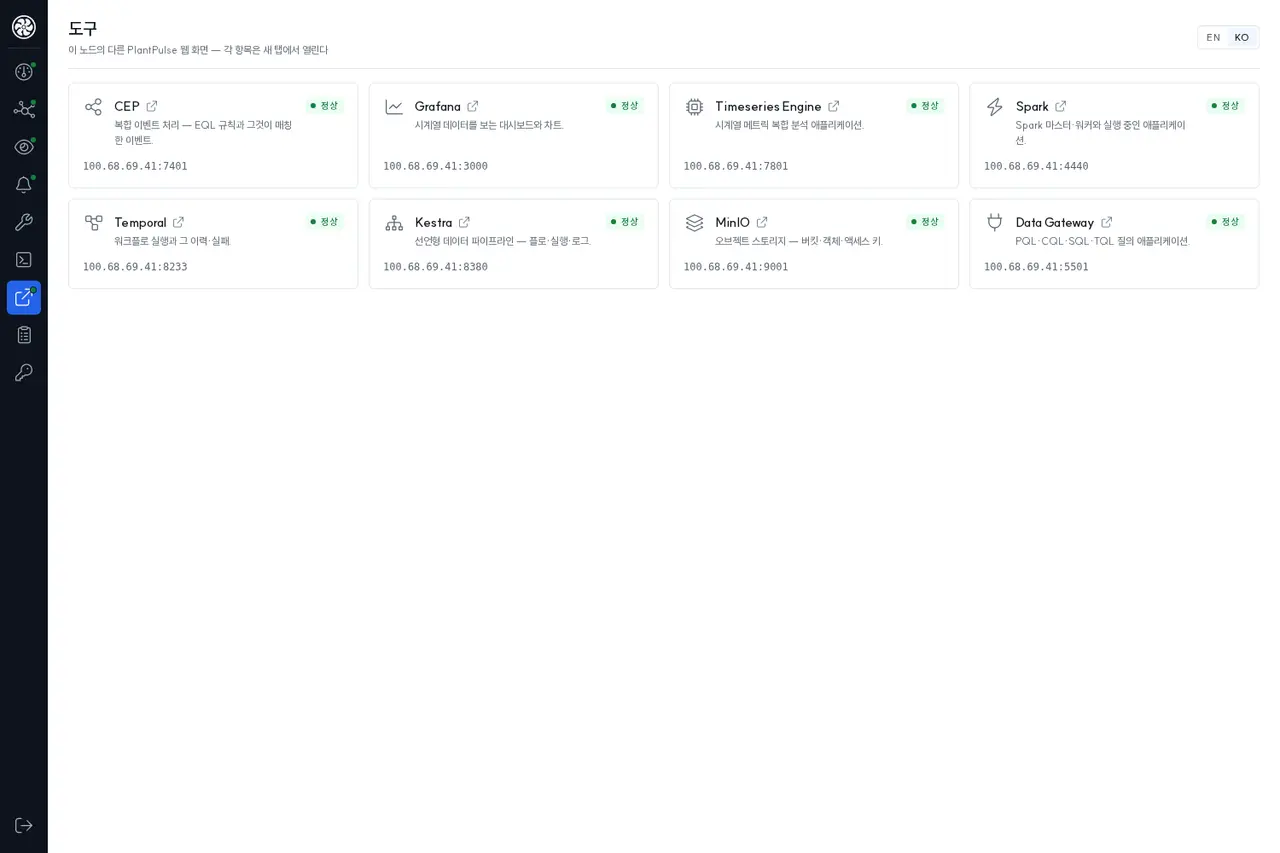
| Tools | Gathers other product web UIs into cards that open in new tabs. The host in the address follows the currently connected host, ensuring you reach the tools for that specific box. Cards for services not present on the node are not rendered. |
| Workflow | Displays both Temporal and Kestra together. Read-only — this screen does not perform execution, triggering, pausing, or termination. «Not applicable» means there is no execution history to assess. |
| Retention | Centralizes table TTL, topic retention, cold tier, and archive jobs. «None» indicates a table without expiration (counters, current values). |
| Credentials | No separate screen. View and change values individually via cards in the Status & Info → Component details → Below. |
| Assistant | Query this node in natural language and execute via approval cards. Requires direct connection to an LLM gateway → Assistant. |
| Audit | Records who changed what in this console. Worker nodes lack an audit store, so this always appears as «Unable to read» — it is not a «quiet week». |
Major Screens
Topology — Identifies where the pipeline is blocked. Consists of two tabs: data flow and nodes.
Status & Info — Health assessment by component. Rows match pd status and refresh every 15 seconds. The Component Version table at the bottom describes the current build rather than the node — including official version, internal version, port, license, source, and module. - indicates «Not applicable» (internal versions are absent for stock components, and some have no listening ports). These same values appear in component details.
Workflow — Monitors whether nightly archives and batch flows ran on time. Displays two engines together: Temporal (Aster TSDB → Iceberg archive) and Kestra (batch flows).
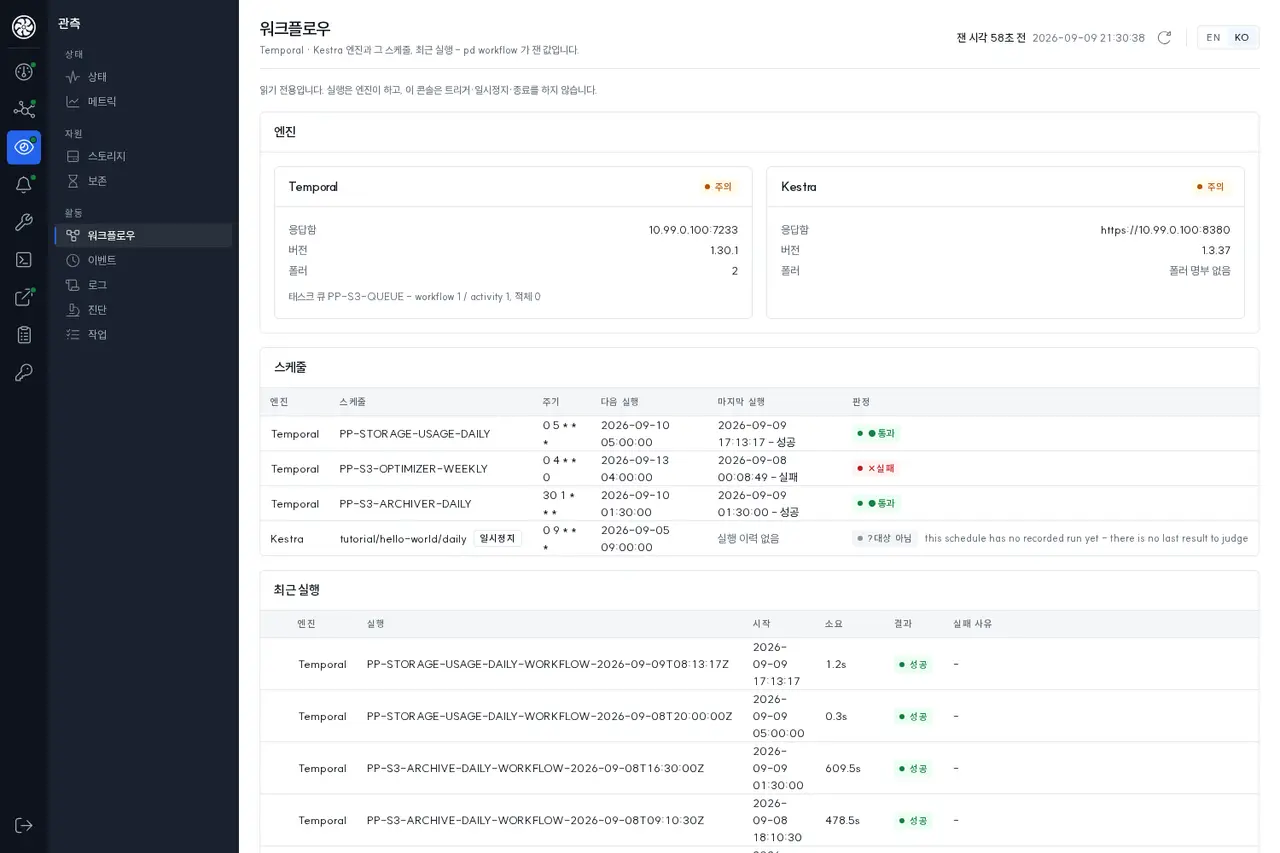
Execution is handled by the engine. This screen does not perform triggering, pausing, or termination — it is for viewing only. Change schedules via the Backup screen (or pd backup schedule set).
Retention — Details what is deleted and when. Consolidates Aster TSDB table TTL and size, Kafka topic retention, and cold tiers with their filling archive jobs on one screen.
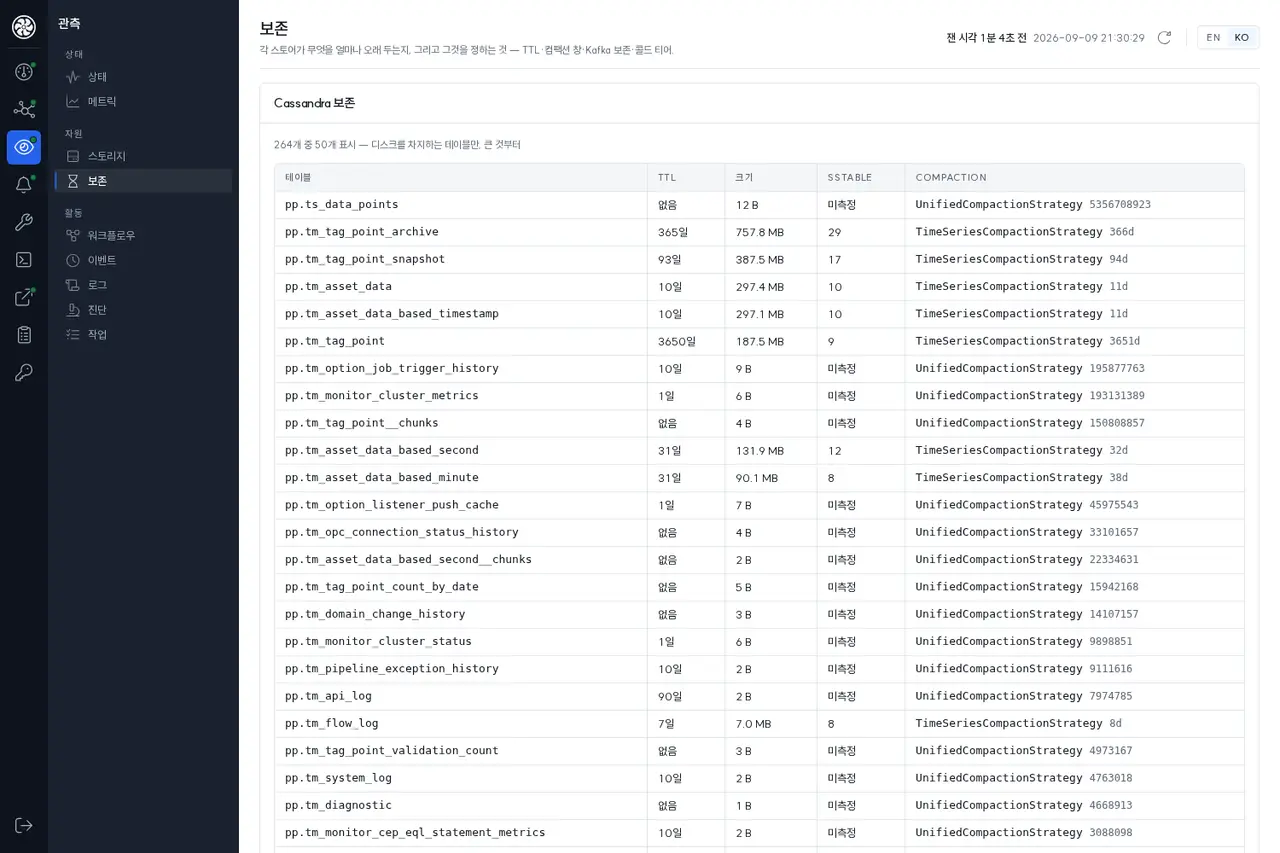
The TTL for pp.tm_tag_point appears as 3650 days. Instructions for changing values are in Data Retention Period.
Settings — «What changes if rendered now» and «Does my template differ from the image default».
Backup — Set list, schedules, and current executions.
Tools — Gathers other product web UIs into cards to be opened in new tabs.
Audit — Records who changed what in this console.
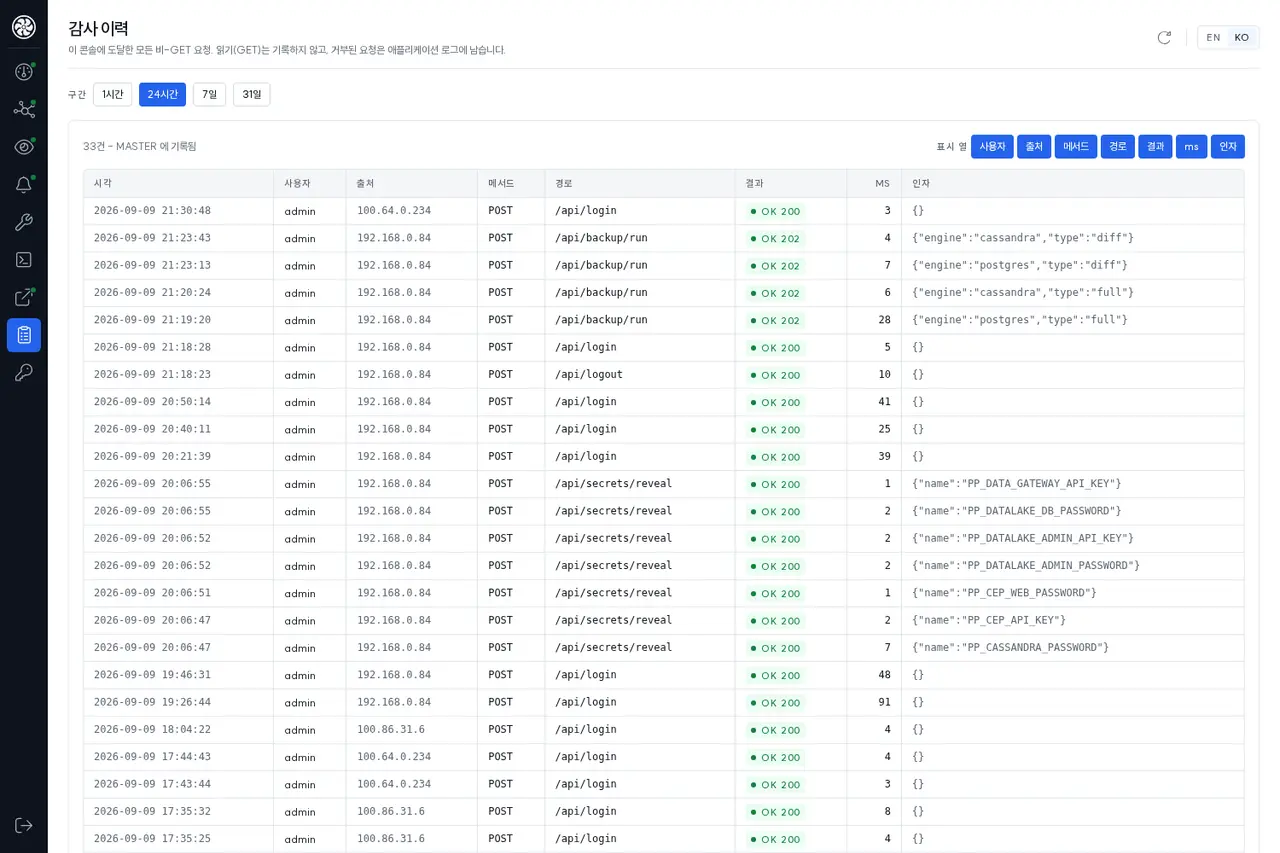
Screens that do not yet receive data are explicitly labeled as empty, stating that this does not mean «No Anomaly». Do not interpret a blank screen as healthy.
Four Screens of the Observation Group
While the «Major Screens» above address «What is wrong?», the four screens in the Observation group answer «Why?». All are accessed via the Observation → Status / Resource / Activity sidebar.
Metrics — Measurement History for a Single Component
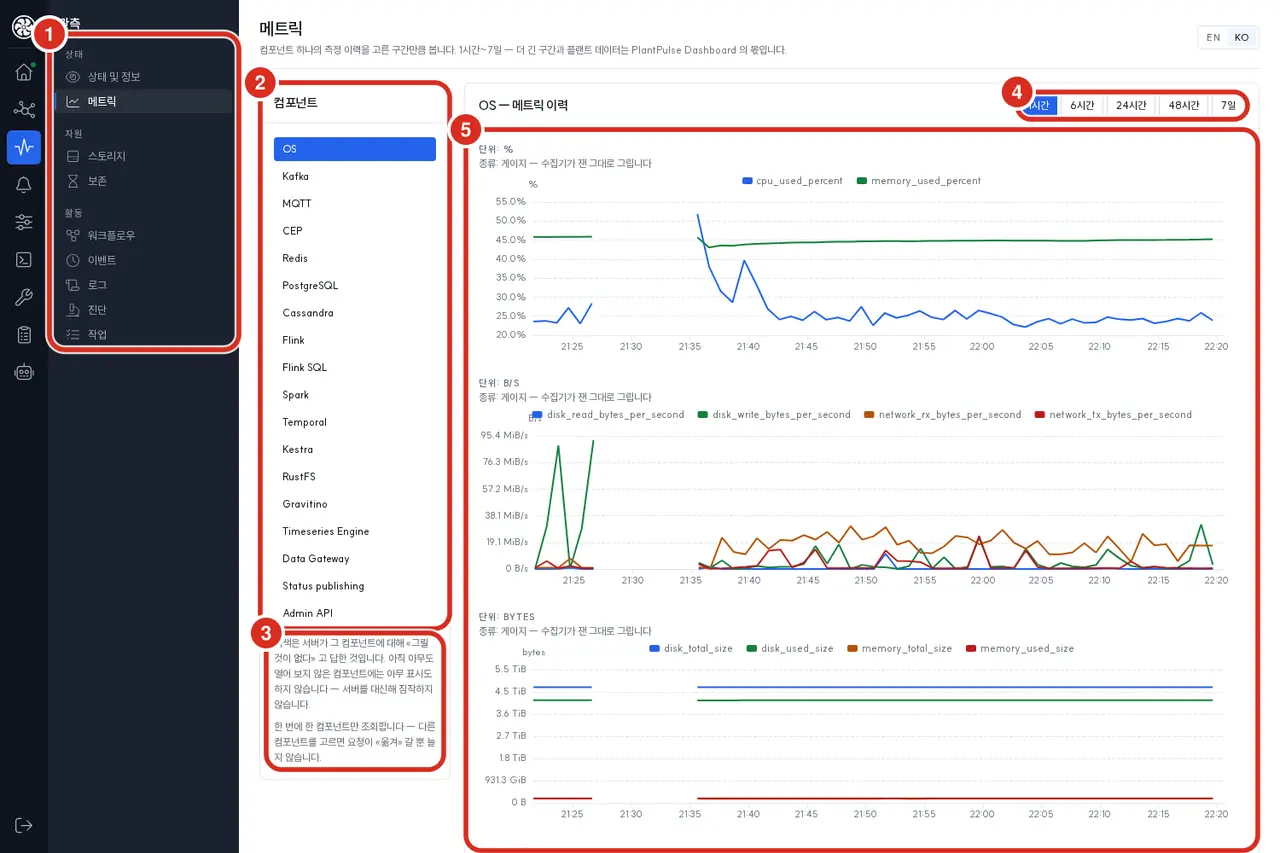
| No. | Area | Function |
|---|---|---|
| ① | Sidebar | Observation group screens — Status & Info, Metrics / Storage, Retention / Workflow, Event, Log, Diagnostics, Job |
| ② | Left | Component List — Select a component |
| ③ | Below List | Meaning of greyed-out components and notice that only one component is queried at a time |
| ④ | Top Right | Interval — 1h, 6h, 24h, 48h, 7d |
| ⑤ | Main | Charts grouped by unit (%, B/S, BYTES, LOAD …) |
The dashboard is a classification screen read without selecting any specific item, so it does not have intervals longer than a day. Conversely, this screen is for diving deep into one component and one interval.
Intervals longer than 7 days and «Plant Data» (non-data lake data) are the responsibility of the PlantPulse Dashboard. The absence of an «Open in PlantPulse Dashboard» link is intentional — links to unverified dashboards are worse than no links.
A component is greyed out only when a response was received for that component and the response was «Not Collected». Components that have not been opened yet receive no marking — guessing would create another «fabricated assessment».
Only one component is queried at a time. Selecting another component shifts the request rather than increasing the load.
Storage — Disk Contents and Retention
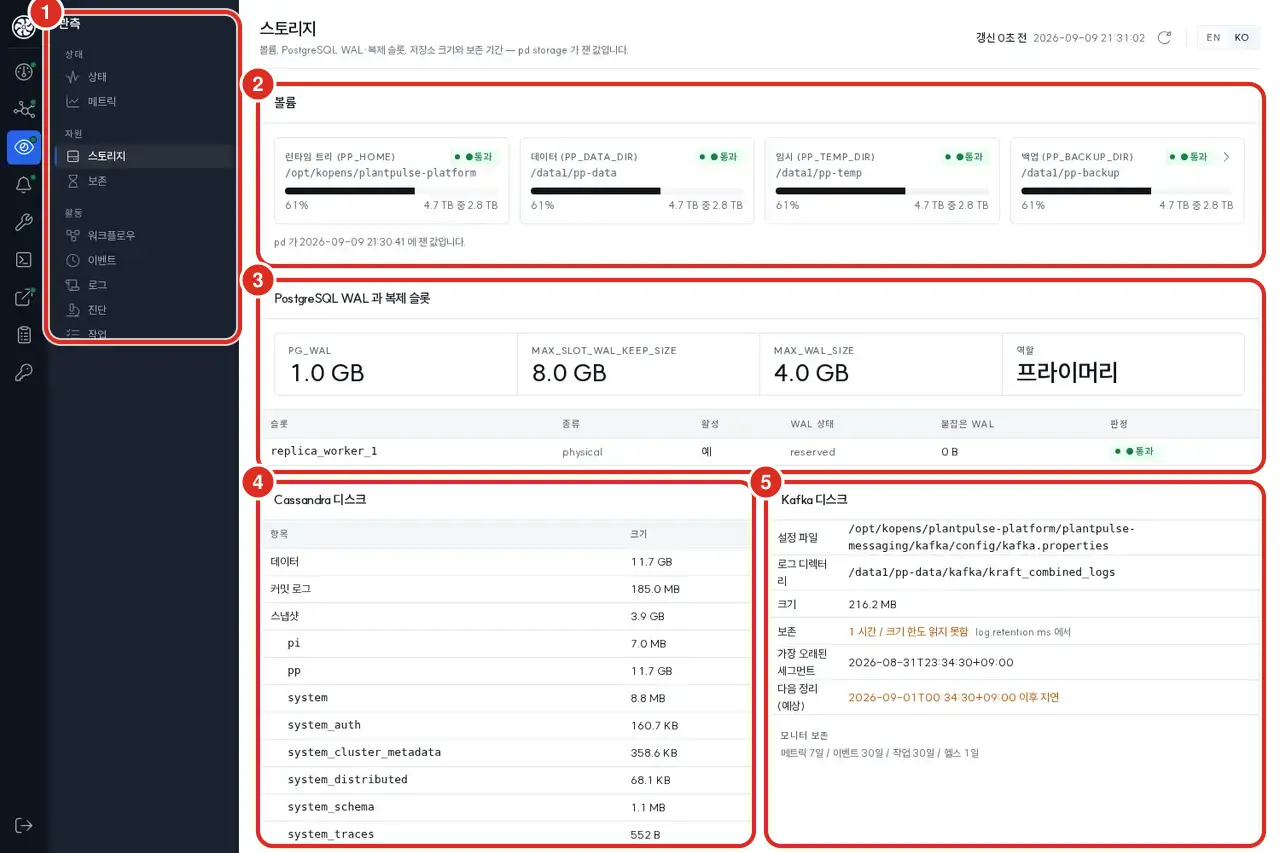
| No. | Area | Function |
|---|---|---|
| ① | Sidebar | Resource section — Storage, Retention |
| ② | Top | Volume — Utilization and assessment for Runtime Tree, Data, Temporary, and Backup |
| ③ | Below | PostgreSQL WAL and Replication Slots — PG_WAL, MAX_SLOT_WAL_KEEP_SIZE, MAX_WAL_SIZE, Role, and slot table |
| ④ | Bottom Left | Aster TSDB Disk — Size by Data, Commit Log, Snapshot, and Keyspace |
| ⑤ | Bottom Right | Kafka Disk — Config file, log directory, size, retention, oldest segment, and next cleanup estimate |
On 2026-09-03, a real incident occurred where replication slot replica_worker_1 held 1.4 GB of WAL while inactive, and max_slot_wal_keep_size was -1 (unlimited). No screen in the product reported this; the only way for an operator to notice was when the disk became full.
Therefore, the screen sequence is: Volume (Is it filling?) → WAL·Slot (What is holding it?) → Storage Size and Retention (Will it decrease?). Monitor «Active» and «Held WAL» in the slot table together.
Events — Occurrences on This Node
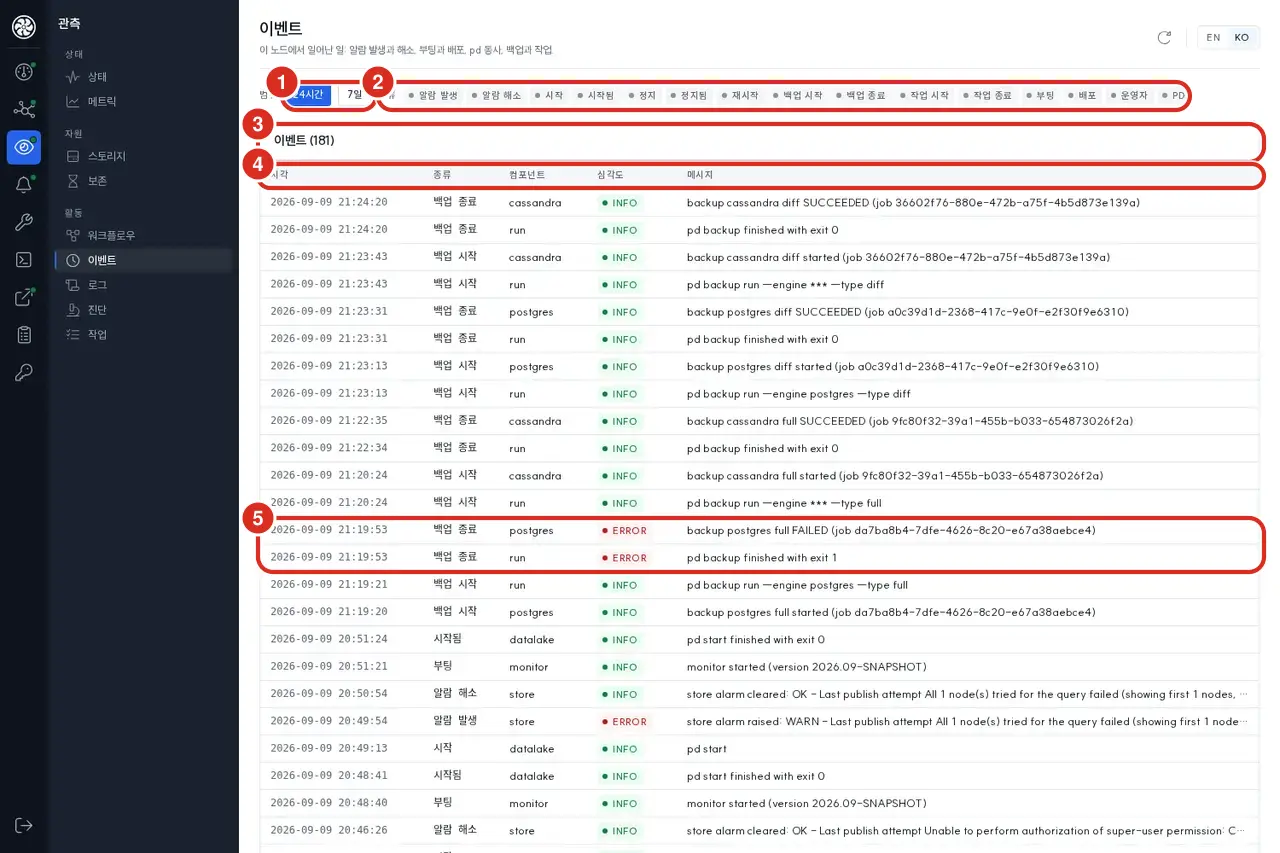
| No. | Area | Function |
|---|---|---|
| ① | Top | Range — 24h / 7d |
| ② | Side | Type Filter — Alarm Occurred/Resolved, Started/Starting, Stopped/Stopping, Restart, Backup Start/End, Job Start/End, Boot, Deploy, Operator, PD |
| ③ | Card Header | Events (N) — Count within the current range |
| ④ | Table Header | Time, Type, Component, Severity, Message |
| ⑤ | Body | Rows for failed backups, such as ERROR, are highlighted in red |
Audit records are attached below the same screen. During a failure, «What happened?» and «What did we do?» are the same question; separating them would require checking two different clocks. By appending them in the same time range, a restart at 01:25 and the operator who ordered it are aligned.
Nodes using memory as storage hold only the last few hundred events in RAM and lose them upon restart. The screen explicitly notifies you of this — do not interpret a partial history as complete.
Unreadable event stores are not rendered as «Quiet Night». Five distinct states are rendered: loading, events present, range empty, endpoint not yet provided, and unmeasured (with reason).
Alarms — Criteria and Notification
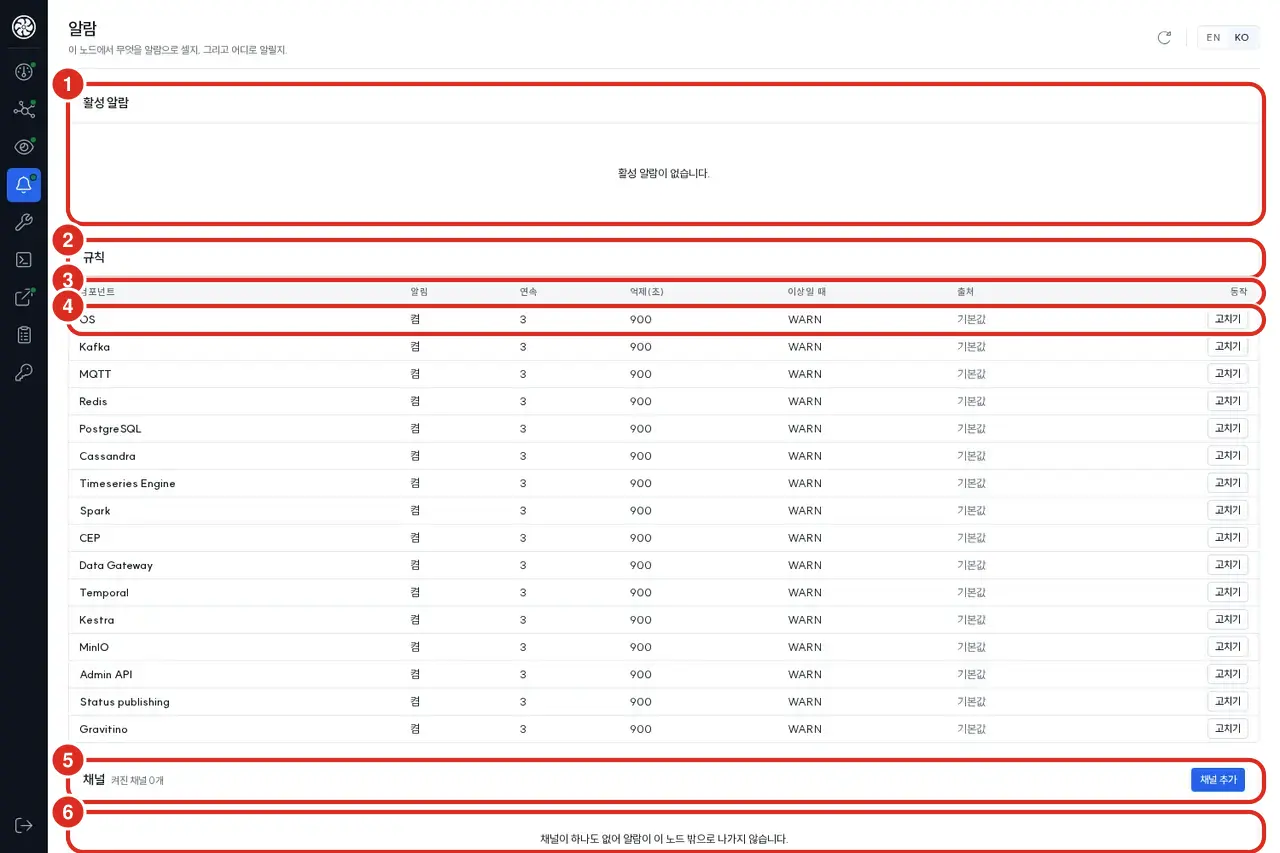
| No. | Area | Function |
|---|---|---|
| ① | Top | Active Alarms — Currently triggered alarms. Displays «No active alarms» if none |
| ② | Center | Rules Card |
| ③ | Table Header | Component, Notification, Consecutive, Suppression (sec), When Anomaly, Source, Action |
| ④ | Row | Rule for one component. Use [Edit] to change that row |
| ⑤ | Below | Channel Card + [Add Channel] — «N Channels On» |
| ⑥ | Bottom | States if no channels are present |
Three cards on one screen address one question asked three times: Is there an anomaly now? (Active), What is defined as an anomaly? (Rules), Who hears it? (Channels). Dividing these would lead users to overlook the potentially empty third state.
There are five reasons why an active alarm might not sound, and the screen describes each with distinct phrasing.
| Screen Text | Meaning |
|---|---|
| Muted | A human silenced the alarm |
| Rule is off | «Notification» in the rule table is off |
| Below minimum severity | Does not meet the «When Anomaly» threshold |
| In suppression period | Within the «Suppression (sec)» window |
| No channel | No destination to send the notification |
The header also displays «N of them are silent». These are not lumped into a single «Mute» badge because the required response for each of the five cases differs.
Additionally, unreadable settings are not rendered as «No settings». The screen displays the server's response store: "NA" and the reason. In nodes where settings cannot be saved, the edit button disappears entirely. Grayed-out buttons that can be clicked are avoided because they might falsely indicate a successful save without actually changing anything.
Four Screens of the Activity Group — What Happened?
Jobs — A Single Ledger for Long-Running Tasks
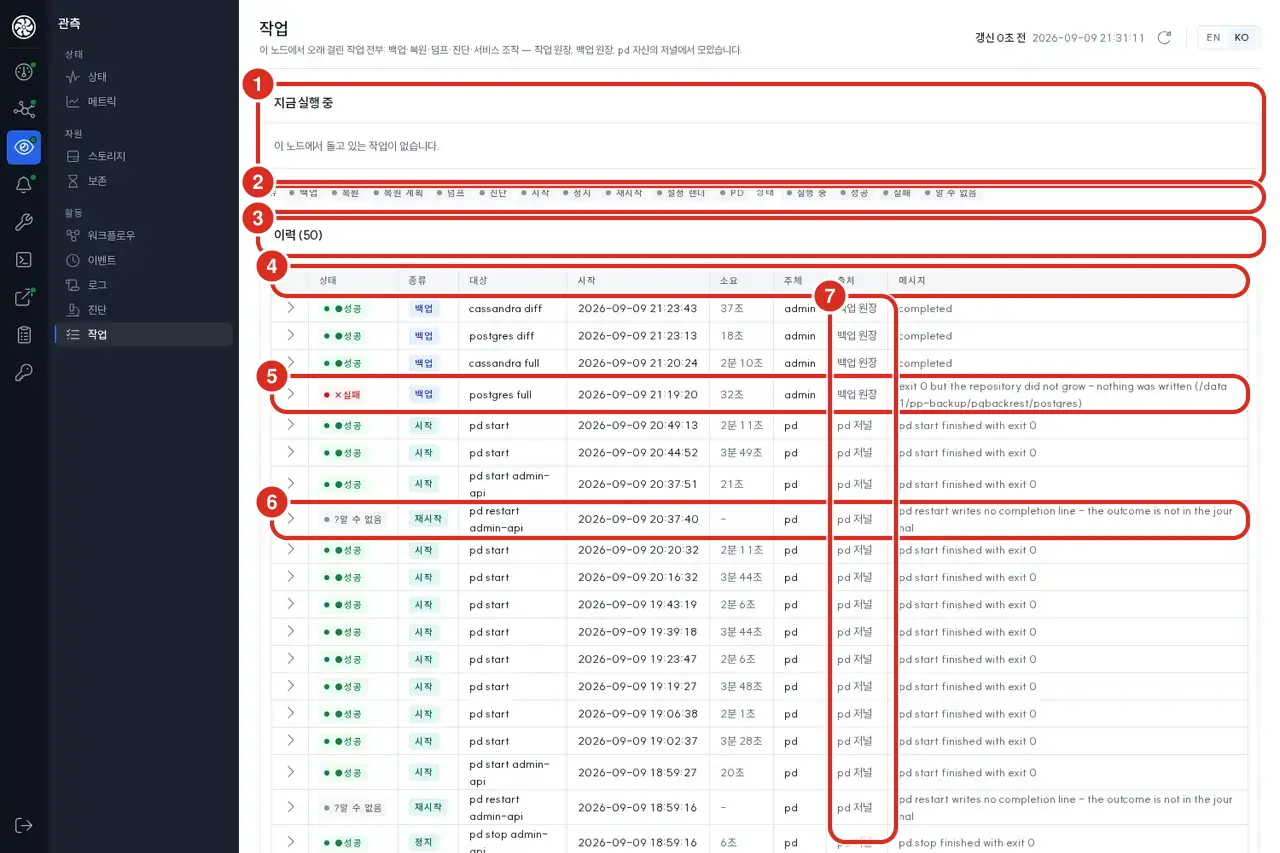
| No. | Area | Function |
|---|---|---|
| ① | Top | Currently Running — Explicitly states if none |
| ② | Below | Type · Status Filter — Backup, Recovery, Recovery Plan, Dump, Diagnostics, Start, Stop, Restart, Config Render, PD / Running, Success, Failure, Unknown |
| ③ | Card Header | History (N) |
| ④ | Table Header | Status, Type, Target, Start, Duration, Subject, Source, Message |
| ⑤ | Failure Row | Failure and reason on one line — e.g., «Exit 0 but storage did not grow — nothing written» |
| ⑥ | Unknown Row | «pd restart does not write completion lines — result not in journal» |
| ⑦ | Source Column | Backup Ledger / PD Journal — Which ledger the line originated from |
Backups, recoveries, dumps, pd doctor, and service operations all take several minutes, but their records were stored in different locations: the console's job ledger, the backup ledger, and the PD's own journal for executions not started via browser. Each screen showed only its own slice, so «What ran on this box today and did it succeed?» could only be answered via audit logs. However, audit logs record HTTP calls, not results.
«Unknown» is rendered as a separate result. For example, pd restart does not leave a completion line, meaning the result is not in the journal — painting this as success or failure would be inaccurate.
No tasks are started, canceled, or retried here. Those actions are located on screens with explicit confirmation and impact scopes (Backup, Diagnostics). The absence of a cancel button is because the server lacks an endpoint to cancel execution.
Logs — Logs «Present» on This Node
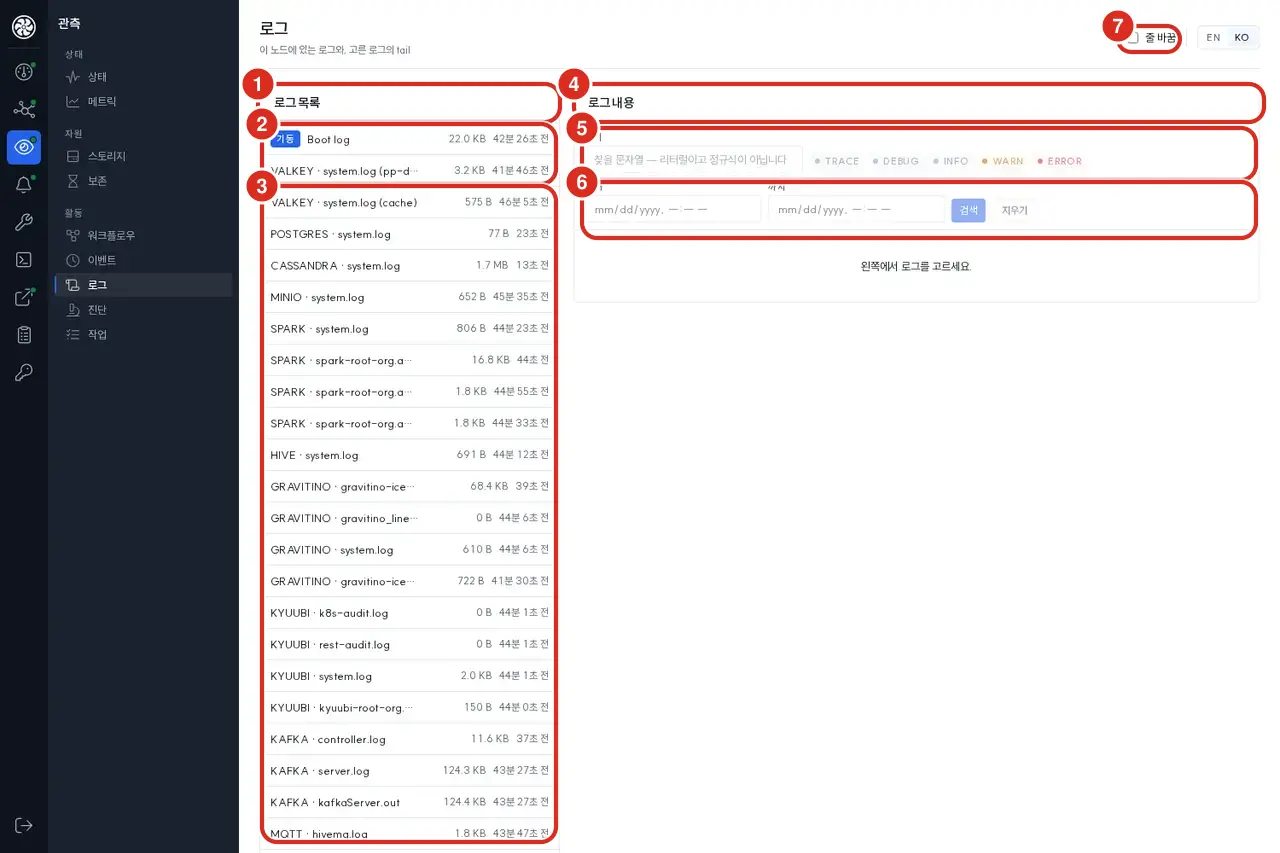
| No. | Area | Function |
|---|---|---|
| ① | Left Header | Log List |
| ② | First Line | Boot log with Startup badge |
| ③ | List | Component, Filename, Size, Last Updated |
| ④ | Right Header | Log Content |
| ⑤ | Search | String — Literal, not regex · Level chips (TRACE, DEBUG, INFO, WARN, ERROR) |
| ⑥ | Period | From ~ To · [Search] · [Clear] |
| ⑦ | Top Right | Line Wrap toggle |
The client does not specify the path. It sends an ID issued by the server, and the server manages the path — there are no parameters like ?path= that could be used for path traversal.
Log content is rendered as plain text only. Since a log line could contain <script>, and the log viewer is a hole in the operations console, HTML execution is blocked.
There are three results, not two: read / server could not query pd / declared but file missing. The latter two are rendered as unmeasured, not as «No logs on this node» or «Empty file».
Only files declared by pd logs --list appear in the list. Logs for app containers (Server, Batch, Warehouse) are not here — use the host's logs.sh.
Diagnostics — Measured by pd doctor
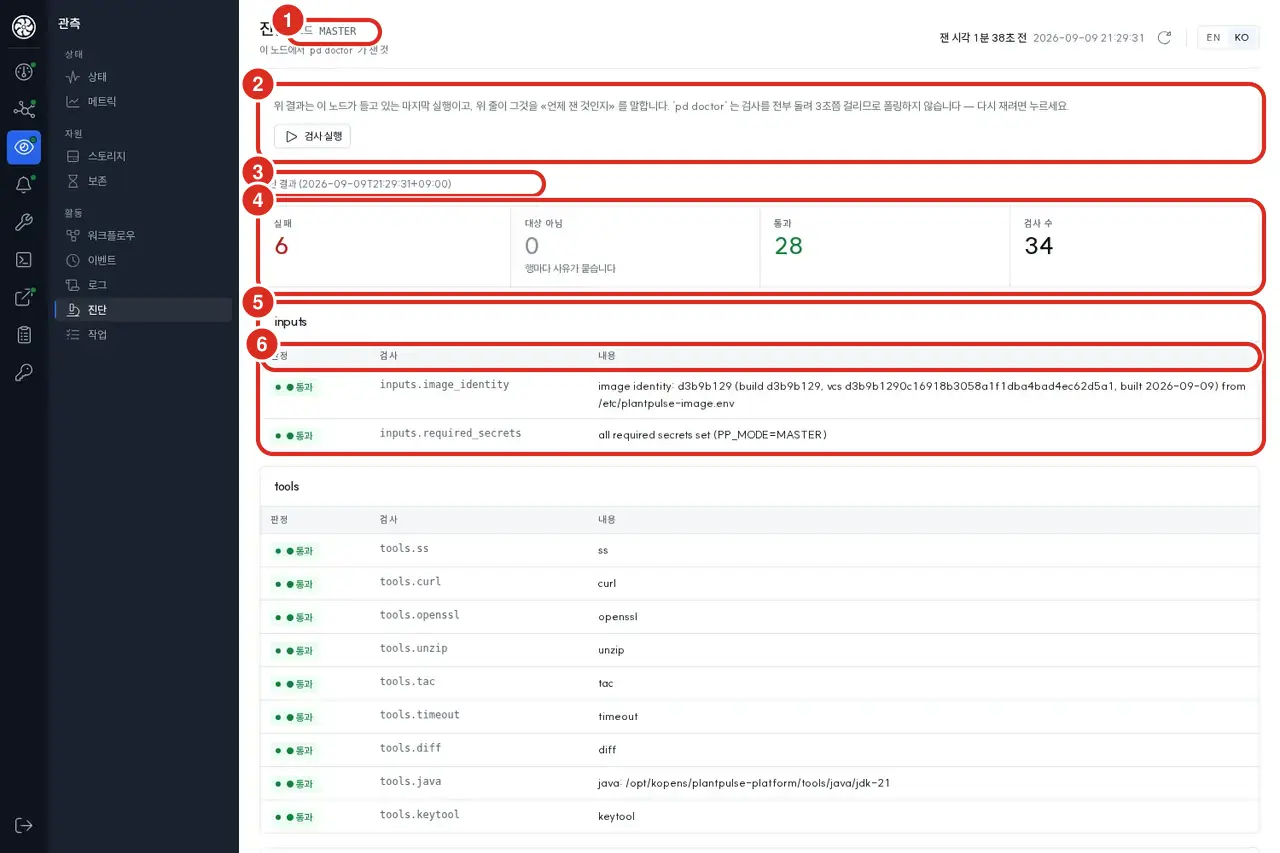
| No. | Area | Function |
|---|---|---|
| ① | Next to Title | Mode — MASTER / Worker |
| ② | Guide | «Last Execution» timestamp and [Execute Test] button |
| ③ | Below | Diagnostic Results (Measurement Time) |
| ④ | Summary | Failure · Not Applicable · Pass · Test Count |
| ⑤ | Group Card | Divided by groups: inputs, tools, … |
| ⑥ | Table Header | Assessment, Test, Content |
Since pd doctor takes about 3 seconds to run all tests, it is not executed periodically. The screen shows the last execution held by the node; the time in ③ indicates when it was measured. To measure again, click [Execute Test] — only one runs at a time; if «busy» appears, retry shortly.
There are five distinct answers, rendered differently: endpoint not yet present / session disconnected / request failed / command failed to run (reason required) / command ran but 0 tests.
The latter two are critical. A document state of na is not «All Passed» — it means nothing was measured, and a reason must be attached. An empty test list is a separate third case. Rendering either as a blank panel would lead an operator to read «No Anomaly» on a screen that measured nothing.
«Not Applicable» items include a reason for every row, as guided by the screen.
Worker — Commands are «Shown», Not Executed
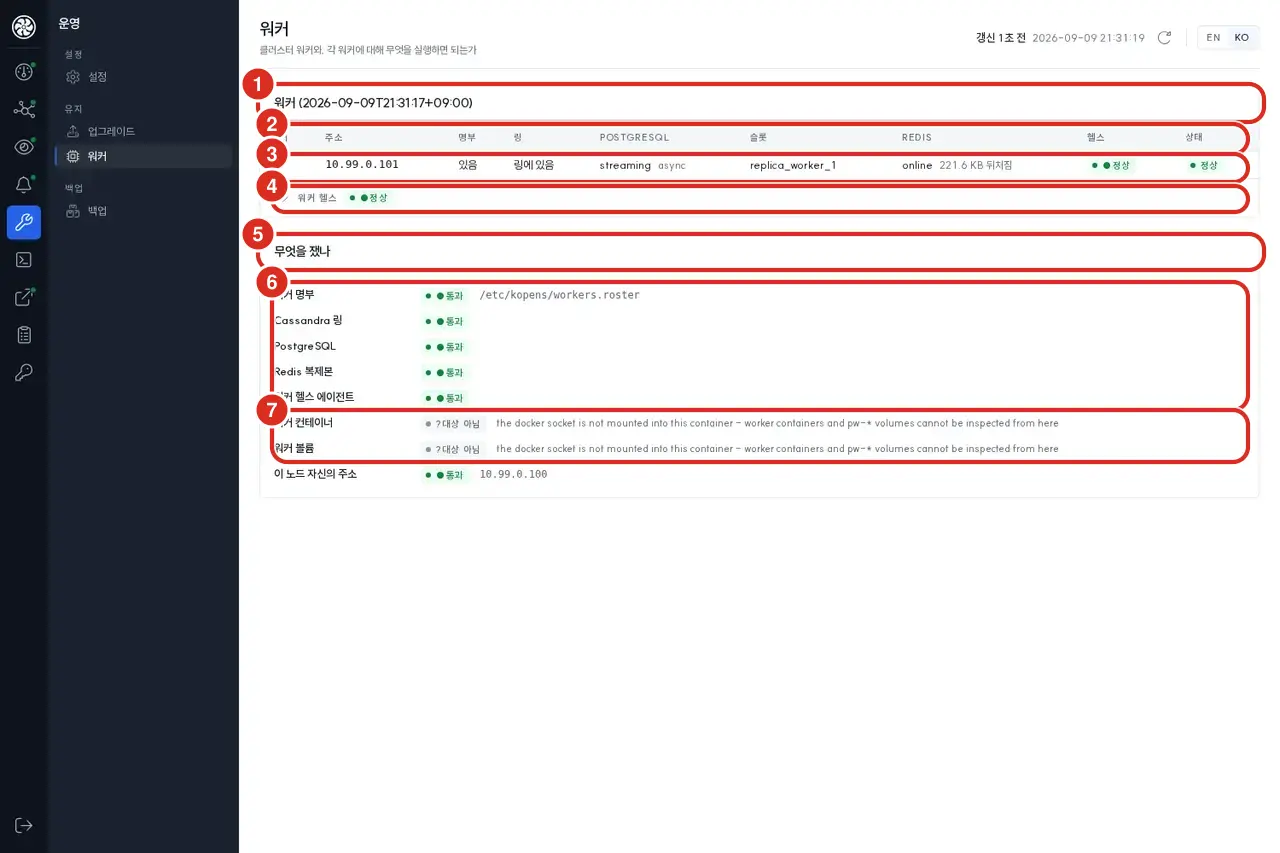
| No. | Area | Function |
|---|---|---|
| ① | Card Header | Worker (Measurement Time) |
| ② | Table Header | Worker, Address, Roster, Ring, POSTGRESQL, Slot, REDIS, Health, Status |
| ③ | Row | One worker. Replication slot name and lag amount on one line |
| ④ | Below | Worker Health — Expand for details |
| ⑤ | Next Card | What was measured? |
| ⑥ | Passed Items | Worker Roster (/etc/kopens/workers.roster), Aster TSDB Ring, PostgreSQL, Redis Replica, Worker Health Agent, This node's own address |
| ⑦ | Not Applicable | Worker Container, Worker Volume — Reasons are explicitly stated |
Commands to add or remove workers (worker-add.sh, worker-decommission.sh, worker-remove.sh) affect the Docker daemon, roster files, and compose overlays, all of which reside on the host. The API behind this screen runs inside the data lake container and has no Docker socket.
Therefore, four distinctions are maintained:
- No verb-shaped controls. The only button on the screen is Copy.
- All commands are prefixed with the title «Execute on Host» and the working directory.
- While a command is on screen, a read-only guide is always present, and the phrasing is from the server — ensuring the screen cannot contradict the API's claim.
- If any of the above are broken, the build fails.
If nothing needs changing, the command card does not appear — as seen in the figure.
This is the case for Worker Container and Worker Volume in the figure. The reasons are explicitly stated — it means the Docker socket is not mounted to this container and cannot be inspected here, not that there is no problem.
Operation, Command Screens and Credentials
These are primarily for making changes, so «What is not done» is more critical than «What is shown».
Upgrade — Report Only
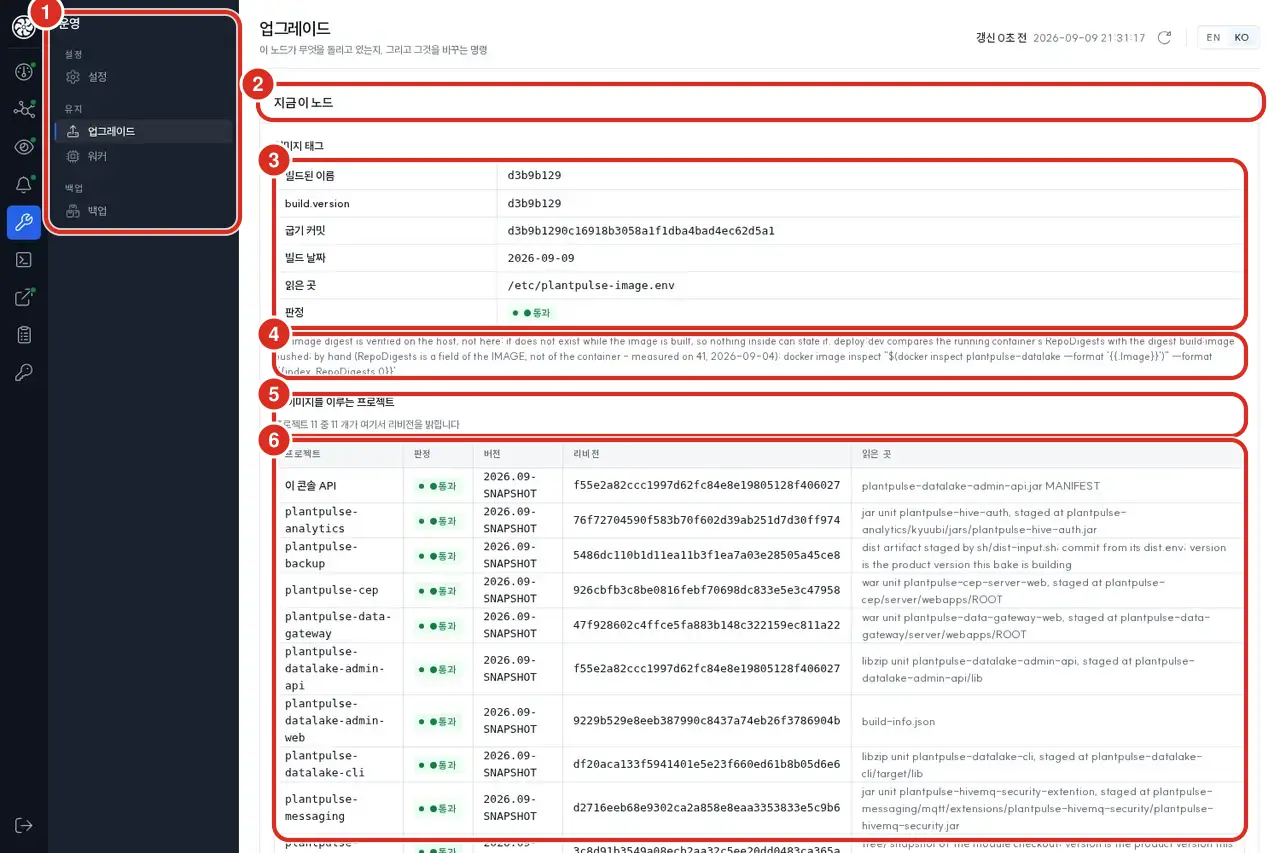
| No. | Area | Function |
|---|---|---|
| ① | Sidebar | Operation group — Settings / Upgrade, Worker / Backup |
| ② | Card Header | Current Node |
| ③ | Image Tag | Built name, build.version, Bake commit, Build date, Read from (/etc/plantpulse-image.env), Assessment |
| ④ | Below | Explanation that image digests are verified on the host — they cannot be known from within the image |
| ⑤ | Next Card | Projects constituting this image — «M of N declare revisions here» |
| ⑥ | Table | Project, Assessment, Version, Revision, Read from (MANIFEST, build-info.json, dist.env … varies by project) |
The only button that sends a request to the server is Pre-check, which is a read-only diagnostic (pd doctor). The only control attached to the command block is Copy; the button is named «Copy» in all languages — never «Execute» or «Apply».
Furthermore, phrases like «Up to date» are entirely absent from the bundle. This node cannot see its own image tag or query available versions. Reassuring phrases would be fabricated, and an operator reading them might stop searching — this is the most dangerous lie this screen could tell, so it was never implemented.
pd doctortakes about 3 seconds to measure and is not run periodically. Clicking the button starts it as a job and polls that job.
Command — Not a Shell
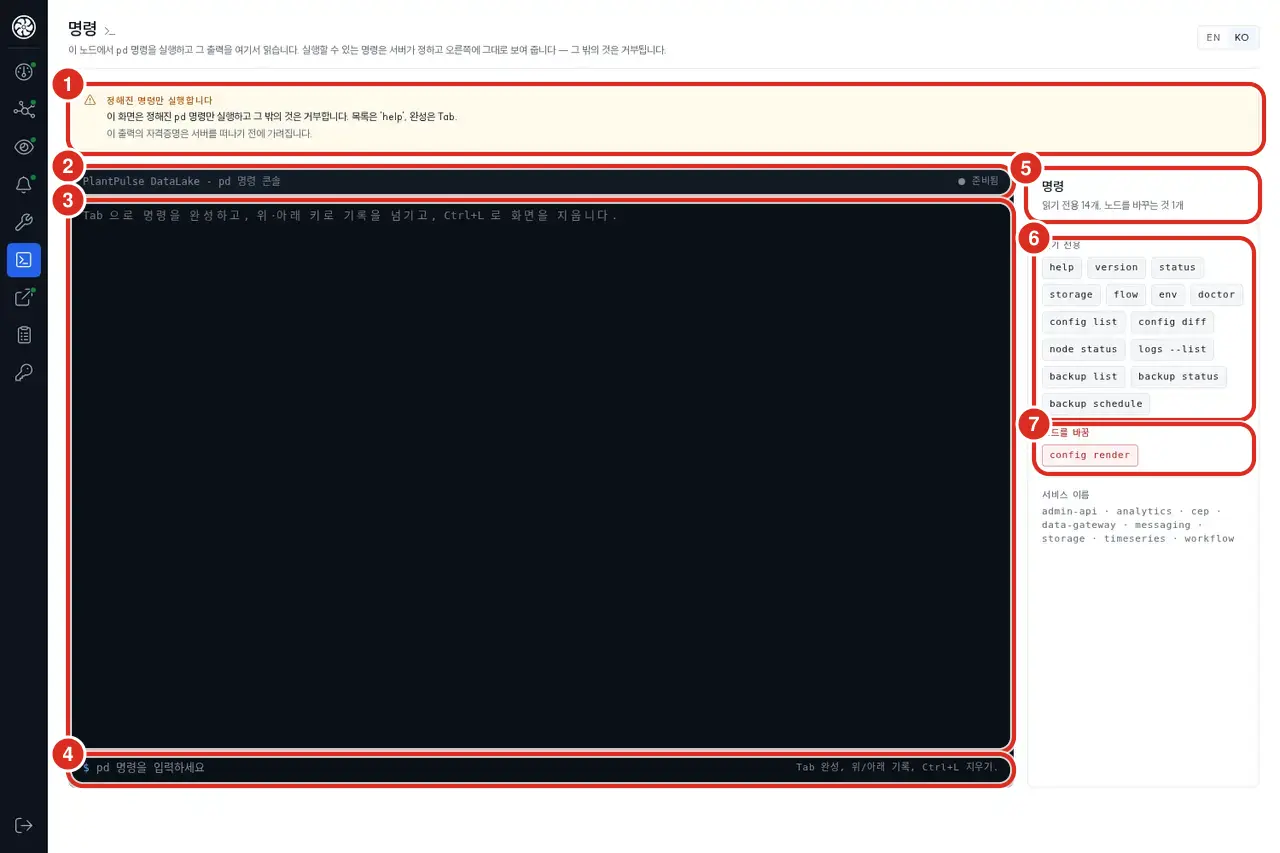
| No. | Area | Function |
|---|---|---|
| ① | Top | Permanent Guide — «Only predefined commands are executed» |
| ② | Terminal Header | Console name and status dot — Ready, Sending, Streaming, Disconnected |
| ③ | Body | Output (scrollback, ANSI color) |
| ④ | Bottom Line | Prompt — Tab completion, ↑↓ history, Ctrl+L clear |
| ⑤ | Right Header | «N read-only, M node-changing» |
| ⑥ | Right | Read-only verbs (help version status storage flow env doctor config list config diff node status logs --list backup list backup status backup schedule) |
| ⑦ | Below | Node-changing — separated by red borders (config render) |
It only mimics a terminal — history, scrollback, ANSI color, Tab completion. The only things that actually run are the pd allow-list enforced by the server.
Those who mistake this for a shell read rejections as «bugs». Therefore, the guide is a permanent screen element, not a single colored line in the scrollback — a warning pushed out of view by scrolling is no longer a warning.
The allow-list is fetched from the server every time the screen opens. No copies are kept in documentation or code — copies eventually diverge, and operators read the diverged version. If the list cannot be fetched, auto-completion is disabled and a notice is provided — it is not replaced by a guessed list.
Node-changing commands are executed only after confirmation. If rejected, the exact reason provided by the server is displayed — lumping it into «Failure» would make product safety mechanisms look like unknown errors.
As guided on the screen — «Credentials in this output are masked before leaving the server». The browser does not receive and hide them; they are never sent.
Credentials — Component Detail Cards
Credentials are viewed and changed on the page of the component that uses the value. There is no separate credentials screen. From the Status & Info screen, click a component row to enter details and find the Credentials card. If the server provides no credentials for that component, the card is not displayed.
| Column | Content |
|---|---|
| Item | What the value is — Admin account, internal API key, etc. |
| Environment Variable | Variable name |
| Account | Account name. Read-only |
| Password / Key | Masked by dots; click View Value to reveal only that item |
| Connection Check | Verified, Value mismatch, Unable to verify (Connection failed), Not a target for verification |
| Last Changed | Time of last modification |
| End | [Change], or reason for being unchangeable (Locked) |
Below the card, the three most recent change requests for this component are shown; failed requests can be [Retried]. The full history is in the Audit screen.
Sensitive values are not loaded in the list. Clicking View Value sends a separate request using only the variable name to retrieve a single value. This request is an POST and is recorded in the audit log; the value is not included in the address.
[Change] does not modify the value immediately. A panel shows the sequence of operations; after selecting Generate (32 chars) or Input Value, the console password and variable name must be re-entered to enter the queue.
- The new value is encrypted, stored, and the change is queued.
- The value is applied to locations that verify or read it within the data lake.
- All data lake services are restarted with the new value — causing several minutes of downtime. Other products using this value receive the new value when they recreate their containers.
- Each component is verified for connectivity with the new value. If a step fails, the request is marked as failed and retried with the same value.
The console has a single account without roles; any logged-in user can change any credential. Re-entering the password and variable name serves as the safety mechanism. Since the password and new value are transmitted, use 4950 (TLS).
Generated values are visible only once upon request and cannot be displayed again.
A blank value in the value column means it is truly empty. «Unable to read here» means this console could not read the value. Locked rows include a reason — account name not changed, calculated from another value, no current value to change, or no tool available for modification.
Procedures for changing values on the host are in Changing Passwords.
Tool Screen Cards
| Card | Address | Description |
|---|---|---|
| CEP | https://<호스트>:7401/ | EQL rules and matching events |
| PlantPulse Dashboard | https://<호스트>:3000/ | Time series data dashboards |
| Timeseries Engine | https://<호스트>:7801/ | Management screen for the engine itself, not the data |
| Spark | http://<호스트>:4440/ | Spark Master, Workers, and running applications |
| Temporal | http://<호스트>:8233/ | Workflow executions and history |
| Kestra | https://<호스트>:8380/ | Data pipelines — Flows, Executions, Logs |
| RustFS | http://<호스트>:9001/ | Object storage — Buckets, Objects, Access Keys |
| Data Gateway | https://<호스트>:5501/ | SQL Execution Console. Former SQL tool cards were merged into this (2026-09-07) |
Usage for three of these tools is documented separately: Data Gateway Console, Timeseries Analyzer, and CEP Console.
Screens with TLS twin ports link to the TLS side. Since this console is TLS (4950), it avoids providing plaintext addresses.
Console Query Frequency to pd
The console screens do not run pd for every request. The backend collection loop runs them one by one and caches the latest document; the screen reads this cache.
| Verb | Interval |
|---|---|
pd status --json · pd logs --list | 15s |
pd node status --json · pd storage --json | 30s |
pd flow --json · pd config diff --json · pd env --json | 60s |
pd doctor --json · pd retention --json · pd config diff --templates --json | 300s |
Based on these intervals, approximately 46 seconds of every 60 are spent running pd. Therefore, it is normal for pd status to occasionally be slow on the box where the console is running.
Health API
All screens rendered by the console are based on /api/*. The full list and schema are provided by the console reading /api/openapi.json and displaying it as an API Table.
curl -kfsS https://<server-ip>:4950/api/health | jq          # TLS
curl  -fsS  http://<server-ip>:4949/api/health | jq          # 평문 — 같은 API
docker exec plantpulse-datalake curl -kfsS https://127.0.0.1:4950/api/health | jq   # 컨테이너 안 — 어떤 구성에서도
curl -kfsS https://<server-ip>:4950/api/services | jq        # 서비스 목록과 상태
The host's status.sh, ops-check.sh, doctor.sh, and stack-verify-boot.sh all read this /api/health. /api/health responds without authentication; all other APIs require a login session or X-API-Key (log endpoint).
Prometheus Integration
Scrape https://<server-ip>:4950/metrics. Enable insecure_skip_verify for self-signed CAs. Connect as a data source from the bundled PlantPulse Dashboard (3000) or an external Grafana.
Common Issues
| Symptom | Cause | Action |
|---|---|---|
| Console won't open · «Not configured» | PP_DATALAKE_ADMIN_PASSWORD is empty | Web Login Accounts |
| 4949 works, 4950 doesn't | Certificate issue | Check browser warnings or replace certificate in Security Settings |
| Health endpoint no response | Data lake container anomaly | On host: status.sh → logs.sh plantpulse-datalake |
| Entire screen says «Not measured» | Polling stopped or old image | Check IMAGE_BUILT_AT of pd env. admin-api versions before 2026-09-04 often returned «Another job is already running» |
| Tool cards not rendered | Service not on this node (Worker) or polling no response | Use Master node console |
| Prometheus scrape 5xx | Backend module down | Check dependent modules via status.sh |
| Audit screen says «Unable to read» | Worker node | Normal — view on Master |
Related Documents
- Web Login Accounts
pdCLI — Original source for console data- System Monitoring — Readiness health checks for each web app
- Port and Service Management