Diagnostics
Table of Contents
- Overview
- Screen Layout
- Top Search Area
- Timeline
- Left — Diagnostic Log Table
- Right Statistics Panels (3)
- Export All (CSV)
- Standard Diagnostic Procedure for Incidents
- Common Diagnostic Message Patterns
- FAQ
- Related Screens
Overview
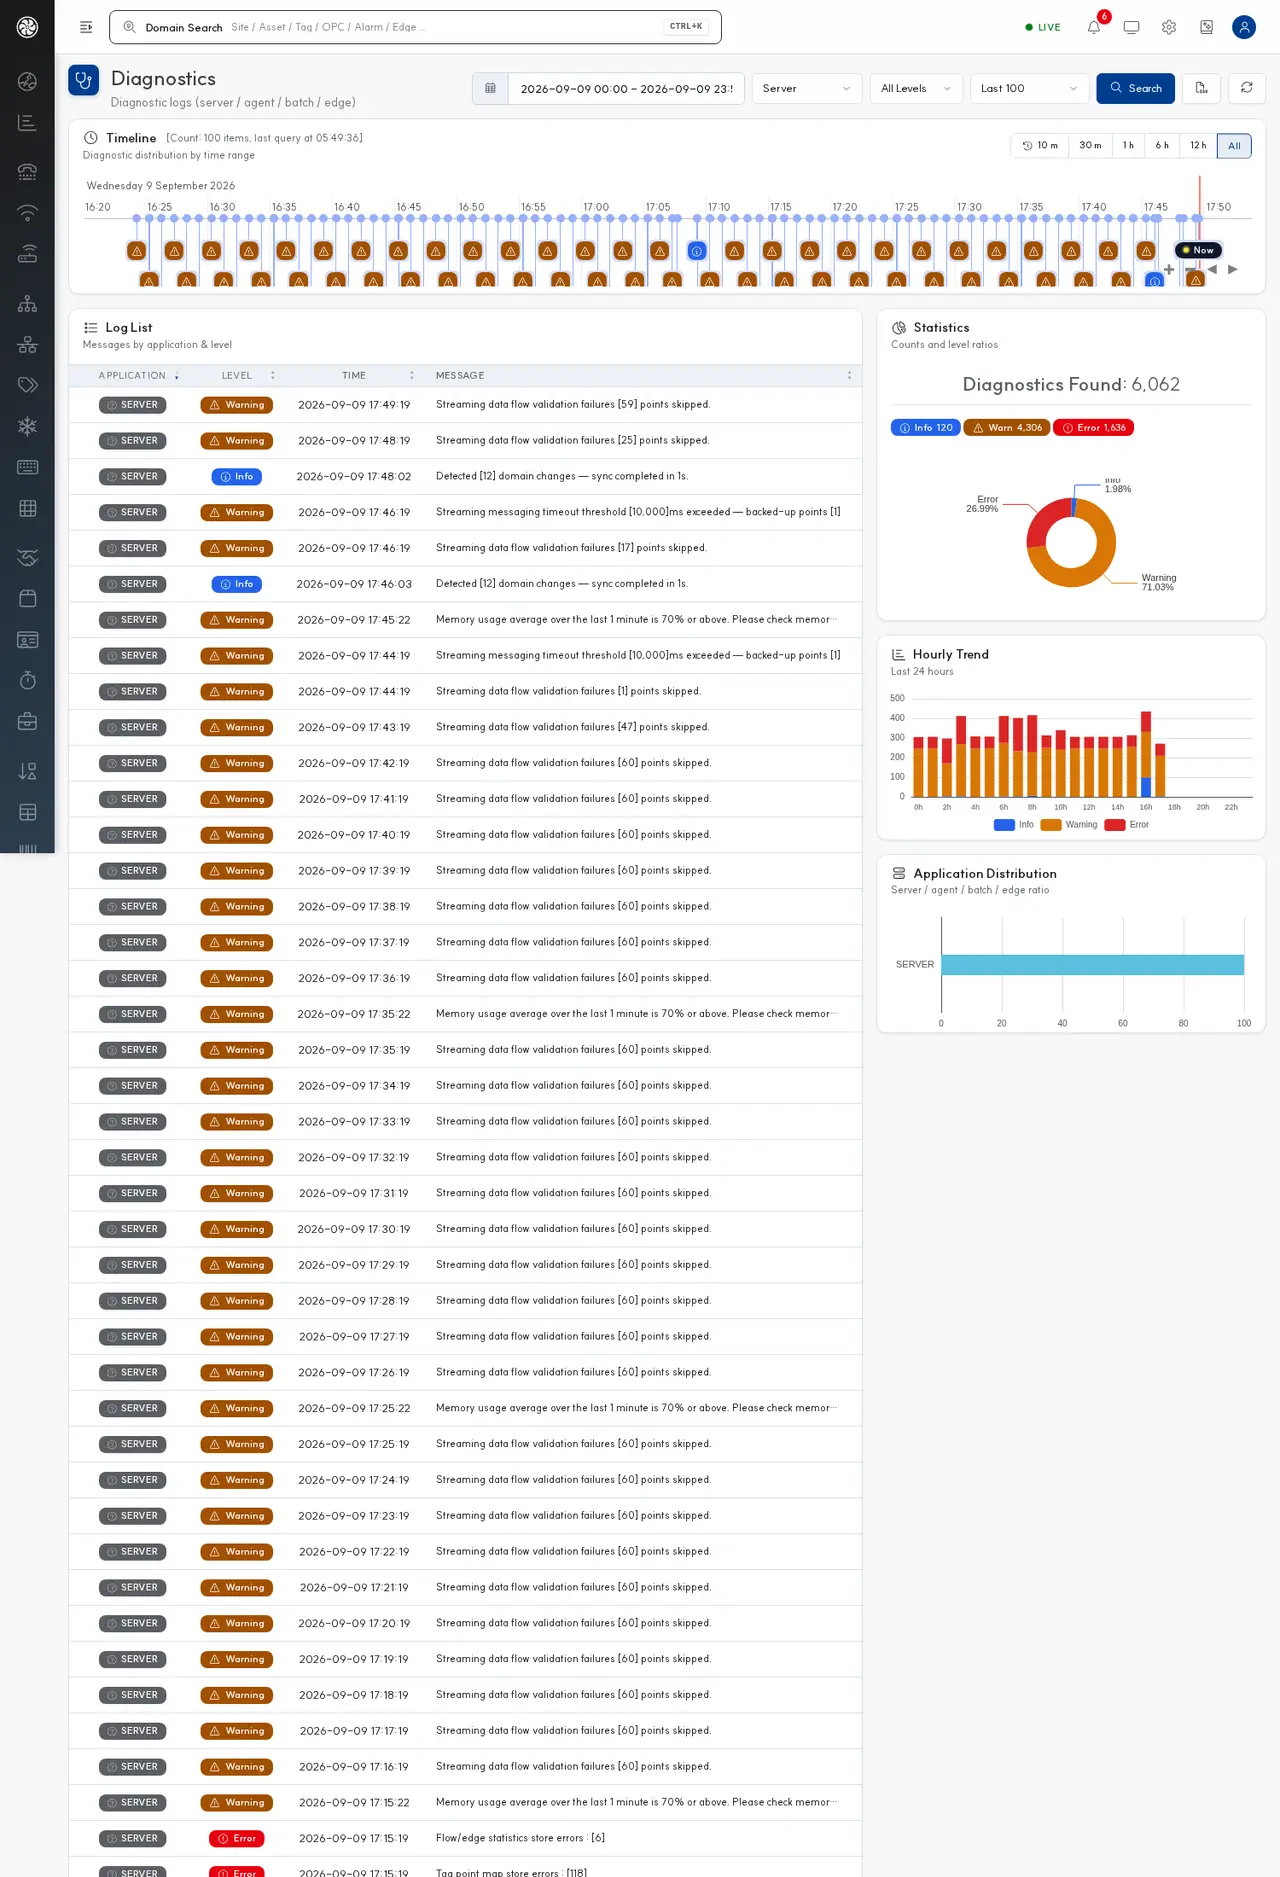
The Diagnostics screen brings together all diagnostic events (info, warning, and severe) generated inside the platform, presenting them in three views at once: a chronological timeline, a table, and statistical charts. This is typically the first screen a system administrator or operator opens when investigating the cause of an incident.
This screen combines the following functions into one:
- Timeline — see at a glance when and where events occurred
- Log table — exact timestamp, application, level, and message content
- Statistics panels — level ratio, time-of-day distribution, application distribution
Path: Left menu > System > Diagnostics (internal URL /diagnostic/index)
Screen Layout
┌───────────────────────────────────────────────────────────────────────────────┐
│ 🩺 진단                                                                          │
│   [기간]  [애플리케이션]  [레벨]  [건수]  [조회] [전체 출력] [↻]                  │ ← ① 검색 영역
├───────────────────────────────────────────────────────────────────────────────┤
│                          타임라인 + 빠른 시간 범위                                │ ← ② 타임라인
├──────────────────────────────────────────────────────────┬────────────────────┤
│                                                          │ 🥧 통계             │
│                  진단 로그 테이블                          │  검색된 진단 N건    │
│      애플리케이션 │ 레벨 │ 시간      │ 메세지              │  정보·경고·심각 뱃지│ ← ③
│      ...                                                 │  레벨 비율 차트     │
│                                                          ├────────────────────┤
│                                                          │ 📊 시간별 발생 추이 │
│                                                          ├────────────────────┤
│                                                          │ 🖥 애플리케이션별  │
│                                                          │   분포              │
└──────────────────────────────────────────────────────────┴────────────────────┘
| Area | Location | Displays |
|---|---|---|
| ① Search area | Top-right form | Period, application, level, display count + Search/Export All/Refresh |
| ② Timeline | Full width | Diagnostic markers over time + 6 quick time-range buttons |
| ③ Left | col-lg-8 | Diagnostic log table (fixed 4 columns) |
| ③ Right | col-lg-4 | 3 statistics panels (level ratio, time trend, application distribution) |
Top Search Area
The search form in the top-right of the page is laid out in a single row, with the following controls from left to right.
Input Fields and Buttons
| Control | Width | Type | Default/Options | Description |
|---|---|---|---|---|
Period (search_time) | 280px | Text input (center-aligned, bold) | Empty | Clicking opens a date/time range picker to set the start/end time. Passed via hidden fields search_date_from / search_date_to inside the form |
Application (app_name) | 120px | Dropdown | Server (SERVER), Agent (AGENT), Batch (BATCH), Edge Gateway (EDGE) | The module that issued the diagnostic |
Level (level) | 100px | Dropdown | All Levels, Info (INFO), Warning (WARN), Severe (ERROR) | Diagnostic level filter. Empty means all |
Message Search (message) | 250px (hidden) | Text input | Empty | Keyword search on message body. Hidden by default; visibility depends on the operating environment |
Count (limit) | 130px | Dropdown | 100, 200, 300, 500, 1,000 | Number of most recent diagnostics to display |
| Search | (auto) | Red button + 🔍 | — | Query diagnostic data using the conditions above |
| Export All | (auto) | Red button + 📄 | — | Bulk-download the diagnostic results matching the current conditions as a CSV file |
Refresh (realtime_icon) | (auto) | Red button + ↻ | — | Re-query with the same previous conditions — can be used as a dashboard |
Meaning of the Application Dropdown
| Value | Label | Description |
|---|---|---|
SERVER | Server | Web server, admin console, domain services |
AGENT | Agent | Data collection agent (pipeline) |
BATCH | Batch | Batch processing, aggregation, report generation |
EDGE | Edge Gateway | Edge device (gateway installed in the field) |
Meaning of the Level Dropdown
| Value | Label | Color | Meaning | Recommended Action |
|---|---|---|---|---|
| `` (empty) | All Levels | — | All levels | |
INFO | Info | Blue | Normal operation info, start/stop notifications, etc. | No action needed |
WARN | Warning | Orange | Potential issue, soft threshold exceeded | Check trend, inspect other modules at the same time |
ERROR | Severe | Red | Error, functional failure, exception | Identify cause immediately + contact system administrator |
Timeline
The diagnostic timeline is drawn in the panel below the search area.
| Item | Description |
|---|---|
| Header | 🕐 "Timeline" + small text search result summary on the right (result_txt) |
| Timeline body | alarm_timeline — horizontal axis is time, diagnostic entries shown as colored markers |
| Marker colors | Info = blue, Warning = orange, Severe = red |
| Hover | Hovering over a marker shows a tooltip with the time + message preview |
| Click | Automatically highlights the corresponding row in the left table |
Quick Time Range (Timeline range)
The 6 buttons on the right of the timeline header allow instant zoom.
| Button | data-range | Action |
|---|---|---|
| 10 min ago | 10M | Zoom to the last 10 minutes |
| 30 min ago | 30M | Zoom to the last 30 minutes |
| 1 hour ago | 1H | Zoom to the last 1 hour |
| 6 hours ago | 6H | Zoom to the last 6 hours |
| 12 hours ago | 12H | Zoom to the last 12 hours |
| Full period | ALL | Full search period (default active) |
The quick range buttons only apply zoom on top of the results already retrieved. To view a longer period, re-run the search using the Period field in the search area.
Left — Diagnostic Log Table
| 애플리케이션 | 레벨 | 시간              | 메세지                                |
|-------------|------|------------------|--------------------------------------|
| server      | ERROR| 2026-05-08 12:00 | Connection timeout to upstream...     |
| messaging   | WARN | 2026-05-08 11:55 | Buffer overflow threshold reached...  |
| Column | Width | Alignment | Displays |
|---|---|---|---|
| Application | 140px | Center | Name of the module that issued the diagnostic (e.g., server, agent, batch, edge) |
| Level | 80px | Center | Color badge — INFO (blue) / WARN (orange) / ERROR (red) |
| Time | 160px | Center | Time of occurrence (yyyy-MM-dd HH:mm:ss) |
| Message | Auto (remaining) | Left | Diagnostic body (truncated to fit the cell width since the table is table-layout: fixed — double-click the row or hover to view wrapped text) |
Row Interactions
- Hover: Highlights the row background
- Click: Synchronously highlights the corresponding marker on the timeline (left-right sync)
- Double-click/Popup: A modal displays the full message body and additional info such as the stack trace
Pagination at the Bottom of the Table
When there are many results, they are split into pages. The number of rows per page is determined by the Count dropdown (100/200/300/500/1,000) in the search area.
Right Statistics Panels (3)
Statistical visualization of the search results. All three show the same data as the left table, from different perspectives.
1. Statistics — Level Ratio (diag_level_chart)
┌────────────────────────────────┐
│  검색된 진단 : N 건             │  ← 큰 글씨 헤드라인
│  [정보 N] [경고 N] [심각 N]     │  ← 3색 뱃지
│                                │
│        도넛/막대 차트           │  ← diag_level_chart (150px 높이)
└────────────────────────────────┘
| Item | ID | Displays |
|---|---|---|
| Headline | — | Large text "Diagnostics found: N" |
| Total count found | diag_total_count | Integer |
| Info badge | diag_info_count | Count of Info level — blue background |
| Warning badge | diag_warn_count | Count of Warning level — orange background |
| Severe badge | diag_error_count | Count of Severe level — red background |
| Level ratio chart | diag_level_chart | Chart of Info/Warning/Severe ratio |
| Empty state message | diag_stats_empty | Displays "No data available." when there is no data |
2. Occurrence Trend Over Time (diag_hourly_chart)
| Item | Description |
|---|---|
| Header | 📊 "Occurrence Trend Over Time" |
| Chart | Hourly bar chart (170px height) — X axis is time, Y axis is diagnostic count |
| Bar segments | Info/Warning/Severe stacked by color |
Interpretation: A sudden spike in a bar for a particular hour indicates a large-scale anomaly at that time. Note the time and double-click the corresponding row in the left table for details.
3. Distribution by Application (diag_app_chart)
| Item | Description |
|---|---|
| Header | 🖥 "Distribution by Application" |
| Chart | Donut/bar chart (140px height) — diagnostic count by application |
Interpretation: If one application accounts for 70% or more of the total, it may indicate a failure concentrated in that module. Narrow the search using the Application dropdown in the search area, then check the left table.
Export All (CSV)
Clicking the Export All button in the search area downloads all diagnostics matching the current search conditions as a CSV file.
CSV Columns
| Column | Format |
|---|---|
| Application | Text |
| Level | Text (INFO/WARN/ERROR) |
| Time | Text (yyyy-MM-dd HH:mm:ss) |
| Message | Text (double quotes escaped) |
The CSV exports the full result set matching the search conditions, not just the rows visible on screen. It is not affected by the Count dropdown (most recent N entries), making it suitable for long-term analysis.
CSV Usage Tips
- Compress (.zip) when sending to the system administrator
- Import into an external analysis tool (spreadsheet/BI tool) for further analysis by module, time, or keyword
- Combine a week's worth of data to compare whether the same pattern repeats daily
Standard Diagnostic Procedure for Incidents
When an incident occurs, following this order helps identify the cause efficiently.
Step 1 — Narrow the Time Range
- Set the Period field to ±10 to ±30 minutes around the time of the incident
- Set Count to 1,000 (so nothing is missed)
Step 2 — Check Severe First
- Set the Level dropdown to Severe (ERROR) → click Search
- Check the message starting from the first row (most recent ERROR) in the left table
- Check the right Distribution by Application chart to see which module generated the most ERRORs
Step 3 — Check Warnings at the Same Time
- Change Level to Warning (WARN) and search the same period
- Check WARN messages that occurred 1–5 minutes before the ERROR — these usually provide clues to the ERROR
Step 4 — Narrow Down by Module
- Select the application with the most ERROR/WARN entries using the Application dropdown
- Reset Level to All Levels to review the module's full flow — a break in INFO messages can be a clue
Step 5 — Message Pattern
Review the message content in the left table. Determine whether the same message repeats (rule storm) or occurred only once (a single external state change).
Step 6 — Hand Off to System Administrator
If the operator cannot resolve the cause directly, use the Export All button to download the CSV and hand it to the system administrator. It's helpful to include the following in the report:
- Time of incident (time of first ERROR)
- Scope of impact (which site/module)
- Text of 1–3 ERROR messages
- The CSV file
Common Diagnostic Message Patterns
| Message Keyword | Meaning | Common Action |
|---|---|---|
Connection timeout | External service connection timeout | Check network status and whether the target service is running |
Out of memory / OOM | Out of memory | Check system resources, consider restart (system administrator) |
Disk space low | Insufficient disk space | Clean up old data or expand disk |
Authentication failed | Authentication failure | Check for expired/incorrect token or account info |
Buffer overflow | Processing queue full | Flatten load with pre-trigger filters or external I/O throttling |
Job already running | Duplicate job execution | Previous job not completed — check with system administrator |
Failed to parse | Message parsing failure | Review external system payload format |
Schema mismatch | DB/message schema mismatch | Check with system administrator (may occur right after deployment) |
Pipeline exception | Data pipeline exception | Also check the selected day detail chart in Daily Statistics |
Edge disconnect | Edge device disconnection | Check device status in Connection Management |
FAQ
Q. I don't see the Message Search (keyword) input field.
A. Message body search may be disabled depending on the operating environment settings (display:none). Contact your system administrator if you need it enabled.
Q. What is the retention period for diagnostic data?
A. The default is 7 days. If longer retention is needed, use Export All to load CSV into an external system, or use a diagnostic trigger (flow_on_diagnostic) in Flow to automatically feed an external log system.
Q. A huge number of ERRORs have accumulated, all with the same message. Can I ignore them? A. If the same ERROR repeats within a short time, it usually indicates a single cause storming — the count itself has little meaning. Focus on the first occurrence time and the message content.
Q. Can the Refresh button be changed to auto-refresh? A. The screen only supports explicit refresh. For operational monitoring requiring auto-refresh, click Refresh periodically at short intervals, or set up alert automation in Flow to receive a push notification when an ERROR occurs.
Q. The timeline markers are too densely packed. A. Lowering the Count dropdown to a smaller value (100–200) or narrowing Level to ERROR/WARN improves readability.
Q. All modules issued ERROR at the same time. A. This likely indicates a shared infrastructure (message channel/storage) failure. Also check the infrastructure/engine status in the Dashboard Health Rail.
Q. CSV download is taking a long time. A. The search conditions are likely too broad. Try narrowing the period to 24 hours or less, or limit it to a specific module.
Related Screens
- Dashboard — Preview recent diagnostics in the right health rail
- Daily Statistics — System diagnostic trends and exception type/code distribution
- Alarm — Domain alarm history
- Connection Management — Edge/OPC device status
- Flow — Automatically route diagnostics using
flow_on_diagnostictriggers