Flow
Table of Contents
Getting Started
Screen Guides
Message/Node Reference
- Message Structure · Payload Examples by Trigger · Node Catalog
- Triggers · Filters · Transforms
- Actions — Integration/Storage · Asset Event Publishing · Domain CRUD
- Edge · External Integration · Flow Control
- Detailed Node Options Reference · Writing Script Nodes · JS Runtime Specification · Memory-Safe Coding Patterns · Mobile Push Notification Channel · External Auth Token Auto-Renewal
Examples & Patterns
Operations
Production Operations
- Frequently Asked Questions (FAQ) · Operational Best Practices · Security & Sensitive Data Handling
- Flow Metrics and Alarms · Message Processing Semantics and Backpressure · What You See in Execution History
- Cluster/HA Behavior · End-to-End Trace · Graph Pattern Catalog · Flow Testing Best Practices
- Performance Limits and Tuning · Audit/History Tracking · New Flow Deployment Checklist · Deployment Strategies (Canary/Blue-Green/A·B) · Emergency Response Procedures
- Node Quick Configuration Reference · Flow REST API · Webhook Triggers · OPC/PLC Industrial Integration Patterns
- External System Integration Cookbook · Data Transformation Cookbook · Reusable Script Collection
Troubleshooting
Other
Overview
Flow is an automation menu that defines data integration with external systems (MES/ERP/SCADA, etc.) and automatic creation/update of domain objects (tags, equipment, work orders, workers, etc.) as a visual graph. Operators can design, deploy, and operate automation scenarios directly without coding.
You compose a data processing pipeline by dragging and dropping over 100 types of nodes onto the canvas and connecting them with wires.
Path: Left menu > Automation > Flow
Learning Roadmap — Recommended Entry Order by Role
This manual is a comprehensive guide of over 4,000 lines. It's more efficient to start with the section that matches your role and purpose.
👶 First-Time Users (Build Your First Flow Within an Hour)
- Core Concepts — 5 minutes
- First Steps — 5 minutes
- End-to-End Tutorial — 30 minutes (follow steps 1–10)
- Screen Layout + Edit Screen — 10 minutes
- Follow Example Flows 1·2·3 — 10 minutes
→ First flow deployment complete. Search for needed nodes afterward in the Node Catalog.
🧑🏭 Field Operators (Writing Automation Scenarios)
- Payload Examples by Trigger — understand real data structures
- Detailed Node Options Reference — master frequently used node options
- Data Transformation Cookbook — copy common transformation patterns
- Graph Pattern Catalog — choose a wiring pattern
- Example Flows (17 types) — reference finished examples by scenario
🛠 System Administrators (Operations, Tuning, Incident Response)
- Flow Metrics and Alarms — which indicators to watch
- What You See in Execution History — interpreting diagnostic logs
- Cluster/HA Behavior — understanding multi-node environments
- End-to-End Trace — tracing problem messages
- Performance Limits and Tuning + Emergency Response Procedures
🔌 Developers/Integration Engineers (External System Integration)
- External System Integration Cookbook — Slack/Teams/Jira/SAP examples
- Flow REST API — manipulate flows programmatically
- Webhook Triggers — trigger flows externally
- OPC/PLC Industrial Integration Patterns — industrial field scenarios
- JS Runtime Specification + Reusable Script Collection
🔐 Security Personnel (Auditing, Authentication)
- Security & Sensitive Data Handling — storing credentials
- External Auth Token Auto-Renewal — operating OAuth2 tokens
- Permissions — actions available by role
- Audit/History Tracking — retaining change/execution history
📚 Quick Reference (For Users Already Familiar)
| Information You Need | Section |
|---|---|
| Node IDs and one-line descriptions | Node Catalog |
| Node option defaults | Detailed Node Options Reference |
| Message JSON examples | Payload Examples by Trigger |
| Ready-to-use scripts | Reusable Script Collection · Data Transformation Cookbook |
| API call curl | Flow REST API |
| Interpreting execution history | What You See in Execution History |
| Troubleshooting guide | Step-by-Step Debugging Guide · Common Issues |
| Quick options table | Node Quick Configuration Reference |
All section links are anchors within this same document. Keyword search with
Ctrl+Fis also effective.
Core Concepts
| Term | Description |
|---|---|
| Flow | A single automation workflow composed of a set of nodes and wires (relations). It's a directed graph with entry points, and its active status is controlled by the deploy/undeploy toggle |
| Node | The unit that receives a message, processes it, and passes it to the next node. Divided into 7 categories (Trigger · Filter · Transform · Action · External Integration · Flow Control · Edge) |
| Relation | The label on a wire going from a node's output to the next node. Nodes directly assign labels such as SUCCESS/FAILURE/TRUE/FALSE/MATCH/NO_MATCH/DEFAULT/THROTTLED/EXHAUSTED to branch. All labels are standardized to uppercase |
| Message | The payload flowing inside a flow. Contains type (classification), originator (subject entity), data (body), metadata (context) |
| Trigger | The node that serves as the starting point of a flow. There are three types: domain events (tag points, alarms, asset events, etc.), external entry (webhook, MQTT, external DB), and time (schedule) |
First Steps
You can get familiar with Flow fastest through the following 4 steps.
- On the list screen, click the
새 플로우button to create an empty flow (just enter a name and description). - On the edit screen, drag a trigger node (e.g.,
flow_on_tag_alarm) from the palette on the left → filter → action (e.g.,flow_send_email) in order and connect the nodes with wires. - Click each node to enter options in the inspector on the right, then click Save at the top right → Test Run to verify behavior once.
- Turn on the Deploy toggle at the top to have the flow run automatically whenever trigger events arrive, and check results in the live debug panel and execution history screen.
For automation scenario wiring patterns, please refer to Example Flows and Use Cases at a Glance in this document. For a step-by-step tutorial on building an actual flow from start to finish, follow along in the End-to-End Tutorial.
End-to-End Tutorial
This is a step-by-step tutorial for building one production-usable automation flow from start to finish. Scenario: When a motor's temperature exceeds 80°C, automatically issue an emergency maintenance work order and notify the responsible party by email.
Step 1 — Create a New Flow
- Click Automation > Flow in the left menu → open the list screen
- Click the New Flow button at the top right
- Enter the following information and click Confirm
| Item | Input Value |
|---|---|
| Name | 모터 과열 자동 정비 발행 |
| Description | [자동화] 모터 자산의 온도 80°C 초과 시 긴급 정비 작업지시 + 이메일. 담당: ops@example.com |
Once the flow is created, the edit screen with an empty canvas opens automatically.
Step 2 — Place a Trigger Node
Receive motor temperature data from an asset telemetry event.
- Expand the Trigger category in the left palette
- Drag the
flow_on_tag_pointnode onto the canvas - Click the node → enter the following options in the right inspector
| Option | Value |
|---|---|
| Display Name | 태그 포인트 인입 |
tag_id_pattern | MOTOR-*.TEMP |
Passing only the motor temperature tag through
tag_id_patternsignificantly reduces downstream processing volume. Other tags are handled as SKIPPED and not counted.
Step 3 — Threshold Filter
Add a script filter to pass through only messages exceeding 80°C.
- Drag
flow_script_filterfrom the Filter category - Connect a wire from the trigger node's output port to the new filter node's input port
- Enter the following in the inspector
| Option | Value |
|---|---|
| Display Name | 임계값 필터 (80°C 초과) |
language | JS |
script | data.value > 80 |
Step 4 — Domain Conversion (Tag → Asset)
Since it's natural to issue alarms/work orders at the asset level, convert the message's originator from the tag to the parent asset.
- Drag
flow_change_originatorfrom the Transform category - Connect a wire from the filter node's
TRUEoutput - Inspector:
| Option | Value |
|---|---|
| Display Name | Tag → Asset 변경 |
entity_type | Asset |
id_field | metadata.asset_id |
metadata.asset_idis automatically populated when tag points come in. If not present in the message, you can also extract the prefix part of the tag ID (e.g.,MOTOR-001.TEMP→MOTOR-001) using a script.
Step 5 — Issue Work Order
Automatically create an emergency maintenance work order.
- Drag
flow_create_work_orderfrom the Action — Domain CRUD category - Connect a wire from the transform node's
SUCCESSoutput - Inspector:
| Option | Value |
|---|---|
| Display Name | 긴급 정비 작업지시 생성 |
asset_id_field | originator.id |
order_name_field | (static value) 긴급 점검 — 모터 과열 |
master_id_field | (optional) data.master_id (auto-generated if not present) |
description_field | (static value) 자동 발행: 임계 온도 초과로 긴급 점검 필요 |
default_priority | HIGH |
Step 6 — Email Notification (Success Branch)
Notify the responsible person once the work order is issued successfully.
- Drag
flow_send_emailfrom the External category - Connect a wire from the work order node's
SUCCESSoutput - Inspector:
| Option | Value |
|---|---|
| Display Name | 정비 담당자 이메일 |
to | ops@example.com |
subject_template | [과열 정비] ${originator.id} 작업지시 ${data.work_order_id} |
body_template | 자산 ${originator.id} 의 온도가 ${data.value}°C 로 상승하여 자동으로 긴급 정비가 발행되었습니다.\n작업지시 ID: ${data.work_order_id} |
Step 7 — Handle the Failure Branch
The work order issuance itself may fail (e.g., asset removed or permission issue). Send an immediate push notification to operators.
- Drag
flow_send_pushfrom External - Connect a wire from the work order node's
FAILUREoutput - Inspector:
| Option | Value |
|---|---|
title | 자동화 실패 |
body_template | ${originator.id} 정비 자동 발행 실패: ${data.error} |
Step 8 — Save and Test Run
- Click the Save button at the top right. An automatic snapshot is stored, allowing later rollback.
- Click the Test Run button at the top right → enter the following in the JSON editor → Publish
{
  "type": "POST_TELEMETRY",
  "originator": { "entity_type": "Tag", "id": "MOTOR-001.TEMP" },
  "data":     { "value": 92.5 },
  "metadata": { "ts": 1746247200000, "tag_id": "MOTOR-001.TEMP", "asset_id": "MOTOR-001" }
}
The dialog footer shows ✓ JSON OK (type=POST_TELEMETRY) → click Publish.
- Check the following in the live debug panel:
- Trigger node lights up green → message passed
- Filter node: branches to
TRUEsince92.5 > 80 - Transform node: originator changed to Asset/MOTOR-001
- Work order node: SUCCESS,
data.work_order_idautomatically assigned - Email node: send attempted
Step 9 — Verify and Deploy
- Check the work order screen to confirm the new work order was registered
- Confirm the email arrived normally (test environment's mailbox)
- Test once more with a message below 80°C (should be blocked at the filter):
{ "type": "POST_TELEMETRY", "originator": {"entity_type":"Tag","id":"MOTOR-001.TEMP"},
  "data": {"value": 70}, "metadata": {"asset_id":"MOTOR-001"} }
The filter node's branch is FALSE, subsequent nodes gray — normal.
- After verifying all branches, use Reset All Counters to reset the statistics window
- Turn ON the Deploy toggle at the top
Now, as soon as the motor temperature exceeds 80°C in the actual production environment, a maintenance work order is automatically issued and the responsible party is notified by email.
Step 10 — Operational Monitoring
It's safer to check the following for 5-10 minutes right after deployment.
| Location | Check Item |
|---|---|
| List screen | Whether the execution count for the flow's row is increasing at a normal rate (not runaway) |
| Live debug panel | Whether there are no node failures |
| Execution history screen | If there are failed messages, check the cause in NODE_ERROR |
| Received email | Whether notifications aren't going out at an unintended frequency |
Next Steps
To further develop this flow:
- Add Retry wiring — backoff retry on email/push send failure (Example 8 reference)
- Auto-adjust bands — auto-correct threshold with 6-hour average ± 3σ (Example 6)
- Downtime accumulation — accumulate overheating history into an asset attribute (Example 14)
- Quality line isolation — automatically stop the line if overheating occurs consecutively (Example 15)
Screen Layout
Flow is composed of the following three screens.
| Screen | Purpose |
|---|---|
| List | List/search/bulk deploy/import of registered flows |
| Edit | Place, connect, and configure nodes on the visual canvas |
| Execution History | View node-level execution logs and timeline |
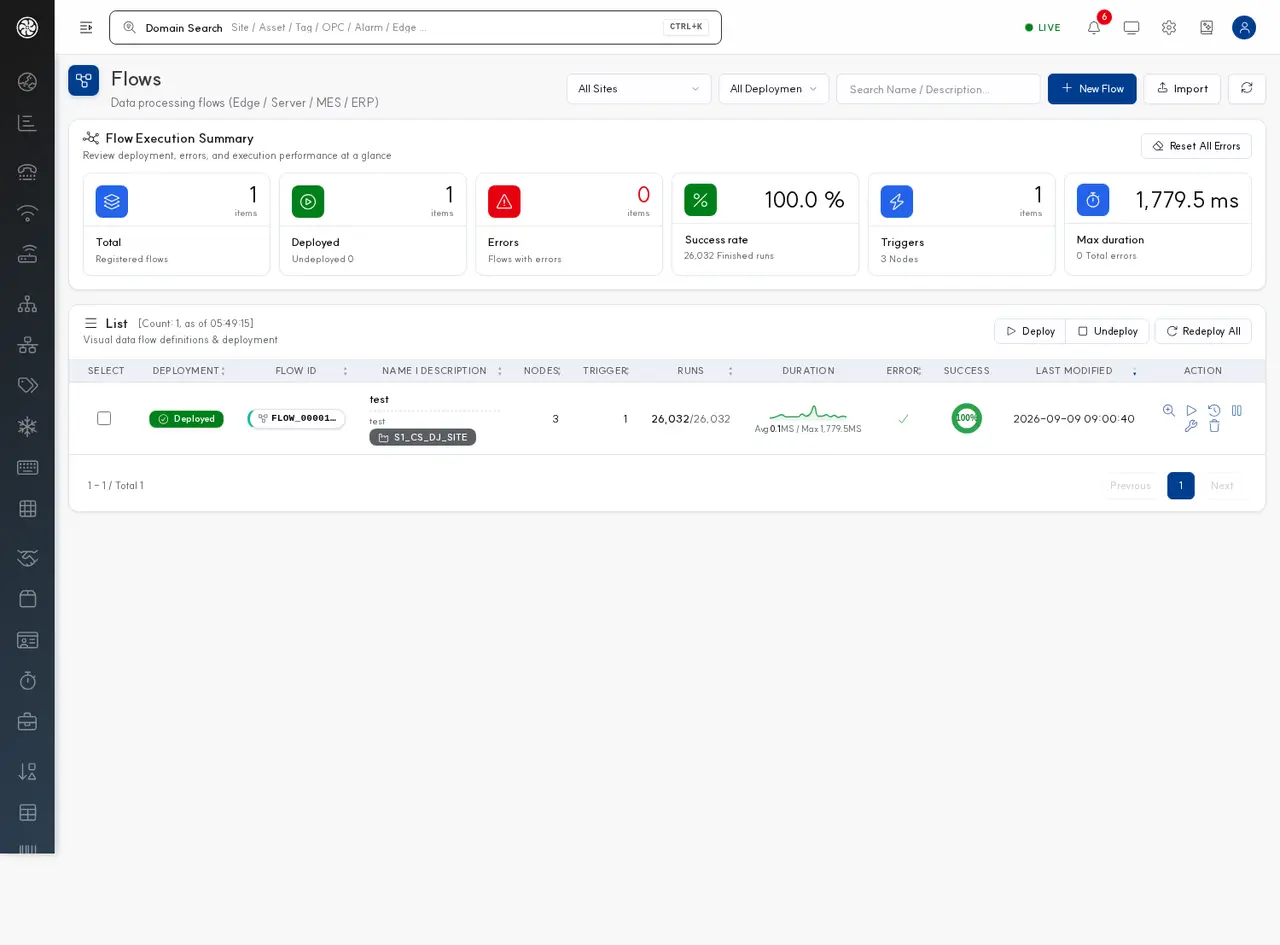
List Screen
Composed of the top search/creation area and the flow list table.
Top Toolbar
| Item | Description |
|---|---|
| Status Filter | 전체 / 배포 / 해제 |
| Name/Description Search | Filter flows by keyword |
| New Flow | Create an empty flow (enter name/description) |
| Import | Upload a JSON received from export to restore a flow |
| Redeploy All | Reload all activated flows at once |
| Refresh | Reload the list |
List Table
The list table is paginated in 25-row units, and each row also displays a processing trend sparkline and an error rate donut chart. Chart state is preserved across pages.
| Column | Description |
|---|---|
| Select | Checkbox for bulk deploy/undeploy |
| Status | 배포 / 해제 badge |
| Flow ID | Sequence ID in FLOW_NNNNN format |
| Name | Description | Meta info specified by the operator |
| Nodes | Number of nodes included |
| Trigger | Number of trigger nodes |
| Execution Count | Cumulative message processing count |
| Processing Time | Node average/recent processing time |
| Errors | Cumulative error count |
| Last Modified | Time of last graph save |
| Action | 편집 / 삭제 buttons |
Bulk Deploy/Undeploy
Deploys (activates) or undeploys (deactivates) selected flows in bulk. Only deployed flows receive trigger events.
Redeploy All
The Redeploy All button at the top reloads all activated flows. Use it in the following situations.
- Immediately after importing graphs in bulk from external sources
- When you want to re-register triggers with their own scheduler, such as schedule / external MQTT subscription / external DB polling
- When cache consistency issues are suspected during operation
Edit Screen (Visual Canvas)
Drag nodes from the palette on the left of the canvas to place them, then click and drag a node's output port to connect it to the next node.
Top Toolbar
| Button | Action |
|---|---|
| Name/Description | Edit the flow's meta information |
| Deploy/Undeploy | Immediately activate/deactivate the current flow |
| Export | Download the entire graph as a JSON file |
| Test Run | Inject an arbitrary JSON message to run once and check the result (see Using Test Run below) |
| Save | Save the current graph to the server. An automatic snapshot is stored on save, allowing later rollback |
If you attempt to save a graph without a trigger, a warning "It will only start via manual test run" is displayed. You can intentionally omit the trigger and use it as a manual-execution-only flow.
Using Test Run
Pressing the 테스트 실행 button opens a JSON editing dialog. Operators can compose a message themselves and publish it once, allowing verification of graph behavior without waiting for a trigger event.
| Item | Description |
|---|---|
| Editor | A JSON editor with line numbers and syntax highlighting. Freely compose the message body |
| Validation Display | Shows ✓ JSON OK (type=X) if the type required fields are present, ⚠ type 필수 if missing |
| Publish | Inject the message into the dispatcher via the 발행 button. Check the result in the live debug panel and execution history |
Default Template Example
{
  "type": "POST_TELEMETRY",
  "originator": { "entity_type": "Asset", "id": "MOTOR-001" },
  "data":     { "speed": 1500, "temp": 75.3 },
  "metadata": { "ts": 1746247200000, "site_id": "SITE-01" }
}
If you press Test Run while there are unsaved changes, an alert "The server will run the saved version" appears. Save first to verify your changes.
Left — Node Palette
Categories can be collapsed and expanded, and the search input allows for instant filtering.
| Category | Color | Number of Nodes |
|---|---|---|
| Trigger | Gray | 22 types |
| Filter | Blue | 6 types |
| Transform | Green | 8 types |
| Action — Integration/Storage/Asset Publishing/Command Invocation | Orange | 7 types |
| Action — Domain CRUD | Orange | 34 types |
| External | Purple | 9 types |
| Control | Gray | 7 types |
| Edge | Teal | 22 types |
Center — Canvas
| Tool | Shortcut/Operation | Action |
|---|---|---|
| Zoom In/Out | Ctrl/⌘ + / Ctrl/⌘ - · mouse wheel | Zoom the canvas |
| 100% | Ctrl/⌘ 0 | Reset zoom |
| Fit to Screen | Ctrl/⌘ 1 | Auto-fit so all nodes are visible |
| Delete Selected Node | Del / Backspace | Delete the selected node/wire |
| Canvas Panning | Left-click and drag on empty area | If you grab and drag the empty canvas background without clicking on a node, the entire canvas moves along |
A minimap is displayed at the bottom right of the canvas, and clicking on the minimap lets you jump to that position instantly.
💡 Panning tip: Dragging over a node moves the node — to move the canvas, be sure to grab an empty background area with no nodes/wires. Panning is faster than the minimap for large flows.
Right — Node Configuration
Clicking a node on the canvas displays the settings form for that node in the right inspector. Input fields are automatically generated based on the node type.
| Input Method | Description |
|---|---|
| Static Value | Uses the value entered directly in the form as-is |
*_field Dynamic Value | Extracts a value from a path in the message payload (e.g., data.tag_id, metadata.site_id). Falls back to a static value if none is present |
Script nodes (filter, transform, switch) can be edited directly with a code editor inside the inspector, and can also be expanded to a separate dialog for editing on a larger screen.
The code editor font is displayed using a readability-enhanced monospace font stack (Cascadia Code · JetBrains Mono · Consolas · Menlo priority), and Korean comments also align reliably.
Resetting Counters
Two reset buttons are shown as icons at the top right of the node settings panel. Hovering over each button shows a guiding tooltip.
| Icon Button | Action |
|---|---|
| 🩹 (bandage) — Reset Error Count | Resets only the cumulative error count for all nodes in this flow to 0 |
| 🔄 (rotating arrow) — Reset All Counters | Resets all processing, error, and processing time counters plus flow-level statistics to 0. Use it when you've finished operational verification and want to start statistics fresh |
Both buttons apply immediately without a confirmation dialog — only statistics are reset, with no effect on node behavior or message processing.
Right — Live Debug
The live debug panel is displayed below the inspector.
| Item | Description |
|---|---|
| Refresh interval | 2 seconds |
| Level color | Left border shows INFO (blue) / WARN (yellow) / ERROR (red) |
| Displayed information | Node display name · processing time (ms) · message preview |
| Pause | Pause updates with the toggle at the top right of the panel |
| Clear | Clear accumulated debug entries from the screen only |
A small indicator light is displayed at the top right of each node on the canvas.
| Color | Meaning |
|---|---|
| Gray | Waiting — no message received |
| Green | Message passing through |
| Red | Error occurred during processing |
The processing time is displayed at the bottom right of the node in the 평균 X · 최근 Y format.
Message Structure
A message flowing inside a flow consists of the following 4 areas.
{
  "type": "POST_TELEMETRY",
  "originator": {
    "entity_type": "Asset",
    "id": "MOTOR-001"
  },
  "data": { "speed": 1500, "temp": 75.3 },
  "metadata": {
    "ts": 1746247200000,
    "site_id": "SITE-01",
    "shift": "DAY",
    "tag_id": "MOTOR-001.SPEED"
  }
}
| Area | Meaning |
|---|---|
type | Message classification. Criteria for filter node branching |
originator | Subject entity of the message (which asset/tag/order it relates to) |
data | Payload body |
metadata | Context (time, site, shift, tag ID, etc.) |
Message Types
| Type | Origin Entry Point |
|---|---|
POST_TELEMETRY / TAG_POINT | Tag point inflow |
POST_ATTRIBUTES | Tag/asset meta update |
TAG_ALARM | Tag-level alarm |
ENTITY_CREATED / UPDATED / DELETED | Entity lifecycle events |
ASSET_DATA / ASSET_EVENT / ASSET_ALARM / ASSET_COMMAND / ASSET_AGGREGATION / ASSET_CONTEXT | Asset domain events |
ASSET_HEALTH_STATUS / ASSET_CONNECTION_STATUS | Asset periodic evaluation (health/connection status) |
OEE_EVENT / RAM_EVENT / EMS_EVENT | ISO analysis result events |
OPC_STATUS / EDGE_STATUS | OPC/edge device status |
DIAGNOSTIC / DOMAIN_CHANGED | Diagnostics/domain changes |
ALARM | Alarm occurred |
WEBHOOK | HTTP webhook received |
KAFKA_INBOUND / MQTT_INBOUND | External topic received |
TIMER | Schedule fired |
Payload Examples by Trigger
You need to know exactly which fields you can access when writing script nodes. Below are actual message JSON examples produced by each trigger. All trigger messages commonly include type, originator, data, metadata.
flow_on_tag_point — Tag Point Inflow
Fires whenever a value comes in for one tag. The most common trigger.
{
  "type": "POST_TELEMETRY",
  "originator": { "entity_type": "Tag", "id": "MOTOR-001.SPEED" },
  "data": {
    "value": 1500.7,
    "quality": "GOOD",
    "ts": 1746247200123
  },
  "metadata": {
    "tag_id":      "MOTOR-001.SPEED",
    "site_id":    "SITE-01",
    "area_id":    "AREA-A",
    "line_id":    "LINE-1",
    "asset_id":   "MOTOR-001",
    "opc_id":     "OPC-LINE-1",
    "java_type":  "Float",
    "unit":       "rpm",
    "shift":      "DAY"
  }
}
| Field | Meaning | Script Access |
|---|---|---|
data.value | Received value (numeric/string/boolean) | msg.data.value |
data.quality | OPC quality (GOOD/BAD/UNCERTAIN) | msg.data.quality |
data.ts | Time received (epoch ms) | msg.data.ts |
metadata.tag_id | Tag ID | msg.metadata.tag_id |
flow_on_tag_alarm — Tag Alarm Occurred
Fires the moment a tag crosses an alarm band (hi/lo/...).
{
  "type": "TAG_ALARM",
  "originator": { "entity_type": "Tag", "id": "MOTOR-001.TEMP" },
  "data": {
    "alarm_band": "HI_HI",
    "value":      95.3,
    "threshold":  90.0,
    "priority":   "ERROR",
    "band_message": "온도 위험"
  },
  "metadata": {
    "tag_id": "MOTOR-001.TEMP",
    "asset_id": "MOTOR-001",
    "site_id": "SITE-01",
    "ts": 1746247200123
  }
}
data.alarm_band Value | Meaning |
|---|---|
NORMAL / HI / LO / HI_HI / LO_LO / TRIP_HI / TRIP_LO | Numeric alarm levels |
BOOL_TRUE / BOOL_FALSE | Boolean alarm |
flow_on_asset_data / flow_on_asset_event — Asset Events
Fires when asset-level aggregated events (CEP processing results, plugin evaluation results, etc.) occur.
{
  "type": "ASSET_EVENT",
  "originator": { "entity_type": "Asset", "id": "MOTOR-001" },
  "data": {
    "event_type":  "STARTUP",
    "details":     { "rpm_target": 1500 }
  },
  "metadata": {
    "asset_id": "MOTOR-001",
    "site_id": "SITE-01",
    "ts": 1746247200123
  }
}
flow_on_asset_data delivers asset-level time series data (data.values is a key-value map), and flow_on_asset_aggregation delivers minute/hour-level aggregated values.
flow_on_asset_health_status / flow_on_asset_connection_status — Periodic Evaluation
The platform evaluates asset-level health/connection status on a 1-minute cycle.
{
  "type": "ASSET_HEALTH_STATUS",
  "originator": { "entity_type": "Asset", "id": "MOTOR-001" },
  "data": {
    "status":       "WARN",
    "info_count":   12,
    "warn_count":   3,
    "error_count":  0,
    "prev_status":  "OK"
  },
  "metadata": { "asset_id": "MOTOR-001", "ts": 1746247200123 }
}
data.status Value | Meaning |
|---|---|
OK / WARN / ERROR / UNKNOWN | Health levels |
CONNECTED / LATENT / ERROR / DISCONNECTED / UNKNOWN | Connection level (connection_status) |
A common pattern is filtering to fire subsequent actions only at the moment of state transition, by comparing against prev_status.
flow_on_oee_event / flow_on_ram_event / flow_on_ems_event — Plugin Events
Fires when work order-level OEE/RAM/EMS evaluation results are updated. The originator is the equipment, and the calculation result is in data.payload.
{
  "type": "OEE_EVENT",
  "originator": { "entity_type": "Asset", "id": "ASSET_DJ_M_0001" },
  "data": {
    "event_type":     "OEE_CALCULATED",
    "plugin":         "OEE",
    "statement_type": "RESULT",
    "asset_id":       "ASSET_DJ_M_0001",
    "timestamp":      1746247200123,
    "payload": {
      "oee":            0.78,
      "availability":   0.95,
      "performance":    0.85,
      "quality":        0.97,
      "good_quantity":  { "quantity_string": "1560", "data_type": "integer", "unit_of_measure": "EA" },
      "scrap_quantity":  { "quantity_string": "42",   "data_type": "integer", "unit_of_measure": "EA" },
      "rework_quantity": { "quantity_string": "6",    "data_type": "integer", "unit_of_measure": "EA" },
      "run_time_ms":    25200000,
      "order_id":       "ORDER_000001"
    }
  }
}
good_quantity,scrap_quantityandrework_quantityare Quantity objects in the work order's unit (ISA-95 / B2MML). The value is a decimal string, so to compute with it in a script convert it, e.g.Number(data.payload.good_quantity.quantity_string), and check the unit inunit_of_measure. The oldgood_countandbad_countfields are gone. Field rules: Order Service — Quantity.scrap_quantityis scrap only; rework isrework_quantity. If you need the bad total, add the two (good + scrap + rework = produced).- A ratio that was not calculated («not applied») and a missing quantity are null, not 0.
flow_on_opc_status / flow_on_edge_status — OPC/Edge Status
{
  "type": "OPC_STATUS",
  "originator": { "entity_type": "OPC", "id": "OPC-LINE-1" },
  "data": {
    "connection_status": "CONNECTED",
    "scan_status":       "START",
    "prev_status":       "DISCONNECTED"
  },
  "metadata": { "opc_id": "OPC-LINE-1", "edge_id": "EDGE-A", "ts": 1746247200123 }
}
flow_on_diagnostic — System Diagnostic Message
Fires when a diagnostic message occurring in a server module comes in.
{
  "type": "DIAGNOSTIC",
  "originator": { "entity_type": "Module", "id": "cep-engine" },
  "data": {
    "level":   "WARN",
    "code":    "PATTERN_LAG",
    "summary": "EQL 패턴 평가 지연 1.2s",
    "module":  "cep-engine"
  },
  "metadata": { "ts": 1746247200123 }
}
data.level | Meaning |
|---|---|
INFO / WARN / ERROR | Diagnostic severity |
flow_on_domain_changed — Domain Change Event
Fires when a domain entity such as asset, tag, site, or work order is CRUD'd.
{
  "type": "DOMAIN_CHANGED",
  "originator": { "entity_type": "Asset", "id": "MOTOR-001" },
  "data": {
    "action":      "UPDATED",
    "before":      { "asset_name": "Motor1" },
    "after":       { "asset_name": "Motor 01 - Renamed" },
    "changed_by":  "admin"
  },
  "metadata": { "ts": 1746247200123 }
}
flow_on_entity_event — Entity Lifecycle
Fires collectively across the three types ENTITY_CREATED / ENTITY_UPDATED / ENTITY_DELETED. A single node receives all three lifecycle types.
{
  "type": "ENTITY_CREATED",
  "originator": { "entity_type": "Customer", "id": "CUST-9001" },
  "data": { "customer_name": "신규 고객", "external_id": "ERP-CUST-9001" },
  "metadata": { "ts": 1746247200123 }
}
flow_on_webhook — External HTTP Push
A payload sent by an external system to POST /webhook/flow/{flow_id} is converted directly into a message. Authenticated via the {flow_id} in the URL path and the X-API-Key header.
/flow/webhook/{flow_id} returns 410 GoneThat path was disabled because it could fire the flow with any flow_id without authentication
(FlowController now returns 410). The new entry point /webhook/flow/{flow_id} has
WebhookController verifying an API key/HMAC. It's an easy-to-miss reversed path —
it's not flow/webhook but webhook/flow.
{
  "type": "WEBHOOK",
  "originator": { "entity_type": "External", "id": "ERP" },
  "data": {
    "order_no":  "PO-20260512-001",
    "customer":  "ACME",
    "quantity":  1000
  },
  "metadata": {
    "http_method": "POST",
    "remote_addr": "10.20.0.55",
    "request_id":  "req-7c0a...",
    "ts": 1746247200123
  }
}
The entire JSON body sent by the external system goes into
dataas-is. HTTP headers appear only partially (remote_addr/method/request_id) inmetadata.
flow_on_mqtt_subscribe — MQTT Topic Subscription
{
  "type": "MQTT_INBOUND",
  "originator": { "entity_type": "Topic", "id": "factory/line1/events" },
  "data": { "event": "STARTUP", "rpm": 1500 },
  "metadata": {
    "topic":   "factory/line1/events",
    "qos":     1,
    "broker":  "tcp://mqtt.example.com:1883",
    "ts": 1746247200123
  }
}
flow_jdbc_poll — External DB Periodic Polling
Executes a configured SELECT query periodically, firing one message per row.
{
  "type": "KAFKA_INBOUND",
  "originator": { "entity_type": "DB", "id": "mes_db" },
  "data": {
    "PO_NO":    "PO-20260512-001",
    "CUSTOMER": "ACME",
    "QTY":      1000,
    "DUE_DATE": "2026-05-20"
  },
  "metadata": {
    "datasource": "mes_db",
    "query":      "SELECT * FROM po WHERE status='NEW'",
    "row_index":  0,
    "ts": 1746247200123
  }
}
If there are 100 rows, 100 messages fire sequentially. Please update a processing flag together within the SELECT query, or add a
processed_atcolumn comparison condition, so as not to reprocess the same rows.
flow_schedule — Time-Based Firing
Fires on a cron expression or fixed interval. The payload is empty and only metadata.ts is populated.
{
  "type": "TIMER",
  "originator": { "entity_type": "Schedule", "id": "daily-report" },
  "data": {},
  "metadata": {
    "cron":      "0 0 8 * * ?",
    "fired_at":  1746247200000,
    "ts":        1746247200000
  }
}
Precautions When Transforming Payloads
originator.idis the domain ID — if changed with theflow_change_originatornode, subsequentflow_save_attributes·flow_publish_asset_*action nodes operate based on the new originator.- When swapping out
data/metadatavia script, direct assignment rather than a shallow copy (Object.assign) is recommended — changing the original could affect other flows subscribed to the same trigger. - All epoch time fields are in milliseconds (ms). If seconds are needed,
Math.floor(msg.metadata.ts / 1000).
Node Catalog
Detailed node IDs and options can be checked in the inspector on the edit screen.
Trigger (22 types)
The starting point of every flow is a trigger node. There are no separate entry/exit point nodes.
Automatic Domain Reception — internal system events are automatically dispatched.
| Category | Trigger Node |
|---|---|
| Tag | flow_on_tag_point (telemetry), flow_on_tag_alarm |
| Asset | flow_on_asset_data, flow_on_asset_event, flow_on_asset_alarm, flow_on_asset_command, flow_on_asset_aggregation, flow_on_asset_context, flow_on_asset_health_status, flow_on_asset_connection_status |
| Plugin | flow_on_oee_event, flow_on_ram_event, flow_on_ems_event |
| OPC/Edge | flow_on_opc_status, flow_on_edge_status |
| Diagnostics/Domain | flow_on_diagnostic, flow_on_domain_changed |
| Entity | flow_on_entity_event |
flow_on_alarmAlarm triggers are split into two based on the target — the tag alarm is flow_on_tag_alarm,
and the asset alarm is flow_on_asset_alarm. An old document's example used flow_on_alarm,
but since that name isn't in the palette, following it directly means the node can't be found.
Every trigger node can perform message-level pre-filtering with the
*_patternoption (glob:*,?). Messages not matching the pattern are not passed to subsequent nodes, and the execution count also does not increase (handled as SKIPPED). To minimize operational load, it's recommended to filter out messages early at the trigger stage.
External Entry
| Node | Action |
|---|---|
flow_on_webhook | Receives a payload pushed by an external system via HTTP |
flow_on_mqtt_subscribe | Subscribes to an external MQTT broker topic |
flow_jdbc_poll | Periodically reads SELECT results from an external database, firing per row |
Time-Based
| Node | Action |
|---|---|
flow_schedule | Cron/interval schedule — fires TIMER message |
Filter (6 types)
| Node | Description |
|---|---|
flow_msg_type_filter | Fires TRUE if type is included in the specified list |
flow_originator_type_filter | Fires TRUE if originator.entity_type is included in the specified list |
flow_script_filter | Evaluate a boolean via script |
flow_check_existence_field | Whether specific fields exist in data/metadata |
flow_switch | Multi-case branching (different relation per case) |
flow_check_relation | Branch based on the relation from the previous step |
Transform (8 types)
| Node | Display Name | Description |
|---|---|---|
flow_script_transform | Script Transform | Transform data/metadata via script |
flow_change_originator | Change Originator | Change originator to a different entity |
flow_rename_keys | Rename Keys | Batch-rename data field names |
flow_template | Template | Generate substituted text with ${path} |
flow_split | Split | Split into a message per element if data is an array |
flow_merge | Merge | Merge multiple messages within a time window — the opposite of flow_split |
flow_flatten | Flatten | Lift child keys of a nested object up to the top level (data.data_map.x → data.x) |
flow_to_email | Email Conversion | Convert a message into email format |
flow_flattenis used when you want subsequent nodes to reference a message with a value nested one level deeper insidedata_map, like a tag point, directly via${data.x}.
Action — Integration/Storage (2 types)
| Node | Description |
|---|---|
flow_save_tag_point | Load a tag point (same as the normal ingest path) |
flow_save_attributes | Partial update of tag/asset meta |
If you're looking for
flow_dds_publish(free publish to the internal message channel), that's not here but in the External Integration palette group.
Action — Asset Event Publishing (4 types)
Publishes asset events via the same processing path as CEP (EQL) (persistent storage + cache + timeline + plugin + message channel consistent handling).
| Node | Channel |
|---|---|
flow_publish_asset_event | Asset event |
flow_publish_asset_context | Asset context |
flow_publish_asset_aggregation | Asset aggregation |
flow_publish_asset_command | Asset command |
flow_asset_command_invoke — Executes rather than publishes
| Node | Display Name | What it does |
|---|---|---|
flow_asset_command_invoke | Invoke Asset Command | Synchronously executes a command defined on the asset and waits for the result |
flow_publish_asset_commandflow_publish_asset_command— Publishes an asset command event to the channel. It ends once published.flow_asset_command_invoke— Actually executes the command defined on the asset and waits until it receives the result.
If you wanted a command to actually execute but used the publish node instead, it will look as if nothing happened.
Action — Domain CRUD (34 types)
All domain operations are delegated to the same domain service, maintaining audit trail and consistency. The *_field dynamic option can extract values from the message payload.
| Domain | Create | Update | Delete |
|---|---|---|---|
| Asset | flow_create_asset | flow_update_asset | flow_delete_asset |
| Tag | flow_create_tag | flow_update_tag | flow_delete_tag |
| Site/Area/Line | flow_create_site | flow_update_site | flow_delete_site |
| WorkOrder | flow_create_work_order | flow_update_work_order | flow_delete_work_order |
| Alarm Configuration (EQL) | flow_create_alarm_config | flow_update_alarm_config | flow_delete_alarm_config |
| Customer | flow_create_customer | flow_update_customer | flow_delete_customer |
| Product | flow_create_product | flow_update_product | flow_delete_product |
| Employee | flow_create_employee | flow_update_employee | flow_delete_employee |
| Calendar (Shift) | flow_create_calendar | flow_update_calendar | flow_delete_calendar |
Tag Alarm Band Partial Update (2 types)
| Node | Description |
|---|---|
flow_update_tag_alarm_band_numeric | Partially updates only the entered fields of numeric alarm bands (hi/lo/hi_hi/lo_lo/trip_hi/trip_lo/band_message/use_alarm) |
flow_update_tag_alarm_band_boolean | Partially updates only the entered fields of boolean alarm bands (bool_true/bool_false/priority/message/use_alarm) |
Work Order Status Transitions (5 types)
Since it calls the domain service's status transition method rather than directly updating a numeric column, OEE/RAM/EMS visibility is maintained.
| Node | Transition |
|---|---|
flow_start_work_order | WAIT → START |
flow_pause_work_order | START → PAUSED |
flow_resume_work_order | PAUSED → START |
flow_end_work_order | START or PAUSED → END |
flow_abort_work_order | START or PAUSED → ABORTED (abort_code, notes options) |
Automatic NOT NULL Backfill — Create nodes automatically fill in default values for NOT NULL columns. Example: for work orders,
status="WAIT"/master_idis the MES master ID (auto-backfilled if absent), customer manager info"admin"/"admin@example.com", employeeorg_idfalls back tosite_id, andinsert_user_id="flow"for all rows. Empty strings in FK columns (e.g.,customer_id/product_id) are converted to NULL.
Update Node — Partial Update — Update nodes for Customer/Product/Employee/Calendar and alarm bands first look up the existing record, then merge and save only the entered fields. Empty strings/null values are ignored, keeping existing values. If a full overwrite is needed, use a Delete + Create combination.
Direct alarm trigger nodes are intentionally excluded. Alarms must only occur through the
flow_create_alarm_configpath to maintain alarm history consistency.
Edge (22 types)
Calls the REST API of an edge device (OPC Agent) to automate OPC server registration, tag CRUD, tag value read/write lookup, and Docker app control. All nodes semantically share the same behavior differing only in the underlying HTTP method (GET/POST/PUT/DELETE).
| Group | Node |
|---|---|
| OPC server management | flow_edge_opc_create, flow_edge_opc_update, flow_edge_opc_delete, flow_edge_opc_start, flow_edge_opc_stop, flow_edge_opc_list |
| Tag management | flow_edge_tag_create, flow_edge_tag_update, flow_edge_tag_delete, flow_edge_tag_read, flow_edge_tag_write, flow_edge_tag_list |
| Lookup | flow_edge_monitoring, flow_edge_info, flow_edge_transfer |
| Docker app control | flow_edge_app_list, flow_edge_app_inspect, flow_edge_app_start, flow_edge_app_stop, flow_edge_app_restart, flow_edge_app_logs, flow_edge_app_stats |
3 Lookup Types
| Node | Display Name | What it does |
|---|---|---|
flow_edge_monitoring | Monitoring | Query edge monitoring metrics |
flow_edge_info | Edge Info | Query edge ID · version · uptime |
flow_edge_transfer | Transport Health | MQTT/Sparkplug transport status |
| Node | Display Name | What it does |
|---|---|---|
flow_edge_opc_list | OPC List | Query the edge's list of OPC servers |
flow_edge_tag_list | Tag List | Query OPC's tag list |
7 Docker App Control Types
Automates via flows the work you'd previously do by hand from the Docker panel of the edge detail screen.
| Node | Display Name | What it does |
|---|---|---|
flow_edge_app_list | App List | List of edge Docker containers |
flow_edge_app_inspect | App Detail | Container detail (inspect) |
flow_edge_app_start | Start App | Start container |
flow_edge_app_stop | Stop App | Stop container |
flow_edge_app_restart | Restart App | Restart container |
flow_edge_app_logs | App Logs | Container logs (line=N) |
flow_edge_app_stats | App Stats | Container CPU / memory / I/O |
app_stop · app_restart actually stops and restarts containers running on field edges.
When attaching to a trigger for automatic execution, keep the condition narrow — attaching
app_restart to a flapping alarm causes the container to repeatedly restart.
Common Settings
| Option | Description |
|---|---|
url | Edge REST endpoint. Supports ${data.x}/${metadata.y} template substitution |
method | HTTP method (defaults per node if unset — e.g., create=POST, update=PUT, delete=DELETE, read/monitoring=GET) |
headers | JSON headers (e.g., {"Authorization":"Bearer ${TOKEN}"}) |
body_template | Request body (sent as data as-is if unset, GET/DELETE do not send a body) |
timeout_ms | Timeout (default 5000) |
Response/Branching
data.response_status— HTTP status codedata.response— Response body (string)data.error— Error message (on failure)SUCCESS(200~399) /FAILURE(otherwise or exception)
External Integration (9 types)
All external nodes support the *_field dynamic option.
| Node | Dynamic Option |
|---|---|
flow_dds_publish | Free publish to internal message channel (not an external call, but belongs to this group) |
flow_http_request | url_field / method_field / body_field |
flow_kafka_publish | topic_field / key_field |
flow_mqtt_publish | topic_field |
flow_webhook_callback | url_field |
flow_send_email | to_field / cc_field / subject_field / body_field |
flow_send_sms | to_field / text_field |
flow_send_push | title_field / body_field |
flow_jdbc_query | Static SQL (SELECT/INSERT/UPDATE/DELETE) |
Flow Control (7 types)
| Node | Description |
|---|---|
flow_log | Debug log (level / prefix) |
flow_noop | Pass-through |
flow_delay | Forward to the next node after delay_ms |
flow_throttle | max_msgs / window_ms limit (THROTTLED relation on exceed) |
flow_debounce | Fires only the last message after window_ms stabilization |
flow_merge | Accumulates input over window_ms and emits once as a data.merged array |
flow_subflow | target_flow_id — call another flow |
flow_retry | max_attempts (default 3) / backoff_ms (default 1000) / backoff_multiplier (default 2.0). After the backoff wait, delivers the message via the SUCCESS branch; on reaching the max attempts, goes to the EXHAUSTED branch. Auto-updates metadata.retry_count / metadata.retry_exhausted |
Recommended Retry Wiring Pattern
[risky_node] ─[FAILURE]─▶ [flow_retry] ─[SUCCESS]─▶ (다시 risky_node 로 루프 연결)
                                       └[EXHAUSTED]─▶ [에러 핸들러 / 알림]
Detailed Node Options Reference
For complex nodes, this describes every option in detail beyond a simple one-line table — including defaults, examples, and failure handling.
flow_script_filter — Script Filter
| Option | Type | Default | Description |
|---|---|---|---|
script | text | (required) | Evaluation expression — returns boolean. true → TRUE branch / false → FALSE branch |
script_type | enum | javascript | javascript / eql |
on_error | enum | FALSE | On script exception — whether to route to TRUE / FALSE / FAILURE branch |
Script Context
| Variable | Meaning |
|---|---|
msg.type | Message type (POST_TELEMETRY, etc.) |
msg.data | Payload (modifiable, but meaningless in a filter) |
msg.metadata | Context |
msg.originator | originator object |
Examples
// 온도가 임계 초과 + 야간 시프트만
msg.data.value > 80 && msg.metadata.shift === 'NIGHT'
// 사이트별 임계 분기
var th = {'SITE-A': 80, 'SITE-B': 90, 'SITE-C': 75};
msg.data.value > (th[msg.metadata.site_id] || 100);
flow_script_transform — Script Transform
| Option | Type | Default | Description |
|---|---|---|---|
script | text | (required) | Transform expression — modify the msg object or return a new object |
script_type | enum | javascript | javascript / eql |
mode | enum | mutate | mutate (in-place) / return (use the return value) |
Examples
// data 에 계산 필드 추가
msg.data.fahrenheit = msg.data.value * 9/5 + 32;
msg.metadata.processed_at = Date.now();
// 페이로드 통째로 교체 (mode=return)
return {
  type: 'WEBHOOK',
  originator: msg.originator,
  data: { temp: msg.data.value, level: msg.data.value > 80 ? 'HIGH' : 'OK' },
  metadata: msg.metadata
};
In
mutatemode, even if there's areturnstatement, it's ignored. Set tomode=returnto replace with a new object.
flow_switch — Multi-Branch
| Option | Type | Default | Description |
|---|---|---|---|
cases | array | (required) | [{expression, relation}] array — evaluated top to bottom, first match adopted |
default_relation | string | DEFAULT | If no cases match |
script_type | enum | javascript | — |
Example
// cases 설정
[
  { "expression": "msg.data.value > 90", "relation": "CRITICAL" },
  { "expression": "msg.data.value > 80", "relation": "WARN" },
  { "expression": "msg.data.value > 70", "relation": "INFO" }
]
// default_relation: "NORMAL"
Subsequent nodes can perform different processing for each of the 4 branch labels (CRITICAL/WARN/INFO/NORMAL).
flow_retry — Automatic Retry
Automatically recovers from transient failures in external IO nodes.
| Option | Type | Default | Description |
|---|---|---|---|
max_attempts | int | 3 | Maximum number of attempts (exceeding this value triggers EXHAUSTED) |
backoff_ms | long | 1000 | Initial wait time (ms) |
backoff_multiplier | double | 2.0 | Exponential backoff multiplier — 1st 1 sec → 2nd 2 sec → 3rd 4 sec |
max_backoff_ms | long | 30000 | Upper cap on a single wait |
jitter_pct | int | 0 | ±N% random jitter on backoff (avoids thundering herd) |
metadata Auto-Enrichment
| Field | Meaning |
|---|---|
metadata.retry_count | Number of attempts so far |
metadata.retry_exhausted | true means it enters the EXHAUSTED branch |
metadata.retry_last_error | Last failure reason |
If the sum of backoffs exceeds 60 seconds, the trigger processing queue may get blocked. If external system responses are consistently slow, first limit the rate of entry with
flow_throttle.
flow_on_webhook — HTTP Trigger
| Option | Type | Default | Description |
|---|---|---|---|
auth_required | boolean | true | Whether the X-API-Key header is required — if off, anyone can call it |
allowed_origins | csv | * | CORS Origin whitelist |
max_body_kb | int | 256 | Body size cap (a 413 response is returned if exceeded) |
payload_pattern | glob | * | Message pre-filtering glob |
How to Call
curl -X POST \
  https://platform.example.com/webhook/flow/{flow_id} \
  -H "X-API-Key: {edge_or_token_key}" \
  -H "Content-Type: application/json" \
  -d '{"order_no":"PO-001","customer":"ACME","quantity":1000}'
{flow_id}in the path can be copied from the list screenX-API-Keyis a token issued from the edge API Key or API Auth Token screen- Response:
200 OK(enqueued to the message queue) /401(auth failure) /404(no flow or not deployed) /413(body exceeded)
flow_http_request — External HTTP Call
| Option | Type | Default | Description |
|---|---|---|---|
url | string | (required) | URL to call. ${data.x} template substitution |
url_field | string | — | When getting the URL dynamically from the payload — e.g., data.endpoint |
method | enum | GET | GET / POST / PUT / DELETE / PATCH |
method_field | string | — | Get the method dynamically from the payload |
headers | json | {} | {"Authorization": "Bearer ${TOKEN}"} form |
body | text | — | Static body (supports template substitution) |
body_field | string | — | When getting the body from the payload — usually data |
timeout_ms | int | 5000 | Response wait cap |
follow_redirect | boolean | true | Automatically follows 3xx redirects |
verify_ssl | boolean | true | TLS certificate verification (turn off only for testing) |
Response Payload Enrichment
| Field | Meaning |
|---|---|
data.response_status | HTTP status code (200 / 404 / 500 ...) |
data.response_body | Response body (auto-parsed if JSON) |
data.response_headers | Response headers object |
Branches
SUCCESS— 2xx/3xxFAILURE— 4xx/5xx or exception/timeout
flow_send_email — Send Email
| Option | Type | Default | Description |
|---|---|---|---|
to | string | — | Static recipients (comma-separated) |
to_field | string | — | Extract recipients from the payload — e.g., data.recipient |
cc / cc_field | string | — | CC |
bcc / bcc_field | string | — | BCC |
subject / subject_field | string | (required 1) | Subject — supports template substitution |
body / body_field | text | (required 1) | Body (HTML allowed) |
is_html | boolean | true | Turn off if it's a plain text email |
attachments | json | [] | [{"url":"...","filename":"..."}] |
SMTP settings must be registered beforehand by the operator under mail settings in System → Settings. Before registration, all email nodes fall into the
FAILUREbranch.
flow_jdbc_poll — External DB Polling
| Option | Type | Default | Description |
|---|---|---|---|
datasource_id | string | (required) | External DB identifier registered in System → Settings |
query | sql | (required) | SELECT query — returns up to 1,000 rows at a time |
poll_interval_ms | int | 60000 | Polling interval (default 1 minute) |
marker_column | string | — | "Last processed time" column — selects only rows after the marker |
marker_initial | string | 1970-01-01 00:00:00 | Marker start value at the first poll |
row_limit | int | 1000 | Maximum rows per poll (safe even if exceeded) |
on_error_continue | boolean | true | Log only diagnostics on DB error and proceed to next poll |
marker_column Usage Example
SELECT po_no, customer, qty, created_at
FROM po
WHERE created_at > :marker
ORDER BY created_at
→ The maximum created_at value received from the last poll is automatically inserted into the :marker position.
flow_kafka_publish / flow_mqtt_publish — External Publish
| Option | Type | Default | Description |
|---|---|---|---|
broker | string | (required) | kafka:9092 or tcp://mqtt:1883 |
topic | string | — | Static topic — ${data.x} substitution possible |
topic_field | string | — | Extract topic from payload (data.target_topic, etc.) |
key / key_field | string | — | (Kafka only) message key |
body / body_field | json/text | (required 1) | Publish body — data as-is if unset |
qos | int | 1 | (MQTT only) 0/1/2 |
retain | boolean | false | (MQTT only) Retained flag |
flow_publish_asset_* — Asset Event Publishing
Asset events (event/context/aggregation/command) are published to an integrated channel recognized simultaneously by CEP/plugins/timeline. Common options for the 4 nodes:
| Option | Type | Default | Description |
|---|---|---|---|
asset_id | string | — | Static asset ID |
asset_id_field | string | — | Extract asset ID from payload (usually metadata.asset_id) |
event_type | string | — | Asset event classification (e.g., STARTUP, SHUTDOWN, MAINTENANCE) |
event_type_field | string | — | Extract classification from payload |
payload | json | ${data} | Body to publish — data as-is if unset |
For
flow_publish_asset_command, it's delivered immediately to the asset's command receiving topic (asset_id/cmd/{event_type}) reaching the edge.
flow_create_* / flow_update_* — Domain CRUD
All Create/Update nodes share the following option pattern.
| Option | Type | Description |
|---|---|---|
{컬럼명} | string | Static value (NULL/default if not entered) |
{컬럼명}_field | string | Extract value from payload (data.foo / metadata.bar) |
id_strategy | enum | auto (system-issued) / field (extracted from {도메인}_id_field) |
on_duplicate | enum | error (default) / skip / update — Create node only |
Automatic NOT NULL Backfill
Create nodes automatically fill in default values for NOT NULL columns.
| Domain | Auto-Filled Columns |
|---|---|
| Work Order | status="WAIT" / master_id (auto-backfilled if absent) / insert_user_id="flow" |
| Customer | Manager info "admin" / "admin@example.com" (if not registered) |
| Employee | org_id=site_id (fallback) |
| Common | insert_date=now() / insert_user_id="flow" |
FK Empty String Handling
When an empty string "" is entered into an FK column (customer_id/product_id, etc.), it's automatically converted to NULL. In JS, msg.data.customer_id = '' is safer than delete msg.data.customer_id.
flow_edge_* — Edge REST Call
The 22 types of nodes calling REST endpoints on edge devices share common options.
| Option | Type | Default | Description |
|---|---|---|---|
edge_id | string | — | Static edge ID |
edge_id_field | string | — | Extract edge ID from payload |
path | string | (node default) | Edge REST path (e.g., /api/v1/opc, /api/v1/app/grafana/start) |
body_template | text | — | Request body — data as-is if unset |
timeout_ms | int | 5000 | — |
Automatic Authentication
Edge nodes automatically lookup that edge's api_key from the mm_edge master table when calling, and attach it as the X-API-Key header. No separate configuration is required by the operator.
Response Payload
| Field | Meaning |
|---|---|
data.edge_response_status | Edge response code |
data.edge_response | Response body |
data.edge_id | Target edge ID called (for confirmation) |
Branching is same as flow_http_request (SUCCESS / FAILURE).
Writing Script Nodes
flow_script_filter / flow_script_transform / flow_switch nodes support two types of expressions.
JavaScript (Default Recommended)
Standard ECMAScript syntax. Supports multi-line, var/let/const, functions, and object literals.
Bindings
| Variable | Description |
|---|---|
msg | The entire message. msg.data.x, msg.metadata.topic, msg.type, msg.originator.id all directly accessible |
data | Shortcut alias for msg.data |
metadata | Shortcut alias for msg.metadata |
Filter Example
data.temp > 80
Transform Example
data.temp_f = data.temp * 1.8 + 32;
data.alert = data.temp > 80 ? 'HIGH' : 'OK';
msg
Switch Example (boolean per case)
data.t > 100 // case "Critical"
Common Transform Patterns
// 1) 단위 변환 (섭씨 → 화씨) + 라벨링
data.temp_f = data.temp * 1.8 + 32;
data.alert  = data.temp > 80 ? 'HIGH' : 'OK';
msg

// 2) 메타데이터 보강 — 시간대·시프트 자동 부여
const h = new Date(metadata.ts).getHours();
metadata.shift = (h >= 6 && h < 18) ? 'DAY' : 'NIGHT';
msg

// 3) 외부 페이로드를 도메인 모델로 매핑 (MES PO → WorkOrder)
const po = data;
data = {
  master_id: 'WO-MES-' + po.po_no,
  asset_id:  po.line_id || 'UNASSIGNED',
  title:     po.product_name + ' (' + po.qty + ')',
  due_date:  po.delivery_date,
  qty:       po.qty
};
msg

// 4) 실패 분기로 명시적 라우팅 (필수 필드 누락 시)
if (!data.tag_id || data.value == null) throw new Error('필수 필드 누락');
msg

// 5) 배열 분할 후 데이터 정제 — split 노드 후에 사용
data.value     = parseFloat(data.raw);
data.threshold = data.value > 100;
msg
Common Filter Patterns
// 우선순위 화이트리스트
['ERROR', 'CRITICAL'].includes(data.priority)

// 시간대 기반 필터 (주간만 허용)
new Date(metadata.ts).getHours() >= 8 && new Date(metadata.ts).getHours() < 20

// 자산 ID 패턴 매칭
/^MOTOR-.*$/.test(originator.id)

// 임계값 + 안정성 (값이 5번 이상 누적된 경우)
data.value > data.threshold && data.consecutive_count >= 5
User scripts run in a safe sandbox, with file, network, thread, and arbitrary class access all blocked. If an external system call is needed, wire an external integration node such as
flow_http_requestseparately.
EQL Expressions
For compatibility with existing EQL users. Only single expressions are supported (no multi-line or semicolon-separated statements), and only side-effect patterns can be used.
#msg.getData().getInt('temp') > 80
If multiple actions are needed, please use JavaScript.
JavaScript Runtime Specification
Scripts run in an isolated sandbox. You must know exactly what's possible/impossible to write stable scripts.
Available (✅)
| Feature | Notes |
|---|---|
| Standard ECMAScript | var/let/const · functions · classes · destructuring · spread · ?. · ??, etc. |
| Object Literals | { key: value, ... } |
| Array Methods | map / filter / reduce / forEach / find / some / every / flat / slice |
| String Methods | split / replace / includes / match / padStart / repeat |
| Math functions | All of Math.* |
| JSON | JSON.parse / JSON.stringify (no need to stringify again if data is already an object) |
| Date | new Date() / Date.now() / getHours() / toISOString(), etc. |
| Regular Expressions | /pattern/ literal + RegExp constructor |
| Throwing Errors | throw new Error('...') — automatically routed to FAILURE branch |
| try/catch/finally | Exception handling |
Not Available (❌)
| Feature | Reason / Alternative |
|---|---|
Network calls (fetch / XMLHttpRequest) | Blocked by sandbox — wire a flow_http_request node separately |
File system (require('fs')) | Blocked by sandbox |
Threads (setTimeout / setInterval / Worker) | Only synchronous execution allowed — use a flow_delay node if delay is needed |
require / import | Cannot load external modules — define needed functions within the same script |
eval / new Function(string) | Blocked for security |
| Arbitrary Java classes | Not exposed to user code even in EQL compatibility mode |
process / global / window | Not defined |
| WebSocket / EventSource | Blocked — message reception is via trigger nodes |
Execution Limits — None
The old document included a table stating execution time 500ms, memory 16MB, stack 1024, output 2MB, but none of the four are actually applied.
- It looks like
timeout_mscan be used in node settings, but script nodes do not read that value. (ScriptTransformNode·ScriptFilterNodeonly readscriptandlanguage.) - The JS execution context also has no time, statement count, or memory limits set.
So a script like while (true) {} will occupy a worker thread indefinitely without being interrupted.
The overall flow limit of 30 seconds (flow_timeout_ms) is checked when the execution loop retrieves the
next task, so an infinite loop running inside a script never reaches that check.
Only write scripts that terminate on their own. Avoid infinite loops, huge iterations, and accumulating large strings, and always put an upper bound on loops.
What's Actually Blocked — Security Sandbox
Instead of time/memory, actions that touch the outside are definitely blocked.
| Item | Status |
|---|---|
Java class access (Java.type, etc.) | Blocked |
| File/network IO | Blocked |
| Thread creation | Blocked |
| Native access | Blocked |
| Experimental options | Blocked |
| Host object access | Only what's on the allowlist |
If an external call is needed, don't do it inside the script — separate it into a dedicated node like
flow_http_request— it won't work in a script anyway, andtimeout_msactually applies to a dedicated node.
Don't cram heavy processing into one script — split it across multiple nodes.
msg Return Convention
// flow_script_transform 의 두 가지 모드
// 1) mutate 모드 (기본) — msg 객체를 직접 수정, 마지막에 msg 또는 아무 값 반환
data.foo = 'bar';
msg

// 2) return 모드 — 완전히 새 객체로 교체
return {
  type: msg.type,
  originator: msg.originator,
  data: { ...data, foo: 'bar' },
  metadata: msg.metadata
};
Standard Time/Locale
| Item | Behavior |
|---|---|
| Server system timezone | UTC (using epoch ms directly is recommended) |
| Displaying Korean time | toLocaleString('ko-KR', { timeZone: 'Asia/Seoul' }) |
| Calculating time in Korean time | new Date(ts + 9*3600000).getUTCHours() or the above locale |
| 0-second-unit timestamp | Math.floor(Date.now() / 1000) * 1000 |
Memory-Safe Coding Patterns
Script nodes have a 16MB memory limit, but even small memory leaks accumulating in frequently invoked nodes can significantly burden the engine's GC. Avoid the following patterns.
Anti-Pattern 1 — Closures Retaining Large Data
// ❌ 나쁜 예 — 큰 배열을 변환 함수에 캡쳐
const heavy = data.records || [];          // 1만 건
const summarize = (item) => heavy.find(r => r.id === item.id);
data.matched = data.targets.map(summarize);
msg
// ✅ 좋은 예 — 인덱스 미리 만들고 함수 안에서만 사용
const index = {};
(data.records || []).forEach(r => { index[r.id] = r; });
data.matched = data.targets.map(t => index[t.id]);
data.records = undefined;     // 변환 후 큰 원본 제거
msg
Anti-Pattern 2 — Passing Large Arrays As-Is
// ❌ data.records 가 10,000 건이면 모든 후속 노드에서 메모리 차지
msg
// ✅ 필요한 통계만 남기고 원본 제거
data.summary = {
  count: (data.records || []).length,
  total: (data.records || []).reduce((s, r) => s + r.value, 0)
};
delete data.records;
msg
Anti-Pattern 3 — Deep Object Copies
// ❌ JSON.parse(JSON.stringify(obj)) 는 큰 객체에서 매우 느림
data.copy = JSON.parse(JSON.stringify(data.original));
// ✅ 얕은 복사 또는 필요한 필드만 직접 선택
data.summary = { id: data.original.id, name: data.original.name };
Anti-Pattern 4 — Regex Explosion (Catastrophic Backtracking)
// ❌ (a+)+b 형태의 중첩 그룹은 입력에 따라 지수 시간
const re = /^(a+)+b$/;
if (re.test(data.text)) ...
// ✅ 비포획 그룹 + atomic 그룹 패턴 또는 단순 매칭
const re = /^a+b$/;
if (re.test(data.text)) ...
Anti-Pattern 5 — let Accumulator Variable Outside the Function
// ❌ 함수 밖 let 은 매 노드 호출마다 0으로 리셋되지만, 의도와 다르게 동작 가능
let counter = 0;
data.items.forEach(() => counter++);
data.counter = counter;
// ✅ 명시적으로 함수 안에서 선언
data.counter = data.items.length;     // 같은 결과, 더 명확
Anti-Pattern 6 — Infinite Retries with Nested try/catch
// ❌ 실패해도 다시 던지지 않으면 그래프가 잘못된 분기로 이동
try {
  riskyCall();
} catch (e) { /* 무시 */ }
msg
// ✅ 실패 의도면 throw, 정상 의도면 명시적으로 기록
try {
  riskyCall();
  data.status = 'OK';
} catch (e) {
  data.status = 'ERROR';
  data.error_msg = e.message;
}
msg
An exception
throwwithin a script goes to theFAILUREbranch and the message is preserved. External IO nodes have their own separate branch, so don't wrap them in try/catch.
Diagnosing Memory Pressure
NODE_SCRIPT_OOMThe old document referred to NODE_SCRIPT_OOM · FLOW_MSG_TRIMMED · ENGINE_GC_PRESSURE as memory pressure
signals, but the product does not produce such code. There is no script memory cap and no
automatic payload truncation.
Determine memory pressure from metrics and symptoms, not code.
| What to Look At | Pressure Signal |
|---|---|
FLOW_EXECUTOR_DROPPED_COUNT | Starts rising from 0 — the processing pool is saturated and dropping messages |
FLOW_EXECUTOR_QUEUE_SIZE | Keeps increasing without decreasing |
FLOW_EXECUTION_TIME | Maximum value spikes to several times the usual level |
| Server logs | work_queue full ... task dropped warning, FlowExecutor timeout warning |
| JVM | Increased GC time · rising heap usage |
If you see the above signals, first inspect flows handling large payloads, and check whether a script is accumulating large string arrays.
Mobile Push Notification Channel
Send push notifications to the operator's mobile app using the flow_send_push node.
Node Options
| Option | Type | Default | Description |
|---|---|---|---|
to / to_field | string | (required 1) | Recipient user ID (comma-separated) or payload path |
title / title_field | string | (required 1) | Notification title (recommend under 50 characters) |
body / body_field | text | (required 1) | Body (recommend under 120 characters) |
priority | enum | NORMAL | NORMAL / HIGH — HIGH shows even on the lock screen |
sound | enum | default | default / silent / custom sound |
data | json | {} | Additional data for the app to process (4KB payload limit) |
deep_link | string | — | Screen to open on notification tap (e.g., pp://asset/MOTOR-001) |
ttl_sec | int | 86400 | Retention time if unread (seconds) — auto-deleted on expiry |
Automatic Per-User Token Routing
When an operator first logs into the mobile app, a device token is automatically registered under Security → API Auth Token. Flows do not handle tokens directly — you only need to specify the user ID.
- If both iOS and Android tokens are registered, both devices receive it
- If a token is invalid (app removed, etc.), it's automatically deregistered
Simple Send Example
[flow_on_asset_alarm]
  ↓ where priority='ERROR'
[flow_send_push]
   to_field:    "metadata.responsible_user"
   title:       "🚨 ${metadata.asset_id} 알람"
   body_field:  "data.band_message"
   priority:    HIGH
   deep_link:   "pp://alarm/view/${data.alarm_id}"
Multi-Language Push
// flow_script_transform — 사용자 로케일에 따라 본문 분기
const locale = metadata.user_locale || 'ko-KR';
const templates = {
  'ko-KR': { title: '🚨 ${asset} 위험 알람',           body: '값 ${value}, 즉시 점검 바랍니다.' },
  'en-US': { title: '🚨 ${asset} Critical Alarm',     body: 'Value ${value}, please inspect immediately.' },
  'ja-JP': { title: '🚨 ${asset} 危険警報',            body: '値 ${value}, 即時点検が必要です。' }
};
const tpl = templates[locale] || templates['ko-KR'];
data.push_title = tpl.title.replace('${asset}', metadata.asset_id).replace('${value}', data.value);
data.push_body  = tpl.body.replace('${value}', data.value);
msg
Used afterward via title_field=data.push_title / body_field=data.push_body in flow_send_push.
Group Notification Bundling (Inbox-style)
Bundle multiple alarms into a single notification (in 5-minute increments):
[flow_on_asset_alarm]
   ↓
[flow_merge window=300s]
   ↓ (data.merged 배열)
[flow_script_transform — 요약 만들기]
   ↓ data.push_body="알람 N건: A자산, B자산, ..."
[flow_send_push]
Automatic Escalation on User Absence
Auto-escalate to SMS or email 30 minutes after an unconfirmed push.
[flow_on_asset_alarm priority=ERROR]
   ↓
[flow_send_push]
   ↓ SUCCESS
   ↓ data.alert_id = response_id
[flow_delay 1800s (30분)]
   ↓
[flow_http_request GET /api/alert/${alert_id}/status]
   ↓ (response_body.read=false 면)
[flow_script_filter (data.response_body.read === false)]
   ↓ TRUE
[flow_send_sms]
   to_field: "metadata.responsible_phone"
   text:     "푸시 미확인 30분 경과: ${data.title}"
Recommended Send Frequency Limit
| Priority | Recommended Frequency |
|---|---|
| HIGH (shows on lock screen) | 5 or fewer per user per hour — prevent alarm fatigue |
| NORMAL | 20 or fewer per user per hour |
Wire in the flow_throttle node before sending, or stabilize alarms for the same asset with flow_debounce before sending.
External Auth Token Auto-Renewal
A pattern for automatically renewing expiring tokens like OAuth2 when calling external systems.
Simple Renewal — Time-Based (cron)
[flow_schedule cron='0 */50 * * * ?']    ← 50분마다 (만료 1시간 전)
   ↓
[flow_http_request]
   url:    "https://auth.example.com/oauth2/token"
   method: POST
   body:   "grant_type=client_credentials&client_id=${creds.client_id}&client_secret=${creds.client_secret}"
   ↓
[flow_script_transform]
   ↓ data.access_token = data.response_body.access_token
[flow_save_attributes]    ← 자격 증명 저장소에 저장
   target_id:   "creds:erp_api"
   attributes:  {"access_token": "${data.access_token}", "expires_at": ${data.response_body.expires_in * 1000 + ts}}
Afterward, in flow_http_request of another flow:
Headers: Authorization: Bearer ${creds:erp_api.access_token}
Proactive Renewal — On Receiving 401
[main flow]
   ↓
[flow_http_request]
   ↓ SUCCESS → 정상 처리
   ↓ FAILURE
[flow_script_filter (response_status === 401)]
   ↓ TRUE
[flow_subflow target_flow_id="refresh-token"]    ← 토큰 갱신
   ↓
[원래 노드로 루프]    ← 갱신된 토큰으로 재시도
Using a Refresh Token
[flow_http_request]
   url:    "https://auth.example.com/oauth2/token"
   method: POST
   body:   "grant_type=refresh_token&refresh_token=${creds.refresh_token}"
   ↓
[flow_script_transform]
   // 새 access_token + 새 refresh_token (rotation)
   data.access_token  = data.response_body.access_token;
   data.refresh_token = data.response_body.refresh_token;
   data.expires_at    = Date.now() + data.response_body.expires_in * 1000;
   msg
   ↓
[flow_save_attributes]
Automatic Alarm on Token Expiry Threshold
[flow_schedule cron='0 0 * * * ?']    ← 매시
   ↓
[flow_jdbc_query]
   sql: "SELECT id, expires_at FROM credentials WHERE expires_at < NOW() + INTERVAL '1 day'"
   ↓
[flow_split]
   ↓
[flow_send_email]
   subject: "API 토큰 만료 임박: ${data.id}"
   body:    "${data.id} 토큰이 ${data.expires_at} 만료 예정입니다."
Recommended Credential Storage Locations
| Type | Recommended Location |
|---|---|
| Static (rarely changes) | Credential store in System → Settings |
| Dynamic (auto-renewed) | Store in asset meta using flow_save_attributes with the pattern above |
| Per-user OAuth | Security → API Auth Token screen |
Never leave credentials as plain text within the graph — always write them as a reference (
${creds.x}) to an external store. Plain-text tokens are also not included in the JSON during import/export.
Select which language to use with the language option (JS or EQL).
Execution History Screen
You can view node-level execution events in chronological order.
Search Criteria
| Item | Description |
|---|---|
| Time | Specify the query period |
| Level | 전체 / INFO / WARN / ERROR |
| Flow ID | Filter to a specific flow only |
| Message ID | For tracing a single message |
| Count | Recent 200/500/1,000 entries |
Quick Time Range
Jump instantly with buttons at the top of the timeline panel: 10분전 / 30분전 / 1시간전 / 6시간전 / 12시간전 / 전체기간.
Result Columns
| Column | Description |
|---|---|
| Level | INFO / WARN / ERROR |
| Time | Event occurrence time |
| Event | FLOW_START / NODE_IN / NODE_OUT / NODE_ERROR / FLOW_END |
| Flow ID | Which flow |
| Node | Node display name |
| Node Type | e.g., flow_script_transform |
| Relation | SUCCESS / FAILURE / TRUE / FALSE / MATCH / NO_MATCH / DEFAULT / THROTTLED / EXHAUSTED (all uppercase) |
| Message | Summary of message type · subject · relation · processing time · data preview |
The current query results can be exported with the CSV Download button.
The retention period for execution history is 7 days. For long-term storage, please load data into an external logging system.
General Workflow
- Create a new flow —
새 플로우button on the list screen → enter name/description - Enter the edit screen — an empty canvas opens automatically
- Place a trigger node — drag a trigger node from the left palette
- Add processing nodes — place filter → transform → action in order and connect with wires
- Configure nodes — click each node and enter options in the right inspector
- Save —
저장button at the top right (auto-snapshot stored) - Test run — inject an arbitrary message and check the result
- Deploy — activate with the
배포toggle → runs automatically when trigger events come in - Monitor — check via the live debug panel and execution history screen
Example Flows
Each example is composed of a node wiring diagram + key node settings + behavior description. The node settings shown in JSON form correspond 1:1 with the values you'd enter in the right inspector.
Example 1: MES Work Order Auto-Creation
Polls MES every minute for new POs and converts them into work orders.
[flow_schedule: 매분]
   │
   ▼ TIMER
[flow_http_request: MES /api/po/list?status=NEW]
   │
   ▼ SUCCESS
[flow_split: data → 각 PO별 메시지]
   │
   ▼
[flow_script_transform: PO → WorkOrder 매핑]
   │
   ▼
[flow_create_work_order]
   │
   ├── SUCCESS → [flow_log: 워크오더 생성됨]
   └── FAILURE → [flow_send_email: 실패 알림]
Node Settings
| Node | Key Settings |
|---|---|
flow_schedule | cron: 0 * * * * ? (every minute at 0 seconds) |
flow_http_request | method: GET, url: https://mes.example.com/api/po/list?status=NEW, headers: {"Authorization":"Bearer ${MES_TOKEN}"} |
flow_split | path: data (split as an array) |
flow_script_transform | language: JS, refer to the script below |
flow_create_work_order | master_id_field: data.master_id, asset_id_field: data.asset_id, order_name_field: data.order_name, planned_quantity_field: data.planned_quantity, unit_of_measure_field: data.unit_of_measure, external_system_field: data.external_system, external_id_field: data.external_id |
flow_send_email | to_field: metadata.alert_to, subject: [MES 동기화 실패] ${data.po} |
Script Transform Example
data.master_id = 'WO-MES-' + data.po;
data.order_name = data.product_name + ' (' + data.qty + ' ' + data.uom + ')';
data.asset_id  = data.line_id || 'UNASSIGNED';
data.planned_quantity  = String(data.qty);   // planned quantity - a decimal greater than 0
data.unit_of_measure   = data.uom;           // UN/ECE Rec 20 code (EA, KGM, LTR ...) - required, no default
data.external_system   = 'MES';              // an external work order is identified by the (system, number) pair
data.external_id       = data.po;
data.due_date  = data.delivery_date;
metadata.alert_to = 'ops@example.com';
msg
Example 2: Publish Asset Command via External Webhook
Validates an HTTP payload sent by an external system and converts it into an internal asset command.
[flow_on_webhook]
   │
   ▼ WEBHOOK
[flow_script_filter: payload 검증]
   │
   ├── TRUE
   ▼
[flow_publish_asset_command]
   │
   ├── SUCCESS → [flow_log]
   └── FAILURE → [flow_webhook_callback: 외부에 실패 통보]
How to call: When you send a JSON body via POST /webhook/flow/{flow_id}, it's carried as-is into the data area and the trigger fires (the old /flow/webhook/… returns 410).
Script Filter Example
// 인증 토큰 일치 + 필수 필드 존재 검사
if (data.token !== 'EXPECTED_TOKEN') return false;
if (!data.asset_id || !data.cmd_key) return false;
true
Example 3: Alarm → Automatic Emergency Work Order Issuance
Upon receiving an alarm at ERROR level or above, issues an emergency maintenance work order targeting the parent asset.
[flow_on_tag_alarm]
   │
   ▼ ALARM
[flow_script_filter: priority = ERROR/CRITICAL]
   │
   ├── TRUE
   ▼
[flow_change_originator: Tag → 상위 Asset]
   │
   ▼
[flow_create_work_order: 긴급 정비]
   │
   └── SUCCESS → [flow_send_email: 정비 담당자]
Script Filter Example
['ERROR', 'CRITICAL'].includes(data.priority)
Example 4: External DB Sync — Bulk Asset Registration
Polls a legacy DB for new equipment rows and automatically registers them as assets.
[flow_jdbc_poll: SELECT * FROM legacy_assets WHERE sync_status='NEW']
   │
   ▼
[flow_script_transform: 컬럼 매핑]
   │
   ▼
[flow_create_asset]
   │
   ├── SUCCESS → [flow_jdbc_query: UPDATE legacy_assets SET sync_status='OK' WHERE id=?]
   └── FAILURE → [flow_log: ERROR + flow_send_push]
Node Settings
| Node | Key Settings |
|---|---|
flow_jdbc_poll | dsn: external DB connection, sql: SELECT * FROM legacy_assets WHERE sync_status='NEW' LIMIT 100, interval_ms: 60000 |
flow_create_asset | asset_id_field: data.legacy_id, asset_name_field: data.name, site_id_field: data.plant_code |
flow_jdbc_query | sql: UPDATE legacy_assets SET sync_status='OK' WHERE id=?, params_field: data.legacy_id |
Example 5: Automatic Work Order Status Transition
Automatically transitions work order status via asset start/stop events.
[flow_on_asset_event]
   │
   ▼ ASSET_EVENT
[flow_switch: data.event_type 기준]
   │
   ├── case "RUN"   ─▶ [flow_start_work_order] ─▶ [flow_log]
   ├── case "STOP"  ─▶ [flow_pause_work_order] ─▶ [flow_log]
   ├── case "DONE"  ─▶ [flow_end_work_order]   ─▶ [flow_log]
   └── DEFAULT      ─▶ [flow_noop]
Switch Node Case Examples
RUN:data.event_type === 'RUN'STOP:data.event_type === 'STOP'DONE:data.event_type === 'DONE' && data.qty_done >= data.qty_planned
If a status transition fails (invalid current status), it's automatically routed to
FAILURE, so you can wire it safely without a separate filter.
Example 6: Alarm Band Auto-Adjustment
Dynamically adjusts a tag's upper/lower alarm band based on asset aggregation (e.g., 6-hour average).
[flow_on_asset_aggregation]
   │
   ▼ ASSET_AGGREGATION
[flow_script_transform: 통계 → 임계값 산출]
   │
   ▼
[flow_update_tag_alarm_band_numeric]
   │
   ├── SUCCESS → [flow_log]
   └── FAILURE → [flow_send_email: 운영자 알림]
Script Transform Example
// 6h 평균 ± 3σ 를 임계값으로 사용
const mean   = data.mean;
const stddev = data.stddev || 1;
data.tag_id  = originator.id + '.TEMP';
data.hi      = mean + 3 * stddev;
data.lo      = mean - 3 * stddev;
data.hi_hi   = mean + 4 * stddev;
data.lo_lo   = mean - 4 * stddev;
data.use_alarm = true;
msg
Example 7: Edge Device Auto-Registration
Bulk-registers new OPC server info to an edge device upon receipt.
[flow_on_webhook] (POST 본문에 OPC + 태그 목록)
   │
   ▼
[flow_edge_opc_create]
   │
   ▼ SUCCESS
[flow_split: data.tags 배열]
   │
   ▼
[flow_edge_tag_create]
   │
   ▼ SUCCESS (모든 태그 등록 완료 후)
[flow_edge_opc_start]
   │
   └── SUCCESS → [flow_log: 엣지 디바이스 가동]
Call Body Example
{
  "type": "WEBHOOK",
  "data": {
    "opc_id":   "OPC-LINE-A",
    "endpoint": "opc.tcp://line-a.local:4840",
    "tags": [
      { "tag_id": "MOTOR-001.SPEED", "address": "ns=2;s=Motor1.Speed" },
      { "tag_id": "MOTOR-001.TEMP",  "address": "ns=2;s=Motor1.Temp"  }
    ]
  }
}
Example 8: External API Reliability Enhancement (Retry)
Applies backoff retry to an external API call that fails intermittently, and notifies the operator if the maximum attempts are exceeded.
[flow_on_asset_event]
   │
   ▼
[flow_http_request: 외부 ERP API]
   │
   ├── SUCCESS  → [flow_log]
   └── FAILURE  ─▶ [flow_retry]
                       │
                       ├── SUCCESS    ─▶ (다시 flow_http_request 로 루프 결선)
                       └── EXHAUSTED  ─▶ [flow_send_email: 'ERP 동기화 N회 실패']
Retry Node Settings
max_attempts:5backoff_ms:2000backoff_multiplier:2.0→ 2, 4, 8, 16, 32-second intervals
Example 9: Plugin Event Routing (Low OEE Notification)
Sends a push notification to the line manager when the OEE value falls below a threshold.
[flow_on_oee_event]
   │
   ▼
[flow_script_filter: data.availability * data.performance * data.quality < 0.6]
   │
   ├── TRUE
   ▼
[flow_template: '라인 ${originator.id} OEE ${data.oee_pct}%']
   │
   ▼
[flow_send_push: 라인 매니저]
Template Example
body:라인 ${originator.id} OEE ${data.oee_pct}% (목표 60% 미달, 주요 손실: ${data.top_loss})
Example 10: Message Cleansing Pipeline (Throttle + Debounce)
Limits high-frequency tag changes to once per minute, and additionally fires subsequent nodes only when there's no change for 5 seconds.
[flow_on_tag_point]
   │
   ▼
[flow_throttle: max_msgs=1, window_ms=60000]
   │
   ├── SUCCESS    → [flow_debounce: window_ms=5000]
   │                                │
   │                                ▼
   │                          [flow_save_attributes]
   └── THROTTLED  → [flow_log: 차단됨]
Example 11: Multi-Trigger Aggregation (Merge)
Bundles 3 event types (OEE/RAM/EMS) in 30-second increments and sends a single report message.
[flow_on_oee_event]  ─┐
[flow_on_ram_event]  ─┼─▶ [flow_merge: window_ms=30000]
[flow_on_ems_event]  ─┘                │
                                       ▼
                              [flow_script_transform: 요약 메시지 생성]
                                       │
                                       ▼
                              [flow_send_email: 일일 요약]
If you place multiple trigger nodes in the same flow, they all become entry points. The
data.mergedarray offlow_mergeaccumulates all messages received during the window.
Example 12: Bundling Common Processing into a Subflow
Separates common message cleansing logic (duplicate check + unit conversion + storage) into a separate flow, called from multiple triggers.
Main Flow (independent each)
[flow_on_tag_point]   ─▶ [flow_subflow: target_flow_id=FLOW_00099]
[flow_on_asset_data]  ─▶ [flow_subflow: target_flow_id=FLOW_00099]
Subflow FLOW_00099
(트리거 없음 — 호출 전용)
[flow_log: 'subflow in']
   │
   ▼
[flow_check_existence_field: data.value 존재]
   │
   ├── TRUE
   ▼
[flow_script_transform: 단위 변환]
   │
   ▼
[flow_save_tag_point]
Subflows can be saved without a trigger and used solely for external invocation (a warning is displayed on save).
Example 13: Automatic Daily Report Send on Shift Change
Sends a summary of production, quality, and downtime for yesterday through today via email at the end of the night shift daily (e.g., 06:00).
[flow_schedule: 0 0 6 * * ?]   (매일 06:00)
   │
   ▼ TIMER
[flow_http_request: 내부 통계 API /api/report/daily]
   │
   ▼ SUCCESS
[flow_script_transform: 본문 마크다운 생성]
   │
   ▼
[flow_send_email]
Script Transform Example
const r = data.report;
data.subject = `[${r.site_id}] ${r.date} 일일 운영 요약`;
data.body    =
  `■ 생산: ${r.qty_done}/${r.qty_planned} (${(100*r.qty_done/r.qty_planned).toFixed(1)}%)\n` +
  `■ 가동률: ${r.availability}%\n` +
  `■ 품질률: ${r.quality}%\n` +
  `■ 다운타임 Top3:\n` +
  r.downtimes.slice(0,3).map(d => ` - ${d.code} ${d.minutes}분`).join('\n');
msg
Example 14: Automatic Downtime Aggregation
Updates shift-level cumulative downtime when an asset STOP event comes in, and sends a notification if a threshold is exceeded.
[flow_on_asset_event]
   │
   ▼
[flow_msg_type_filter: type in [ASSET_EVENT]]
   │
   ▼ TRUE
[flow_script_filter: data.event_type === 'STOP']
   │
   ▼ TRUE
[flow_script_transform: 다운타임 분 단위 계산]
   │
   ▼
[flow_save_attributes: 자산 누적 다운타임 갱신]
   │
   ▼ SUCCESS
[flow_script_filter: data.shift_downtime_min > 30]
   │
   ▼ TRUE
[flow_send_push: '시프트 다운타임 30분 초과']
Example 15: Automatic Quality Defect Line Isolation
Issues a stop command to the line asset and halts the work order if 5 or more consecutive defects are reported in a quality inspection.
[flow_on_asset_event]   (event_type=QUALITY_FAIL)
   │
   ▼
[flow_script_transform: data.consecutive_fail = (... + 1)]
   │
   ▼
[flow_save_attributes]
   │
   ▼ SUCCESS
[flow_script_filter: data.consecutive_fail >= 5]
   │
   ▼ TRUE
[flow_publish_asset_command: cmd_key='STOP']
   │
   ▼
[flow_abort_work_order: abort_code='QUALITY']
   │
   └── SUCCESS → [flow_send_email: 품질 매니저 + 라인 매니저]
Example 16: Energy Threshold Exceeded — Recommend Line Pause
Sends an SMS along with a recommendation message to the operator when the line's hourly energy consumption exceeds budget.
[flow_on_ems_event]
   │
   ▼
[flow_script_filter: data.power_kwh > data.budget_kwh * 1.2]
   │
   ▼ TRUE
[flow_template: '${originator.id} 시간당 ${data.power_kwh}kWh (예산 ${data.budget_kwh}kWh 초과)']
   │
   ▼
[flow_send_sms]
   │
   └── SUCCESS → [flow_save_attributes: 자산에 마지막 경고 시각 기록]
Example 17: External System Bidirectional Sync — Work Order Status Mirroring
Bidirectionally syncs status between an external ERP and the internal work order status.
Down (ERP → Internal)
[flow_on_mqtt_subscribe: erp/work-order/status]
   │
   ▼
[flow_script_transform: 메시지 → 도메인 매핑]
   │
   ▼
[flow_switch: data.status]
   │
   ├── case "STARTED" ─▶ [flow_start_work_order]
   ├── case "PAUSED"  ─▶ [flow_pause_work_order]
   ├── case "DONE"    ─▶ [flow_end_work_order]
   └── DEFAULT        ─▶ [flow_log: WARN]
Up (Internal → ERP)
[flow_on_entity_event]   (originator.entity_type=Order)
   │
   ▼
[flow_msg_type_filter: type in [ENTITY_UPDATED]]
   │
   ▼ TRUE
[flow_template: ERP 형식으로 변환]
   │
   ▼
[flow_mqtt_publish: erp/work-order/status]
To avoid infinite loops during bidirectional sync, mark the message origin with a key like
metadata.source, and filter out self-published messages at the trigger stage.
Import/Export
Flow definitions can be serialized to JSON to port to other environments or for backup.
| Action | Location | Description |
|---|---|---|
| Export | 내보내기 button at the top of the edit screen | Downloads the entire graph + nodes + wires + node settings as JSON |
| Import | 가져오기 button at the top of the list screen | Paste or upload JSON text |
| Auto-snapshot | Automatic on save | Stored per version on graph save (for rollback) |
Import Behavior
- A new flow ID is always issued (prevents overwriting existing IDs)
- Node IDs are also freshly assigned, and wire links are automatically remapped
- A flow immediately after import is loaded in an undeployed state; the operator must review it and deploy manually
Error Handling
Node Level
- If an exception occurs during node processing, it's automatically routed to the
FAILURErelation. - If no node is connected to the
FAILUREoutput, the message is dropped and only an error log remains. - Messages not matching the
*_patternof a trigger node are handled asSKIPPEDand not passed to subsequent nodes, and are not included in the processing/error counters either. - All errors are displayed in the live debug panel and execution history screen.
Flow Level
| Item | Default | Description |
|---|---|---|
| max_depth | 100 | Limit on cumulative node visits during one message's processing |
| max_revisit | 3 | Limit on revisit count of the same node (prevents infinite cycle loops) |
| flow_timeout_ms | 30,000 | Forced termination on exceeding processing time |
External IO Node Retry
External IO nodes such as HTTP, Kafka, and external DB can perform immediate internal retries via the retry_count / retry_delay_ms options, and are routed to the FAILURE relation if all retries fail. For more sophisticated backoff or EXHAUSTED branch handling, use a separate flow_retry node.
Operational Diagnostics
Administrators can check the flow engine's dispatch queue status (worker operating status, queue backlog size, cumulative processed/failed/dropped count, last error) in the system menu.
The server periodically checks the load on the flow worker pool in the background, and if the load persists for a certain period, records a state change (HEALTHY → DEGRADED → CRITICAL) in a single line in the operational log. When it recovers to normal, one more recovery log line is left.
Permissions
Flow does not introduce a separate permission model and uses the existing system authentication/permission as-is.
| Feature | Required Permission |
|---|---|
| View list / view execution history | All authenticated users |
| Create, edit, deploy, delete flows | ADMIN |
| Import/export / redeploy all | ADMIN |
Operational Patterns (Recipes)
A library of commonly used wiring shapes. Each pattern can be copied as-is to use as a starting point for a new flow.
Pattern 1 — Processing + Notification Branching
Dual-branches results based on outcome: SUCCESS is stored, FAILURE goes to notification.
[Action Node]
   ├── SUCCESS → [flow_log] / [flow_save_attributes] / ...
   └── FAILURE → [flow_send_email] / [flow_send_push]
Pattern 2 — Safe Retry
Composes a backoff + EXHAUSTED handler so external IO is robust against transient failures.
[risky_node] ─[FAILURE]→ [flow_retry] ─[SUCCESS]→  (risky_node 로 루프)
                                       └[EXHAUSTED]→ [에러 핸들러]
Pattern 3 — Blocking Load with Pre-Filtering
Reduces downstream processing volume by filtering messages early with the trigger's *_pattern. Pattern mismatches are handled as SKIPPED and not included in the counter.
[flow_on_tag_point]    (옵션 tag_id_pattern: "MOTOR-*.SPEED")
   │
   ▼
[필터/변환/액션 ...]
Pattern 4 — Multi-Case Branching
Branches into multiple paths based on status/type.
[flow_switch]   (case별 boolean 표현식)
   ├── case A → [...]
   ├── case B → [...]
   └── DEFAULT → [...]
Pattern 5 — Window Accumulation + Emit Once
Converts high-frequency input, collected over a set time, into a single message.
[High-rate Trigger]
   │
   ▼
[flow_merge: window_ms=10000]   → data.merged 배열에 누적
   │
   ▼
[flow_script_transform: 요약]
   │
   ▼
[Action / 외부 발송]
Pattern 6 — Retry + Route Around After Exhausting Retries
Routes to a backup path (another API, notification, DB storage) once retries are done.
[Primary HTTP] ─[FAILURE]→ [flow_retry]
                            ├─[SUCCESS]    → (Primary HTTP)
                            └─[EXHAUSTED]  → [Backup HTTP] ─[FAILURE]→ [flow_log/Email]
Pattern 7 — Follow-Up Action After Domain Conversion
Converts a tag-level alarm to an asset level, delegating to per-asset processing.
[flow_on_tag_alarm]
   │
   ▼
[flow_change_originator: Tag → Asset]
   │
   ▼
[자산 단위 액션 (Create Work Order / Publish Asset Event 등)]
Pattern 8 — Combined Throttle + Debounce
Processes only when throttled to at most once per minute + no change for 5 seconds.
[High-rate Trigger]
   │
   ▼
[flow_throttle: max_msgs=1, window_ms=60000]
   │
   ▼ SUCCESS
[flow_debounce: window_ms=5000]
   │
   ▼
[Action]
Pattern 9 — Modularizing Common Logic via Subflow
Separates into a subflow when multiple entry points need to share the same follow-up processing (validation, cleansing, storage).
메인1: [Trigger A] → [flow_subflow: target=FLOW_99]
메인2: [Trigger B] → [flow_subflow: target=FLOW_99]

서브 (FLOW_99): (트리거 없음)
[검증] → [정제] → [적재]
Pattern 10 — Direct Trigger Bypass
To flow the result of one flow into another flow's input, publish to the domain channel with flow_dds_publish, and have the other flow receive the same message type as its trigger.
플로우 A: [...] → [flow_dds_publish: type=ASSET_EVENT, originator=...]
플로우 B: [flow_on_asset_event] → [...]
Use Cases at a Glance
| Scenario | Composition |
|---|---|
| MES Integration | flow_schedule → flow_http_request → flow_script_transform → flow_create_work_order |
| External Event Relay | flow_on_asset_event → flow_msg_type_filter → flow_mqtt_publish |
| Data Cleansing/Storage | flow_on_tag_point → flow_script_transform → flow_save_tag_point |
| Alarm Automation | flow_on_tag_alarm → flow_script_filter → flow_send_email + flow_create_work_order |
| External DB Sync | flow_jdbc_poll → flow_script_transform → flow_create_asset |
| Webhook Reception | flow_on_webhook → flow_script_filter → flow_publish_asset_command |
| Alarm Band Auto-Adjustment | flow_on_asset_aggregation → flow_script_transform → flow_update_tag_alarm_band_numeric |
| Work Order Status Automation | flow_on_asset_event → flow_switch → flow_start/end/pause/resume_work_order |
| API Reliability Enhancement | flow_http_request ─FAILURE→ flow_retry ─SUCCESS→ loop / EXHAUSTED→ notification |
| Low OEE Notification | flow_on_oee_event → flow_script_filter → flow_template → flow_send_push |
| Bulk Edge Registration | flow_on_webhook → flow_edge_opc_create → flow_split → flow_edge_tag_create → flow_edge_opc_start |
| High-Frequency Cleansing | flow_throttle → flow_debounce → follow-up |
| Multi-Event Aggregation | Multiple triggers → flow_merge → summary transform → send |
Step-by-Step Debugging Guide
A standard procedure to follow when a flow doesn't work as intended.
Step 1 — Check Whether It's Firing
On the list screen, watch whether the execution count for that flow is increasing.
| Observation | Meaning · Next Action |
|---|---|
| Count is 0 | Trigger isn't firing. Check the flow's deployment status + trigger node wiring + *_pattern option |
| Count increases but errors increase too | Failing at an action node. Go to Step 2 |
| Count increases but subsequent processing doesn't happen | Missing branch wiring. Check all outputs including FAILURE/THROTTLED/EXHAUSTED etc. are handled |
Step 2 — Check Flow Per-Node via Live Debug
Open the edit screen and turn on the live debug panel (2-second refresh).
| Observation | Meaning |
|---|---|
| A specific node's light stays gray | Message not arriving — either it branched at FAILURE at the prior node or was blocked by a filter |
| Light red + ERROR line | Exception during node processing. Check the message's data.error field and the NODE_ERROR event in /flow/log |
| Light green but next node gray | Output relation label mismatch. Verify the wire label exactly matches the node's output relation (SUCCESS/TRUE, etc.) |
Step 3 — Trace the Message via Execution History Screen
Trace the entire flow of a single message by message ID in the /flow/log screen.
- Enter the
msg_idseen in the live debug into the message ID filter - Sort chronologically in the order
FLOW_START→NODE_IN→NODE_OUT→FLOW_END - If
NODE_ERRORis visible, that node'serror_messageis the cause
Step 4 — Inspect Node Settings
Frequently occurring mistakes:
| Mistake | Check |
|---|---|
*_field path typo | Is it correct? Is it data.tag_id or metadata.tag_id? Verify the actual key using the message preview in live debug |
${...} template variable not substituted | Whether the variable path exists in the message, whether there's a typo |
| External IO timeout | Increase timeout_ms. The external system's own response time |
| Permission/auth headers | Whether the headers JSON format is correct, whether the token is still alive |
Step 5 — Isolation Testing
Move the problematic node alone into a new temporary flow, and isolate/verify the result by firing just one message with Test Run. If it works fine, suspect the wiring of the original flow or the message shape from previous stages.
Step 6 — Reset Counters and Reproduce
Resetting all counters and firing just one message to reproduce with clean statistics makes the problem clearer.
Common Issues
| Symptom | Cause · Action |
|---|---|
| Trigger doesn't fire | Check whether the flow is deployed, whether the trigger node's *_pattern is too narrow. For schedule/external subscription nodes, retry after redeploy all |
| Live debug is empty | Check whether the message counter isn't increasing — trigger pattern mismatches (SKIPPED) aren't included in the counter. Also check whether the pause toggle at the top of the panel is on |
| Counter value accumulates abnormally | Reset the statistics window with the Reset All Counters button at the top right of node settings |
| The same message is processed repeatedly | Suspect a cycle. Revisiting the same node is only allowed within max_revisit's default 3 times. Separate with flow_subflow, then adjust the input volume with flow_throttle/flow_debounce |
| External system calls fail intermittently | Wire backoff retry with retry_count/retry_delay_ms node options or a flow_retry node |
| Schedule doesn't work after import | Run Redeploy All at the top of the list |
| Some fields don't change after running the Update node | Intended behavior. The Update node only updates entered fields and keeps the rest. Full update requires a Delete + Create combination |
| Create node fails with NOT NULL error | Check whether the *_field dynamic option path actually exists in the message in the node settings. Some NOT NULL columns are auto-backfilled, but key IDs (asset_id, tag_id, etc.) must be filled in directly |
flow_kafka_publish / flow_mqtt_publish isn't published | Check the external broker connection info (bootstrap_servers/broker_url) and topic permissions. Wire a flow_log nearby to check whether the message reaches right before publishing |
flow_http_request isn't getting a response | Increase timeout_ms (default 5000), and explicitly specify the body in ${msg.data.x} form at body_template. The response is stored in data.response_status / data.response |
flow_retry isn't being retried | This is a wiring mistake case. The SUCCESS output of flow_retry must be wired back into a loop to the original failed node for retries to occur (refer to Pattern 2 below) |
Rows like flow_jdbc_poll keep coming in again each time | The WHERE condition of the polling SQL must include a status update after processing (e.g., WHERE sync_status='NEW' + UPDATE ... sync_status='OK' via flow_jdbc_query at the end of the same flow) |
| Cannot find a direct alarm trigger node | This is an intended exclusion. Alarms must only occur via the flow_create_alarm_config path to maintain alarm history consistency |
Script node fails with a Java class access error | Blocked in the script sandbox. Wire a separate external integration node for external calls |
Work order status transition node only produces FAILURE | The current status is not a valid starting state for the transition. E.g., flow_pause_work_order only works from the START state. Check the status beforehand with flow_check_existence_field / flow_script_filter |
| Test Run worked but the graph appears changed | Test Run always fires the saved version. To verify changes, save first → then Test Run |
| Imported flow is inactive | Intended behavior. Review it and turn on the Deploy toggle yourself |
Frequently Asked Questions (FAQ)
A collection of questions operators frequently ask when first using Flow.
Q. Can a single flow have multiple triggers?
A. Yes. Multiple trigger nodes placed in the same flow all become entry points, each firing independently. Combined with flow_merge, you can merge multiple event types into a single downstream process.
Q. Can I create a flow without a trigger?
A. Yes. A warning is displayed on save, but it saves. You can use it as a "library" form that only fires via Test Run or another flow's flow_subflow call.
Q. Can one message go through multiple nodes at the same time? A. Yes. If you connect multiple wires from one node's output port, the same message branches simultaneously and is delivered to all subsequent nodes.
Q. Can a transform node build a message and turn it into a different message?
A. Yes. In flow_script_transform, msg.type, msg.originator, msg.data, msg.metadata can all be freely changed. However, even if you make the message itself appear like a different trigger type, it doesn't automatically invoke a different flow (the original trigger mapping is maintained). Use flow_subflow or flow_dds_publish to call another flow.
Q. How many auto-snapshots are retained? Can I restore them directly?
A. It's automatically stored on every graph save and follows the operational environment's retention policy. There's no UI to restore directly from the screen; if needed, you can ask an administrator to revert to a specific version. The safest method is to keep a JSON file externally with 내보내기 before making changes.
Q. How long is execution history retained?
A. 7 days by default. For long-term storage, load into an external log system with flow_kafka_publish or flow_jdbc_query.
Q. I want to reset the statistics for only one flow. A. Use Reset Error Count (errors only) or Reset All Counters (everything) at the top right of node settings in the edit screen. Other flows are unaffected.
Q. I want to move a flow to another environment (dev/staging/production).
A. Download the JSON with 내보내기 from the edit screen, and upload it with 가져오기 on the list screen of the target environment. Imported flows are always loaded with a new ID + undeployed state, so the operator can deploy it themselves after review.
Q. The same payload gets processed twice. How do I prevent that?
A. Narrow it down at the trigger stage with *_pattern, or limit frequency with flow_throttle/flow_debounce. If it's external input (webhook/MQTT), have the sender include an idempotency key and filter duplicates with flow_check_existence_field or a message ID-based filter.
Q. Is a cycle (loop) wiring safe?
A. Intended cycles like flow_retry are safe. Unintended cycles are automatically blocked by max_revisit (default 3 times). However, during operation, it's better to visualize the flow with flow_log to catch unintended cycles early.
Q. Are flow changes reflected in real time? A. Reflected immediately upon graph save. However, for triggers with their own scheduler such as schedule/external subscription/external DB polling, please re-register with Redeploy All or by toggling the flow off then on.
Q. Can I change the ID of an already registered node? A. Node IDs are automatically assigned by the system. Display names can be changed in the node settings form, and display names are used in live debug and execution history.
Q. Can a user without permission accidentally change a flow? A. Creating, editing, deploying, and deleting flows requires ADMIN permission. General users can only view the list and execution history.
Operational Best Practices
Principles worth following to safely operate flows in production.
Load Management
- Reduce downstream processing volume by pre-filtering at the trigger stage with
*_pattern. Tag points arriving tens of thousands of times per minute are the most expensive entry point. - Combine external system calls (
flow_http_request/flow_jdbc_query, etc.) withflow_throttle/flow_debounceto control external load. - If multiple downstream nodes need to hang off the same input, reduce total graph node count by separating with
flow_subflow. More nodes also means higher live debug polling cost. - Turn on debug mode only during operational verification. The more it accumulates, the faster the 7-day execution history retention window fills up.
Safe Writing
- Always wire a
FAILUREbranch on every action node (at minimum, even justflow_log). IfFAILUREis empty, the message silently drops, making incident tracing difficult. - Combine external IO nodes with
flow_retrywhere possible to absorb transient failures. - Update nodes update only the entered fields (partial update). Use a Delete + Create combination for full overwrites.
- A graph without a trigger node is for manual test-run only. Check the save warning to avoid accidentally omitting a trigger.
- Only create cycles (wiring back to the same node) in intended forms such as
flow_retry; otherwisemax_revisitprotects against it, but visualize the flow withflow_logfor suspicious graphs.
Change Management
Recommended order when changing an operating flow.
- Backup — download the current graph as a JSON file with
내보내기in the edit screen for storage (auto-snapshots are also stored, but external storage is safer). - Work with a copy or a new flow — rather than modifying an operating flow immediately, change and verify it in a new flow (or a copy made via import).
- Test Run — directly inject JSON messages to fire all branches (SUCCESS/FAILURE/EXHAUSTED, etc.) once each, and check the results in execution history.
- Deploy to Production —
내보내기the verified flow's graph JSON →가져오기in the production environment → operator reviews then toggles Deploy. - Rollback if issues occur — immediately disable with the Undeploy toggle. Since auto-snapshots are stored, you can ask a developer to revert to a previous version.
Utilizing Counters/Statistics
- If the processing trend sparkline on the list screen suddenly flattens, check for trigger non-firing or possible SKIPPED handling.
- If the error rate donut chart is abnormal, suspect the
*_fieldpath in node settings. It often fails if the key is missing from the message payload. - After operational verification, reset the statistics window with Reset All Counters to remeasure the normal baseline.
Emergency Response Procedures
Step-by-step procedures to use quickly when an issue occurs during operation.
Scenario 1 — A Specific Flow Runs Away (Message Surge)
Symptom: A flow's execution count surges tens to hundreds of times higher than normal, with errors also increasing
Action
- Immediately disable that flow with the Undeploy toggle (1 second on the list screen)
- Check the live debug panel and execution history to identify which trigger caused the surge
- Narrow the trigger node's
*_patternoption, or wireflow_throttle/flow_debounceright after - If needed, restrict to a message type with
flow_check_existence_fieldorflow_msg_type_filter - Reproduce with Test Run after fixing → confirm normal → resume Deploy
Scenario 2 — Mass Failures Due to External System Outage
Symptom: Errors accumulate simultaneously across external IO nodes such as HTTP/Kafka/external DB
Action
- If the impact scope is broad, bulk undeploy related flows (select multiple on the list screen, then bulk undeploy)
- Confirm external system recovery
- Add
flow_retrywiring for external IO nodes lacking it - Adjust
timeout_msif the external system's response has slowed - Depending on the environment, run Redeploy All then resume Deploy
Scenario 3 — Infinite Loop Due to a Cycle
Symptom: A single message keeps passing through the same node, processing time accumulating
Action
max_revisitprotection auto-blocks after up to 3 revisits, but for operational safety, undeploy and inspect- Visually trace the cycle in the graph (follow wires on the edit screen)
- If an intended loop (
flow_retry), check whethermax_attemptsis appropriate - If an unintended cycle, remove the wiring or add a branch with
flow_check_relation - Reset all counters after fixing → redeploy
Scenario 4 — Suspected Data Corruption (Incorrect Auto-Update)
Symptom: Domain data gets updated unintentionally through automation
Action
- Immediately undeploy that flow
- Check the previous graph JSON backup stored externally, or check a previous version from the auto-snapshot (administrator cooperation)
- Analyze the graph: check for unintended Update node wiring, incorrect
*_fieldpaths, or script transform errors - Correct affected domain data via a separate procedure on the back-office screen
- Verify the corrected graph with Test Run and then redeploy
Scenario 5 — Suspension During System Maintenance
Symptom: Want to temporarily pause external IO calls during external system maintenance
Action
- Bulk undeploy the affected flows (multi-select from the list)
- Resume Deploy after maintenance ends
- For triggers with their own scheduler (schedule, external MQTT subscription, external DB polling), verify normal re-registration with one run of Redeploy All
Scenario 6 — Live Debug Loading Queue Full
Symptom: Loading queue size in the operational diagnostics page is near the threshold, drop count increasing
Action
- Reduce the number of flows with debug mode on and the amount of loading (turn OFF debug mode for verified flows)
- Reduce follow-up processing volume itself with
*_patternat the trigger stage - If the system enters automatic recovery mode, a
DEGRADED/CRITICALlog line is left in the load watchdog — share it with the administrator
The priority in every scenario is immediately undeploy → identify cause → fix → verify → redeploy. Also refer to the change safety procedure.
Security & Sensitive Data Handling
Since flows handle sensitive input/output such as external API calls, email/SMS sending, and webhook reception, please follow these principles.
Tokens/Credentials
- Do not enter API tokens/passwords directly in node settings as plain text. Use environment variable substitution in the form
${ENV_VAR}so that they're injected from the operational environment's secret store. - Separate the location of the token in the
headersJSON into an environment variable as much as possible to avoid exposing it in the operational environment.
// 권장
{ "Authorization": "Bearer ${MES_TOKEN}" }

// 비권장
{ "Authorization": "Bearer eyJhbGciOi..." }
Protecting Webhook Entry Points
While flow_on_webhook is an internal entry point invoked by authenticated users, when exposing it externally, be sure to wire a payload validation filter.
// flow_script_filter — 토큰 + 필수 필드 검사
if (data.token !== '${WEBHOOK_TOKEN}') return false;
if (!data.asset_id || !data.cmd_key)   return false;
true
Masking Sensitive Data
The live debug panel and execution history display a message preview. Mask personal information (name, contact info, account) and tokens right before storage.
// 디버그/로그 적재 직전 변환
data.email_masked = data.email
  ? data.email.replace(/(.{2}).+(@.+)/, '$1***$2') : null;
delete data.email;
delete data.token;
msg
Handling External IO Response Bodies
data.response of flow_http_request stores the entire response body. If the response contains sensitive data, immediately extract only the needed keys with a subsequent transform node and remove the original.
// 응답에서 필요한 필드만 보존
data = { id: data.response_obj.id, status: data.response_obj.status };
msg
Script Node Isolation
Script nodes run in a safe sandbox with file, network, and arbitrary class access blocked. If an external call is needed, be sure to wire a separate external integration node.
Flow Metrics and Alarms
Metrics automatically collected while a flow is operating, where to see them, and how to set alarms on them.
Flow-Level KPIs
The following KPIs are displayed on each row of the list screen (/flow/index).
| Metric | Meaning | Abnormal Signal |
|---|---|---|
| Total Execution Count | Number of times a trigger fired and passed through the graph once (success/failure combined) | Sharp drop from usual → trigger dead / sharp rise → runaway |
| Error Count | Number of times any node in the graph fell into the FAILURE branch | Investigate if over 5% of the total |
| Error Rate | 에러 / 전체 × 100 | Set an alarm if a threshold is exceeded |
| Last Execution | The most recent firing time | "No firing for over 5 minutes" is OK only if that's the normal case |
| Average Processing Time | Average ms for one message to pass through the entire graph | Changes significantly when external IO nodes are added/removed |
| Recent Processing Time Trend | 5-minute sparkline — live debug panel | Check external system response upon a spike |
Node-Level KPIs
Clicking a node on the edit screen shows the following at the bottom right of the node.
[Node Name]
처리 999 · 에러 3 · 평균 12ms · 최근 18ms
| Location | Display |
|---|---|
| Top indicator | Gray (waiting) / green (processing) / red (error) |
| Bottom label | 처리 N · 에러 M · 평균 Xms · 최근 Yms |
4 Node Statistics Types
| Counter | Meaning |
|---|---|
| Processed | Number of messages entering that node and exiting via a normal branch |
| Error | Number of FAILURE branch or exception occurrences |
| Average Processing Time | Node's own processing ms (including external IO) |
| Recent Processing Time | ms for processing the last single item |
System-Level Metrics
Metrics for the flow engine overall can be checked on the System → Monitoring screen.
Metrics are exposed as the following five under the JMX domain plantpulse.core.engine.
| Metric | Type | Meaning | How to View |
|---|---|---|---|
FLOW_EXECUTOR_QUEUE_SIZE | Gauge | Size of the flow execution pool's waiting queue | If it keeps accumulating, processing can't keep pace with inflow |
FLOW_EXECUTOR_ACTIVE_COUNT | Gauge | Number of active threads in the execution pool | Saturated if stuck at the pool size |
FLOW_EXECUTOR_DROPPED_COUNT | Gauge (cumulative) | Cumulative number of tasks dropped due to pool saturation | If not 0, messages have been lost — the value to check first |
FLOW_DEBUG_QUEUE_SIZE | Gauge | Size of the debug event loading waiting queue | Grows larger with more flows having debug mode on |
FLOW_EXECUTION_TIME | Timer | Processing time distribution per flow | Track average/max |
flow.engine.*The old document included a table with flow.engine.queue_depth · in_flight · dispatch_lag_ms · exec_p95_ms
failed_per_min · script_timeout_per_min, but no metrics of that name exist. The above five
are all there are.
(flow.engine.enabled is not a metric but a configuration key in engine.properties —
a master gate that turns off the entire flow engine.)
Metric-Based Alarm Registration Patterns
4 patterns for monitoring the flow's own metrics with an advanced alarm or CEP → Trigger.
Pattern A — Error Rate Threshold Exceeded
context EVERY_1_MINUTES
SELECT flow_id, count(CASE WHEN status='FAILURE' THEN 1 END) * 100.0 / count(*) AS err_pct
FROM   AssetEvent.win:time(5 min)
WHERE  event_type = 'FLOW_EXEC'
GROUP  BY flow_id
HAVING err_pct > 5
Pattern B — Processing Queue Backpressure Occurring
Alarm when flow.engine.queue_depth > 500 persists for over 1 minute — a situation where the trigger firing rate exceeds the processing rate.
Pattern C — Firing Silence for a Specific Flow
SELECT * FROM pattern [
  every a = AssetEvent(event_type='FLOW_EXEC', flow_id='my-flow')
        -> ( timer:interval(15 min)
             and not AssetEvent(event_type='FLOW_EXEC', flow_id=a.flow_id) )
]
Alarm if a flow that normally fires N times per minute goes silent for over 15 minutes.
Pattern D — External IO Timeout Surge
context EVERY_5_MINUTES
SELECT flow_id, node_id, count(*) AS timeout_count
FROM   Log.win:time(5 min)
WHERE  module = 'flow-engine' AND code = 'NODE_TIMEOUT'
GROUP  BY flow_id, node_id
HAVING count(*) > 10
Recommended Alarm Output Channels
| Alarm Type | Recommended Channel |
|---|---|
| Error rate/firing silence (direct operations) | Email + push notification |
| Queue backpressure/timeout surge (system) | Slack/Teams webhook |
| Automatic diagnostics (reference) | Diagnostic log only |
⚠️ Never rely on metrics being monitored by the very flow used for alarms — if the alarm flow dies, the alarm itself won't come. Monitor alarm flows via external health checks in System → Monitoring.
Message Processing Semantics and Backpressure
The guarantee level of the flow engine when processing messages and backpressure behavior.
Delivery Guarantee — At-Least-Once
The flow engine guarantees at-least-once delivery.
| Case | Behavior |
|---|---|
| Normal processing | Fires once → passes through the graph once → completes once |
| Engine restart during processing | Messages remaining in the trigger queue are reprocessed after the next boot |
| Node-level exception | Only transitions to the FAILURE branch. The message doesn't disappear |
| External IO timeout | Transitions to the FAILURE branch + can auto-retry with flow_retry |
Possibility of Duplicates — This is not exactly-once. If
flow_create_*is interrupted midway and retried, the same ID may come in twice, so please useon_duplicate=skipor the external system's idempotency key.
Idempotency Key Pattern
A pattern for guaranteeing idempotency when a flow calls an external system.
// flow_script_transform — 멱등성 키 생성
msg.data.idempotency_key =
  msg.metadata.asset_id + '|' +
  msg.metadata.ts + '|' +
  msg.data.event_type;
Attach afterward as a header when calling externally:
"headers": { "Idempotency-Key": "${data.idempotency_key}" }
Processing Order — Per-Trigger FIFO
| Messages from the same originator | Different originators |
|---|---|
| Per-trigger FIFO (arrival order) | Parallel processing (order-independent) |
Even if 2 events for asset A occur almost simultaneously, A's events are processed in occurrence order. Events for asset A and asset B may be processed in parallel on different workers.
Backpressure
Behavior when processing speed can't keep up with the firing rate.
| Situation | Behavior |
|---|---|
| Queue depth < 80% | Normal — new triggers immediately enqueued |
| Queue depth 80%~100% | Diagnostic WARN log occurs — queue continues to accept |
| Queue depth = 100% (full) | New triggers dropped + diagnostic ERROR log occurs |
What the Operator Should Do When the Queue Is Full
- Check
flow.engine.queue_depthin System → Monitoring - Identify the flow with a surge in execution count on the list screen
- Narrow that flow's trigger pre-filter (
*_pattern) to reduce load - Or temporarily undeploy that flow for emergency handling
Circuit Breaker (External IO)
External IO nodes (HTTP/Kafka/MQTT/email) are bulk-blocked for 30 seconds if the following conditions are met.
| Condition | Threshold |
|---|---|
| Consecutive failures in the last minute | ≥ 10 |
| Average response time | ≥ 10 seconds |
All messages coming into that node during the block are immediately routed to FAILURE. Once the external system's response recovers, the block is automatically released. This behavior isolates the flow engine itself so that an external failure doesn't paralyze it.
The moment the circuit opens is recorded in the diagnostic log as
code = CIRCUIT_OPENED. If the external system recovered quickly, you can manually re-run missing messages by checkingmetadata.retry_countin the execution history.
Cycle (Loop) Prevention
If a cycle like the following occurs in a flow, an infinite loop can result.
A → B → C → A (잘못된 결선)
The flow engine blocks cycles with two lines of defense.
| Line of Defense | Behavior |
|---|---|
max_depth=100 | Forced termination after passing through 100 nodes |
max_revisit=3 | Message discarded + diagnostic ERROR at the moment of the 4th visit to the same node |
The SUCCESS branch of
flow_retry→ loop back to the original node is an intentional cycle, and sincemetadata.retry_countincreases together, it terminates normally before max_revisit triggers.
What You See in Execution History
Codes like NODE_SCRIPT_TIMEOUT · FLOW_TIMEOUT · FLOW_MAX_DEPTH · TRIGGER_QUEUE_FULL
WEBHOOK_AUTH_FAIL · DOMAIN_DUP_KEY were listed in a table, but the product never produces
that string anywhere. Searching the logs for that code returns 0 results forever.
What the flow engine actually leaves are the following 5 event types.
Five types of events are stored in the flow execution history (mm_flow_log, left menu Automation > Flow Execution History).
| Event Type | When | Storage Condition |
|---|---|---|
FLOW_START | On entering the flow | Always |
FLOW_END | On flow processing termination (both success and timeout) | Always |
NODE_IN | When a node receives a message | Only in debug mode |
NODE_OUT | When a node emits a message | Only in debug mode |
NODE_ERROR | Exception during node processing | Always |
Fields each row has together.
| Field | Content |
|---|---|
level | INFO / WARN / ERROR |
flow_id · flow_node_id · node_name · node_type | Which flow's which node |
msg_id | For message-level tracing — grouped by this value to follow one message's flow |
message · error_message | Human-readable description, exception message |
duration_ns | Node execution time (nanoseconds) — only meaningful for NODE_OUT · NODE_ERROR |
NODE_IN · NODE_OUT are only stored in debug mode. It's normal for execution history
to normally show only FLOW_START · FLOW_END. To follow node-by-node, turn on
debug mode for that flow — but that greatly increases log volume.
Finding by Symptom
Starting from symptoms rather than codes.
| Symptom | Look Here First |
|---|---|
| Trigger fires but no node seems to run | Whether the flow is deployed (toggle ON) · whether the trigger's *_pattern is filtering out the message |
| Processing is cut off midway | One message exceeded 30 seconds (flow_timeout_ms). Verify with the FlowExecutor timeout warning in server logs |
| The same message is processed repeatedly | A cycle. Auto-blocked by max_revisit (3 times) but check the wiring |
| Graph is too long, doesn't finish | Exceeds max_depth (100). Split into subflows |
| Node throws an exception | Look at error_message in the NODE_ERROR row of execution history |
| External call fails | Check data.response_status · data.error in a following node for that node |
The threshold values (100 · 3 · 30,000ms) are the defaults for
ExecutionState.
Cluster/HA Behavior
When the platform is installed as a clustered environment, the flow engine operates distributed with the following rules.
Node Role Separation
| Role | Behavior |
|---|---|
| Leader | The single node processing flow graph changes (save/deploy/undeploy) serially |
| Worker | Regular nodes performing parallel trigger firing/message processing (all nodes also act as workers) |
| Scheduler | Handles flow_schedule cron evaluation — same node as the leader |
The leader node is automatically elected at platform boot, and if the leader goes down, one of the other nodes is automatically promoted to leader. There's no need for the operator to designate it manually.
Message Distribution — Consistent Per-Asset Routing
| Distribution Key | Behavior |
|---|---|
originator.id (asset/tag/order ID) | Messages of the same asset are always routed to the same worker — sequence guaranteed |
External inbound (flow_on_webhook, etc.) | Round-robin distribution |
This rule prevents order confusion from asset A's events being processed simultaneously across multiple workers. As a result, single-worker processing is guaranteed per asset, while parallel processing is achieved across assets.
Behavior on Leader Failure — Failover
[Leader 다운 t=0]
        ↓
[다른 노드가 리더 승격 시도 t=0~3s]
        ↓
[새 리더 확정 t=3~5s]  ← cron 스케줄·플로우 배포 변경 재개
        ↓
[기존 워커들은 정상 동작 유지 — 트리거 처리 영향 없음]
| Stage | Impact |
|---|---|
| 0~3 seconds | flow_schedule firing temporarily paused / trigger processing unaffected |
| 3~5 seconds | New leader confirmed, schedule resumes |
| After 5 seconds | Normal |
Cron firing immediately re-executes one missed firing according to
misfirepolicy. During operation, if the evaluation unit offlow_scheduleis less than 5 seconds, short-term omissions may be visible.
Trigger Queue Persistence
| Item | Behavior |
|---|---|
| Trigger queue location | In-memory queue + persistent storage (transaction log) |
| On node restart | Unprocessed messages remaining in the queue are re-dispatched after the next boot |
| Node down during processing | That message is reprocessed, but requires an idempotency key in external systems per the at-least-once guarantee |
Operator Checklist for Cluster Deployment
- Synchronize time (NTP) across all nodes — trigger firing time should be consistent across nodes
- Place external systems (MQTT/Kafka brokers) at network locations reachable by all nodes
- Register
flow_send_email's SMTP settings only once in system settings — shared by all nodes - Adjust the worker pool size (
flow.engine.workers) according to each node's CPU core count
Single-Node Mode (Development, Small Scale)
- Leader, worker, and scheduler all run in one process
- No failover — if the node goes down, the flow itself stops
- Trigger queue is guaranteed via in-memory + disk, recoverable after restart
End-to-End Trace
How to trace after the fact how a message passed through the entire graph.
Automatic Correlation ID Assignment
The flow engine automatically assigns a correlation ID to every trigger-fired message.
{
  "type": "POST_TELEMETRY",
  ...,
  "metadata": {
    "trace_id":   "tr-a1b2c3d4-e5f6-7890-...",
    "span_id":    "sp-01",
    "parent_id":  null,
    ...
  }
}
| Field | Meaning |
|---|---|
metadata.trace_id | A unique ID for one entire trigger firing — all messages passing through every node of the graph share it |
metadata.span_id | Unique ID per node — updated each time it passes through a node |
metadata.parent_id | span_id of the preceding node |
Searching by trace_id in Execution History Screen
Pasting an ID into the trace_id input on the execution history screen displays a chronological log of all nodes that message passed through.
🔍 trace_id = tr-a1b2c3d4-...

[12:34:56.123] [trg]      flow_on_tag_point      태그=MOTOR.TEMP, value=87
[12:34:56.125] [filter]   flow_script_filter     score>80 → TRUE
[12:34:56.126] [transform] flow_change_originator Tag → Asset
[12:34:56.130] [action]   flow_create_work_order WO-20260513-001 생성
[12:34:56.241] [external] flow_send_email        admin@... 발송 성공
Trace Propagation on Subflow Invocation
Calling another flow with the flow_subflow node propagates the same trace_id as-is. That is, all node logs across the main flow + invoked subflow are searchable under the same trace.
Propagation to External Systems
An external HTTP call automatically attaches the X-Trace-Id header.
GET /api/orders HTTP/1.1
Host: erp.example.com
X-Trace-Id: tr-a1b2c3d4-e5f6-...
X-Span-Id:  sp-04
If the external system receives this header and records it along with its own logs, you can match logs across both systems using the same ID.
Exposing trace_id in Alarms/Emails
Including ${metadata.trace_id} in the alarm body or email template lets the operator immediately trace the event in the history screen right after receiving the alarm.
제목: [긴급] 모터 과열 — ${metadata.asset_id}
본문:
시각: ${metadata.ts}
값: ${data.value}°C
trace: ${metadata.trace_id}
이력 보기: https://platform.example.com/flow/log?trace_id=${metadata.trace_id}
Trace Retention Period
| Data | Retention Period |
|---|---|
| trace_id and per-node span logs | 7 days (same as execution history) |
| External storage (long-term retention) | Use external system mirroring under Audit/History Tracking |
If the trace_id is too long and message size is a burden, you can create a short format exposing only the last 4 characters (like
tr-...d4) withflow_script_transformfor use in alarms/emails. However, the full ID is needed for search.
Graph Pattern Catalog
10 commonly used wiring patterns in flow graphs.
Pattern 1 — Pipeline (Simple Serial)
[trigger] → [filter] → [transform] → [action]
| Characteristic | Message passes through nodes in order | | Use case | Threshold exceeded alarm → send email |
Pattern 2 — Fan-out (1 to N)
                     ┌─→ [action 1]
[trigger] → [t] ─────┼─→ [action 2]
                     └─→ [action 3]
| Characteristic | One message processed by multiple actions simultaneously | | Use case | Alarm occurs → email + SMS + Slack + create work order |
Copies of the same message are distributed to multiple nodes. Each branch is processed independently; one branch's failure doesn't affect other branches.
Pattern 3 — Fan-in (N to 1) — Merge
[trigger A] ──┐
[trigger B] ──┼─→ [flow_merge] → [aggregator] → [action]
[trigger C] ──┘
| Characteristic | Collects messages from multiple triggers within a time window and processes them at once | | Use case | Combine all alarms occurring over 5 minutes into a single daily report |
Pattern 4 — Scatter-Gather (Distribute → Collect)
[trigger] → [split] ─┬─→ [process] ──┐
                     ├─→ [process] ──┼─→ [merge] → [action]
                     └─→ [process] ──┘
| Characteristic | Split an array into per-element processing, then re-aggregate results | | Use case | Validate 100 external orders in parallel, then bulk-report results |
Pattern 5 — Switch (Conditional Branching)
                            ┌─[CRITICAL]→ [긴급 알람]
[trigger] → [flow_switch] ──┼─[WARN]    → [경고 알람]
                            └─[NORMAL]  → [통과]
| Characteristic | Route one message to different paths per condition | | Use case | Separate processing channel by alarm priority |
Pattern 6 — Retry with Fallback
[risky] ─[FAILURE]─→ [flow_retry] ─[SUCCESS]─→ (다시 risky)
                                  └[EXHAUSTED]→ [fallback action]
| Characteristic | Auto-retry transient failures, alternative processing for permanent failures | | Use case | Retry an external API 3 times on failure, notify a person if it still fails |
Pattern 7 — Circuit Breaker (Using Circuit Breaking)
[trigger] → [throttle] → [external_io] ─[SUCCESS]─→ [save]
                                       └[FAILURE]─→ [log only]
| Characteristic | Limit call rate with flow_throttle + bulk-block with the circuit breaker |
| Use case | Protect against overload on an external system |
Pattern 8 — Dead Letter Queue (DLQ)
[main flow] ─[FAILURE]─→ [flow_save_attributes] → 별도 자산에 적재
                                                  ↑
                              운영자가 주기적 점검 후 수동 재처리
| Characteristic | Send permanently failed messages to a separate store | | Use case | Collect messages that failed external ERP sync (targets for manual reprocessing) |
Pattern 9 — Sliding Window Aggregation
[trigger] → [flow_throttle 60s] → [transform: 누적] → [action]
                                  (마지막 60건만 유지)
| Characteristic | Decide based on state within a window of the last N items | | Use case | Enter site emergency mode if there are more than 30 alarms in the last 5 minutes |
Pattern 10 — Saga (Multi-Stage Transaction)
[start] → [step1] ─OK→ [step2] ─OK→ [step3] ─OK→ [complete]
              │            │            │
              └─FAIL→[rollback1]        │
                           │            │
                           ┌─FAIL→[rollback1+2]
                                        │
                                        └─FAIL→[rollback1+2+3]
| Characteristic | Handle partial failures of work spanning multiple external systems via compensation | | Use case | Create work order → reserve asset → sync ERP → notify worker (cancel all prior steps if one step fails) |
Pattern Selection Guide
| Requirement | Recommended Pattern |
|---|---|
| Simple threshold alarm | Pipeline (1) |
| One event → multiple channels | Fan-out (2) |
| Multiple events → one summary | Fan-in/Merge (3) |
| Bulk array processing | Scatter-Gather (4) |
| Branching handling | Switch (5) |
| External API reliability | Retry (6) |
| External system protection | Circuit (7) |
| Retain failed messages | DLQ (8) |
| Decision based on recent N accumulated | Sliding (9) |
| Consistency across multiple external systems | Saga (10) |
Flow Testing Best Practices
Testing strategy for safely changing and deploying flows.
3-Stage Testing — Unit → Integration → Simulation
| Stage | Tool | What's Verified |
|---|---|---|
| ① Unit | Edit screen ▶ Test Run | Single node's standalone behavior (script expression, external call response) |
| ② Integration | Same screen, temporary payload + live debug ON | Entire graph sequence/branching |
| ③ Simulation | Deployed + waiting for real triggers (staging environment) | Real message flow · integration with external systems |
Test Run Payload Library
Refer to the Payload Examples by Trigger section for trigger-specific payload examples to paste into the Test Run dialog. Also prepare boundary cases that frequently occur in production.
Boundary Case Examples
| Case | Payload |
|---|---|
| null field | {"value": null} — whether the script is null-safe |
| Empty string | {"value": ""} — verify whether an empty string is interpreted as 0 |
| Negative number | {"value": -1} — whether threshold checks work as intended with ± sign |
| Huge number | {"value": 1e20} — overflow/precision |
| Unicode | {"name": "한글-Émoji-🚀"} — external system encoding |
Safe Change Procedure
1. 기존 플로우를 [내보내기] (JSON 파일 저장)
2. 새 플로우를 사본으로 만듦 (이름 끝에 `_v2`)
3. 사본의 트리거 패턴을 좁혀 일부 자산만 매칭 (예: TEST-* 사이트만)
4. 신구 동시 배포 — 새 버전 데이터 확인
5. 1주일 안정성 검증 후 신 버전을 전체 트리거 패턴으로 변경
6. 구 버전 해제 + 보관
Keeping Regression Test Scenarios
Keep frequently used scenarios in a text file, and re-run them after each change.
# regression-tests/alarm-to-workorder.json
{
  "case": "고온 알람 → 워크오더 자동 생성",
  "input": {
    "type": "TAG_ALARM",
    "data": { "alarm_band": "HI_HI", "value": 95.0 }, ...
  },
  "expected": {
    "domain_changes": ["WorkOrder.CREATED"],
    "notifications": ["email:admin@example.com"]
  }
}
External System Mock Patterns
To mock external system responses in a staging environment:
| Method | Description |
|---|---|
| Point flow_http_request's url to a mock server | Separate production URL as a staging URL variable |
| Change flow_jdbc_poll's datasource | Change only from production DB → staging DB |
| Set flow_send_email's to_field to fake@example.com | Prevent accidental sends |
Load Testing After Resetting Counters
- Reset counters (all) for the new version flow
- Fire normal triggers for 5 minutes
- Check processing/error counts and average processing time on the list screen
- If p95 processing time increases over 20% compared to previous, analyze the cause and consider rollback
Performance Limits and Tuning
Processing limits and tuning tips for the flow engine.
Default Limits
| Item | Default | Notes |
|---|---|---|
Number of node visits per message (max_depth) | 100 | Forced termination if not finished within 100 nodes |
Same-node revisit count (max_revisit) | 3 | Prevents infinite cycle loops |
Flow processing time (flow_timeout_ms) | 30,000ms | Forced termination if one message's processing exceeds 30 seconds |
| External IO node timeout | 5,000ms (timeout_ms) | HTTP/Kafka/MQTT, etc. |
| Script execution timeout | 500ms (timeout_ms) | Per-node |
| Execution history retention | 7 days | Auto-expires afterward |
Recommended Common Window Sizes
| Node | Recommended Window | Notes |
|---|---|---|
flow_throttle | 1,000~60,000ms | Match to external system API limits |
flow_debounce | 500~5,000ms | When you want only stable values to pass through |
flow_merge | 5,000~60,000ms | Too short causes fragmentation, too long increases latency |
flow_retry backoff | Start 1,000ms × 2x | 5 retries would be 1·2·4·8·16 seconds |
Ways to Increase Throughput
- Trigger pre-filter — enter only necessary messages via
*_pattern(most effective) - Simplify graph via subflows — main graph handles only branching/routing, heavy processing goes to subflows
- Wire external IO asynchronously — flatten external API load with
flow_delay/flow_throttle - Debug mode only during verification — turn off debug mode after operations stabilize
- Wire only the necessary categories — don't necessarily wire heavy nodes like Edge/external integration into every branch
Message Size
The data / metadata of a message is JSON-serialized and stored in execution history. For huge payloads (multi-MB response bodies, etc.), extract only the needed keys with a transform node where possible. Message size is proportional to processing cost across history retention, debug display, and subflow invocation.
Audit/History Tracking
Where to check when tracing changes and execution history for flows.
Graph Change History
- Auto-snapshot — stored per version on every graph save. Ask an administrator to revert to a previous state.
- Modifier/modification time — the Last Modified column on the list screen shows the most recent save time. The modifier is recorded based on the system-authenticated user.
- Recommended to log change reasons — recording change reasons, responsible person, and related ticket numbers in the flow meta's Description field improves traceability.
Tracking Execution Events
- Message ID tracking — using the Message ID filter on the execution history screen, you can view the entire flow of a single message (
FLOW_START→ allNODE_IN/NODE_OUT→FLOW_END) chronologically. - CSV export — the CSV Download button on the execution history screen lets you export the current query results for delivery to an external audit system.
Domain Change History
Since domain changes performed by a flow's action nodes (flow_create_* / flow_update_* / flow_delete_*) are all delegated to the same domain service, they're also recorded in the domain-specific change history on the back-office screen. The worker ID is marked with something like insert_user_id="flow" to distinguish it from regular user changes.
Long-Term Storage via External Loading
For long-term storage exceeding the retention period (7 days) of execution history, build a separate flow to load key events into an external system (Kafka, external DB, etc.).
[flow_on_tag_alarm]
   │
   ▼
[flow_kafka_publish: topic=audit.alarm.events]
New Flow Deployment Checklist
Items to check before deploying a new flow to production.
Graph Structure
- Is exactly one trigger node (or intentional multiple) wired?
- Is the
FAILUREoutput of all action nodes handled (at minimum withflow_log)? - If a cycle exists, is it an intended wiring like
flow_retry, and is it withinmax_revisitprotection? - Is
retry_count/retry_delay_msorflow_retrywired for external IO nodes?
Node Settings
- Is the trigger's
*_patterntoo narrow or too broad? - Does the
*_fielddynamic option path actually exist in the message? - Are all NOT NULL fields of Create nodes filled in (beyond auto-backfill)?
- Is partial update the intended behavior of Update nodes?
Verification & Testing
- Passed once via SUCCESS branch with a normal payload
- Passed via FAILURE branch with an abnormal payload (missing required fields, etc.)
- Passed via Retry → EXHAUSTED branch for an external IO failure case (if applicable)
- The INFO/ERROR display in the live debug panel matches intention
- Are all stages recorded in the
/flow/logscreen?
Operational Safety
- Is a backup (graph JSON export) stored externally?
- Is the change reason/responsible person recorded in the flow description?
- If there's a notification (Email/SMS/Push) wiring, has the recipient been verified?
- Is there a monitoring plan for the execution history for 5-10 minutes right after deployment?
Deployment Strategies — Canary / Blue-Green / A·B Testing
3 strategies for safely releasing a new flow. All strategies can be implemented with just the platform's basic features (trigger patterns, message dispatch, live debug).
Strategy 1 — Canary (Progressive Application to Some Assets Only)
Apply a new flow to some assets first, observe for a period, then expand to all.
[1단계 출시]
  새 플로우 v2 — 트리거 패턴: asset_id LIKE 'LINE-1.%'  (1개 라인만)
  기존 플로우 v1 — 트리거 패턴: asset_id LIKE 'LINE-2.%' OR 'LINE-3.%' OR ...

[2단계 확대 (1주일 후 안정 확인)]
  v2 패턴: 'LINE-1.%' OR 'LINE-2.%'
  v1 패턴: 'LINE-3.%' OR 'LINE-4.%'

[3단계 전체 (2주 후)]
  v2 패턴: '%'   ← 모든 자산
  v1 해제·보관
Canary Rollout Checklist
| Period | Monitoring Item |
|---|---|
| Day 1 | Error rate < 1% / average processing time within ±20% of existing |
| 1 week | External system integration 100% normal / appropriate alarm occurrence frequency |
| 2 weeks | Cumulative statistics / user feedback / decide next line expansion |
For the canary line, choose a line with relatively low impact even among operating lines (one with high maintenance frequency or that only runs at night, etc.).
Strategy 2 — Blue-Green (Run Old & New Simultaneously, Then Immediate Switch)
[Blue (현재)]                       [Green (새 버전)]
플로우 v1 — 배포됨                  플로우 v2 — 배포 + 격리된 originator
모든 트리거 처리                    metadata.test_mode=true 인 메시지만 처리

[전환 결정 시점]
   v2 트리거 패턴을 v1 과 동일하게 변경 (1초)
   v1 해제 토글 (1초)
The core of Blue-Green is immediate switching while both versions are deployed simultaneously — if a problem is found, immediately redeploy v1 to roll back.
v2 Isolation Wiring Pattern
[trigger 모든 메시지]
   ↓
[flow_script_filter — metadata.test_mode === true]
   ↓ TRUE
[새 로직]
Send test messages via the /flow/{id}/run API specifying metadata.test_mode=true.
Strategy 3 — A/B Testing (Compare Performance/Results)
Both versions receive the same message, then take different actions, and compare results.
[trigger 메시지]
   ↓
[flow_split (메시지 복제)]
   ├ A 경로 → 기존 v1 액션 → [flow_save_attributes target=stats_v1]
   └ B 경로 → 새 v2 액션  → [flow_save_attributes target=stats_v2]
Afterward, compare cumulative results of stats_v1 vs stats_v2 on the daily statistics screen.
Automated A/B Comparison Analysis
-- EQL 으로 두 버전 비교 (예: 알람 생성 누적)
context EVERY_1_HOURS
SELECT
  count(CASE WHEN metadata.flow_version='v1' THEN 1 END) AS v1_count,
  count(CASE WHEN metadata.flow_version='v2' THEN 1 END) AS v2_count
FROM AssetAlarm.win:time(1 hour)
Strategy Selection Guide
| Situation | Recommended Strategy |
|---|---|
| First release of a new automation scenario | Canary — verify on one line then expand |
| Major change to existing logic (structural reorganization) | Blue-Green — allows immediate rollback |
| Measuring which of two algorithms is better | A/B Testing |
| Simple option value adjustment | Direct change — write a metadata.audit_diff note then monitor for a week |
Rollback Procedure (Common)
Immediate rollback upon finding an issue:
- Undeploy toggle for the new version on the list screen
- (For Canary/A·B) Change the trigger pattern to match 0 cases
- Monitor for 5 minutes to confirm the existing version operates alone
- Confirm there's no
code=FLOW_NOT_DEPLOYEDin diagnostic logs - Root-cause analysis — trace failed messages with
trace_idin execution history
Pre-Release Checklist (Condensed)
Core items only from New Flow Deployment Checklist in one view:
[ ] 테스트 실행으로 정상·경계·실패 시나리오 모두 통과
[ ] 외부 IO 노드에 timeout_ms / 재시도 정책 설정됨
[ ] 자격 증명은 ${creds.*} 참조 (평문 미포함)
[ ] 트리거 패턴이 의도한 자산만 매칭
[ ] 영향받는 도메인 (자산/태그/주문) 식별됨
[ ] 운영 시간(특히 야간) 영향 검토됨
[ ] 롤백 시점·기준·담당자 결정됨
[ ] [감사 로그](#audithistory-tracking) 에 변경 의도 메모 작성됨
Node Quick Configuration Reference
A cheat sheet gathering only the key settings for frequently used nodes during operation.
Trigger Quick Settings
| Node | Key Options |
|---|---|
flow_schedule | cron (e.g., 0 */5 * * * ? = every 5 min), or interval_ms |
flow_on_webhook | No options — fires externally via POST /webhook/flow/{flow_id} |
flow_on_mqtt_subscribe | broker_url, topic, client_id, username/password |
flow_jdbc_poll | dsn, sql, interval_ms |
flow_on_* (domain) | *_pattern (glob — MOTOR-*, SITE-?, etc.) |
Transform Quick Settings
| Node | Key Options |
|---|---|
flow_script_transform | language (JS/EQL), script, timeout_ms (default 500) |
flow_change_originator | entity_type, id_field |
flow_rename_keys | mapping (e.g., {"old":"new"}) |
flow_template | template (substitution of ${data.x}/${metadata.y}) |
flow_split | path (array location, default data) |
flow_to_email | subject_template, body_template |
Flow Control Quick Settings
| Node | Key Options |
|---|---|
flow_delay | delay_ms |
flow_throttle | max_msgs, window_ms, (branches: SUCCESS/THROTTLED) |
flow_debounce | window_ms |
flow_merge | window_ms (accumulated into data.merged array) |
flow_subflow | target_flow_id |
flow_retry | max_attempts (default 3), backoff_ms (default 1000), backoff_multiplier (default 2.0) |
flow_log | level (INFO/WARN/ERROR), prefix |
flow_noop | (no options) |
External Integration Quick Settings
| Node | Static Options | Dynamic Options (*_field) |
|---|---|---|
flow_http_request | method, url, headers, body_template, timeout_ms, retry_count, retry_delay_ms | url_field, method_field, body_field |
flow_kafka_publish | bootstrap_servers, topic, value_template, headers | topic_field, key_field |
flow_mqtt_publish | broker_url, topic, qos | topic_field |
flow_webhook_callback | url, method, headers | url_field |
flow_send_email | to, cc, subject, body | to_field, cc_field, subject_field, body_field |
flow_send_sms | to, text | to_field, text_field |
flow_send_push | title, body | title_field, body_field |
flow_jdbc_query | dsn, sql, params_field | — |
Action — Integration/Storage Quick Settings
| Node | Key Options |
|---|---|
flow_save_tag_point | tag_id_field (default metadata.tag_id), value_field, timestamp_field |
flow_save_attributes | entity_type_field, id_field, attributes_field |
flow_dds_publish | type, originator_field, payload_field |
flow_publish_asset_event | asset_id_field, event_type_field, severity_field, details_field |
flow_publish_asset_command | asset_id_field, tag_id, cmd_key_field, payload_field |
Domain CRUD Quick Settings
| Node | Key Options |
|---|---|
flow_create_* | Domain-specific fields + *_field dynamic option. NOT NULL fields are partially auto-backfilled (see the Domain CRUD table for auto-backfilled items) |
flow_update_* | Partial update: only entered fields update, empty values ignored. Full overwrite requires a Delete + Create combination |
flow_delete_* | *_id_field |
flow_start/end/pause/resume_work_order | order_id_field (default data.order_id) |
flow_abort_work_order | + abort_code_field, abort_notes_field |
flow_update_tag_alarm_band_numeric | tag_id_field, hi_field, etc. (only entered fields update) |
Edge Quick Settings
All edge nodes use the same set of options.
| Option | Description |
|---|---|
url | Edge REST endpoint (e.g., http://edge.local:60000/opc/server) |
method | HTTP method (defaults per node if unset) |
headers | JSON headers (auth token, etc.) |
body_template | Request body (sent as data as-is if unset) |
timeout_ms | 5000 |
Flow REST API — Manipulating Flows Programmatically
A REST API used to manage flows as code from external automation tools (Ansible/GitOps/CI pipelines), or to have external systems immediately execute a flow.
Authentication
All API calls attach as a header the token issued from Security → API Auth Token.
Authorization: Bearer {api_token}
Endpoint List
1) List Flows
GET /flow/list
curl -H "Authorization: Bearer ${TOKEN}" \
     https://platform.example.com/flow/list
Response:
{
  "data": [
    { "flow_id": "flow-abc123", "flow_name": "MES 동기화", "deployed": true,
      "node_count": 12, "exec_count": 9430, "error_count": 2, "last_exec_at": 1746247200000 },
    ...
  ]
}
2) Query a Single Flow
GET /flow/get/{flow_id}
The response body includes all graph nodes, relations, and options. Directly usable for backup/version control.
3) Create a Flow
POST /flow/create
Content-Type: application/json

{
  "flow_name":        "신규 자동화",
  "description":     "외부 알림 → 워크오더 자동 생성",
  "deployed":         false
}
Take flow_id from the response for use in subsequent calls.
4) Edit Flow (Meta)
POST /flow/update
Content-Type: application/json

{
  "flow_id":     "flow-abc123",
  "flow_name":   "수정된 이름",
  "description": "..."
}
5) Save Graph (Bulk Replace Nodes/Relations)
POST /flow/{flow_id}/graph
Content-Type: application/json

{
  "nodes":     [ { "node_id": "n1", "type": "flow_on_tag_point", "options": {...}, "x": 100, "y": 100 }, ... ],
  "relations": [ { "from_node_id": "n1", "to_node_id": "n2", "relation": "TRUE" }, ... ]
}
Graph save is transactional — if validation fails, the entire graph is rolled back.
6) Deploy / Undeploy
Changing the deployed field of the flow meta automatically deploys/undeploys.
# 배포
curl -X POST -H "Authorization: Bearer ${TOKEN}" -H "Content-Type: application/json" \
     -d '{"flow_id":"flow-abc123","deployed":true}' \
     https://platform.example.com/flow/update
7) Immediate Execution (Manual Trigger)
POST /flow/{flow_id}/run
Content-Type: application/json

{
  "type":       "WEBHOOK",
  "originator": { "entity_type": "External", "id": "manual-run" },
  "data":       { "test": true }
}
Executes immediately from the first node, bypassing the trigger node's pre-filter. Useful for manual verification/debugging.
8) Dispatch (Trigger Bypass Firing)
POST /flow/dispatch
Content-Type: application/json

{
  "type":       "POST_TELEMETRY",
  "originator": { "entity_type": "Tag", "id": "MOTOR-001.SPEED" },
  "data":       { "value": 1500 },
  "metadata":   { "tag_id": "MOTOR-001.SPEED", "ts": 1746247200000 }
}
Injects the message into the normal trigger processing path — all flows matching that message fire simultaneously.
9) Reset Statistics
POST /flow/{flow_id}/stats/reset-errors        — 에러 카운트만 초기화
POST /flow/{flow_id}/stats/reset-all           — 전체 카운트 초기화
10) Export / Import — Graph Backup
# Export — JSON 파일로 다운로드
curl -H "Authorization: Bearer ${TOKEN}" \
     https://platform.example.com/flow/${FLOW_ID}/export \
     -o flow-backup.json

# Import — 같은 JSON 을 다른 환경에 등록
curl -X POST -H "Authorization: Bearer ${TOKEN}" -H "Content-Type: application/json" \
     --data @flow-backup.json \
     https://platform.example.com/flow/import
On import, a new ID is automatically issued if there's a conflicting ID. Please map external dependencies (credentials, asset IDs, etc.) separately after importing.
11) Redeploy All Flows
POST /flow/redeploy
Used for bulk sync after large-scale changes or after a node restart. Call during operation with caution — temporary processing delays occur.
12) Self-Diagnostics
POST /flow/selftest
Checks the flow engine's internal components (trigger queue, dispatcher, node registry, script runtime) once and returns status. Results are also recorded in the diagnostic log.
13) Query Node Catalog
GET /flow/catalog
Returns the schema of options and all currently registered node types. Used by the UI to dynamically generate the inspector. Also referenced when an external tool automatically generates a graph.
Firing Externally via a Webhook Trigger
A flow containing an flow_on_webhook trigger can be fired directly by an external system via the following URL.
POST /webhook/flow/{flow_id}
Authorization: Bearer {token}    또는    X-API-Key: {token}
Content-Type:  application/json

{
  "order_no":  "PO-001",
  "customer":  "ACME",
  "quantity":  1000
}
Response:
{ "status": "ACCEPTED", "trace_id": "tr-..." }
| Response Code | Meaning |
|---|---|
| 200 | Message enqueued into the queue (actual processing result is asynchronous) |
| 401 | Authentication token wrong/missing |
| 404 | Flow ID not found or not deployed |
| 413 | Body exceeds 256KB |
| 422 | Trigger node is not flow_on_webhook |
| 429 | Per-minute call limit exceeded |
External Automation Tool Integration Examples
GitHub Actions — Deploy Flow on PR Merge
- name: 플로우 배포
  run: |
    curl -X POST \
      -H "Authorization: Bearer ${{ secrets.PP_TOKEN }}" \
      -H "Content-Type: application/json" \
      --data @flows/mes-sync.json \
      https://platform.example.com/flow/import
Ansible — Batch Flow Management
- name: 모든 플로우 백업
  uri:
    url: "https://platform.example.com/flow/{{ item }}/export"
    headers:
      Authorization: "Bearer {{ pp_token }}"
    dest: "/backups/{{ item }}.json"
  loop: "{{ pp_flow_ids }}"
Jenkins — Selftest on Every New Build
stage('PlantPulse Flow Selftest') {
  steps {
    sh """
      curl -X POST -H 'Authorization: Bearer ${PP_TOKEN}' \\
           https://platform.example.com/flow/selftest \\
           --fail-with-body
    """
  }
}
API Rate Limit
| Endpoint | Per-Minute Limit (per token) |
|---|---|
GET /flow/list · get · catalog | 600 |
POST /flow/create · update · delete | 60 |
POST /flow/{id}/run · dispatch · webhook/{id} | 1,000 |
POST /flow/redeploy · selftest | 10 |
A 429 Too Many Requests response is returned on exceeding the limit.
OPC/PLC Industrial Integration Patterns
A collection of integration scenarios unique to industrial fields. Combines 22 edge node types with 4 asset event publishing types.
Pattern A — Automatic OPC Server Registration
Automatically registers an OPC server to the edge based on line information received from ERP when a new line goes into operation.
[flow_on_webhook]
   ↓ (data = {"line_id":"LINE-7","host":"10.0.7.10","port":4840})
[flow_change_originator]
   ↓ (originator → Edge:EDGE-A)
[flow_edge_opc_create]
   ↓ (path=/api/v1/opc, body={"opc_id":"OPC-${data.line_id}","host":"${data.host}","port":${data.port}})
[flow_edge_opc_start]
   ↓ (수집 시작 명령)
[flow_save_attributes]
   ↓ (등록 이력을 자산 메타에 기록)
The edge node automatically looks up
api_keyfrom themm_edgemaster table. The operator doesn't need to set up separate authentication.
Pattern B — Automatic PLC Command Publishing
Automatically publishes a stop command to a PLC when an asset alarm occurs.
[flow_on_asset_alarm]
   ↓ where priority='ERROR' AND alarm_band='TRIP_HI'
[flow_publish_asset_command]
   ↓ (event_type='STOP', payload={"reason":"trip_high","triggered_by":"flow"})
[flow_log] (감사 로그)
flow_publish_asset_commandis delivered immediately to the asset's command topic (asset/{id}/cmd/STOP), causing the edge to perform an OPC Write to the PLC.
Pattern C — Bulk OPC Tag Registration (CSV/Excel Ingestion)
Registers 100-1000 tags from a CSV all at once during new equipment setup.
[flow_jdbc_poll]            ← 외부 DB 에 적재된 CSV 행
   ↓ (한 행 = 한 메시지)
[flow_script_transform]     ← 태그 정의 가공
   ↓
[flow_create_tag]           ← 도메인 등록 (NOT NULL 자동 보강)
   ↓
[flow_edge_tag_create]      ← 엣지에 동기화
   ↓
[flow_log] (성공 카운트)
When registering 1,000 items, it's recommended to flatten the rate to 100 or fewer per minute with
flow_throttle. The edge may temporarily respond slowly.
Pattern D — Automatic OPC Disconnection Recovery
Automatically restarts when an OPC connection is disconnected then recovers.
[flow_on_opc_status]
   ↓ where prev_status='CONNECTED' AND status='DISCONNECTED'
[flow_delay 30s]            ← 잠시 안정화 대기
   ↓
[flow_edge_opc_start]       ← 수집 재시작 시도
   ↓ SUCCESS: 정상
   └ FAILURE: [flow_retry max=3] → EXHAUSTED: [관리자 알림]
Pattern E — Line Status Check at Shift Start
Checks all lines of a site at each shift start time.
[flow_schedule cron='0 0 7,15,23 * * ?']   ← 7시·15시·23시
   ↓
[flow_edge_monitoring]      ← 엣지에서 OPC 상태 전체 조회
   ↓ data.opcs = [...]
[flow_split]                ← 배열을 행별 메시지로
   ↓
[flow_script_filter]        ← status != 'CONNECTED' 만
   ↓
[flow_send_email]           ← 비정상 OPC 만 한 통의 메일에 합쳐 발송
Pattern F — Automatic Worker Mapping on Shift Change
Automatically maps workers to work orders per work schedule changes.
[flow_on_entity_event type='ENTITY_UPDATED' Calendar]
   ↓
[flow_script_filter (시프트 시작 시각이 지금인 경우만)]
   ↓
[flow_jdbc_query (그 시프트의 작업자 목록 조회)]
   ↓ data.employees=[...]
[flow_split]
   ↓
[flow_update_work_order (작업자 매핑)]
Pattern G — Multiple PLC Calls Simultaneously (Scatter-Gather)
Calls data from multiple PLCs simultaneously then integrates results.
[flow_on_webhook]
   ↓ data.targets=['PLC-1','PLC-2','PLC-3']
[flow_split]
   ↓ (3개로 분할)
[flow_edge_tag_read]
   ↓ (병렬 호출)
[flow_merge window=5s]
   ↓ data.merged=[...]
[flow_script_transform (data.summary 만들기)]
   ↓
[flow_publish_asset_aggregation]
Pattern H — Alarm Band Auto-Adjustment
Automatically applies the learned LIMIT_MIN/MAX values from Predictive Analysis to alarm bands.
[flow_schedule cron='0 0 4 * * MON']    ← 매주 월요일 4시
   ↓
[flow_jdbc_query (forecast 결과 조회)]
   ↓ data.tags=[{tag_id, limit_min, limit_max}]
[flow_split]
   ↓
[flow_update_tag_alarm_band_numeric]    ← lo=limit_min, hi=limit_max
   ↓ SUCCESS
[flow_log] (적용 결과 기록)
Pattern I — Automatic Downtime Classification
Classifies asset stop events by reason to accurately reflect them in OEE availability.
[flow_on_asset_event event_type='SHUTDOWN']
   ↓
[flow_switch]
   ├ CASE 점심: hour_of_day(ts) BETWEEN 12 AND 13 → [flow_create_calendar (계획정지)]
   ├ CASE 시프트 종료: 시프트 종료 시각 ±5분    → [flow_log (정상 종료)]
   ├ CASE 정기점검: 마지막 정비일 +30일 경과     → [flow_create_calendar (정기점검)]
   └ DEFAULT (비계획)                            → [flow_send_email (긴급)]
Pattern J — Bidirectional Work Order Sync with External ERP
PlantPulse ↔ external ERP bidirectional mirroring.
입력 1: ERP → 플랜트펄스
[flow_on_webhook] → [flow_create_work_order]

입력 2: 플랜트펄스 → ERP
[flow_on_entity_event type='ENTITY_CREATED' WorkOrder]
  → [flow_script_filter (출처가 ERP 가 아닌 경우만)]
  → [flow_http_request (ERP REST PUT)]
To prevent infinite loops, mark messages coming in from outside with
metadata.source='ERP', and filter that message in the flow going in the opposite direction.
Precautions for Industrial Integration
| Item | Recommendation |
|---|---|
| Publish OPC Write commands after a safety interlock | Only after operator confirmation or passing an automatic safety rule |
| Don't set the PLC polling interval too short | Below 1 second risks a spike in PLC CPU usage |
| Edge device Docker container resource limits | Watch for CPU/memory over 80% when OPC collection + additional containers are running |
| During commissioning, run all commands in dry-run mode | Use the dry_run=true option of flow_edge_tag_write |
| Prepare for power outages — trust only persistent storage triggers | flow_on_webhook, etc. are volatile; domain event triggers are persistent |
External System Integration Cookbook
A collection of flow_http_request settings and payload examples for frequently called external systems.
Slack — Incoming Webhook Notification
URL:    https://hooks.slack.com/services/T0000/B0000/{secret}
Method: POST
Headers:
  Content-Type: application/json
Body (body_template):
  {
    "text": "${data.title}",
    "blocks": [
      { "type": "header",  "text": { "type": "plain_text", "text": "${data.title}" } },
      { "type": "section", "text": { "type": "mrkdwn",     "text": "*자산:* ${metadata.asset_id}\n*값:* ${data.value}\n*시각:* ${metadata.ts}" } }
    ]
  }
- Success: 200 +
okbody - Failure: 400 (invalid payload) / 404 (wrong secret) / 429 (per-minute call limit exceeded)
- Recommendation: wire
flow_throttleat 1/minute or less
Microsoft Teams — Webhook Notification
URL:    https://{org}.webhook.office.com/webhookb2/{id}/IncomingWebhook/{secret}
Method: POST
Headers:
  Content-Type: application/json
Body:
  {
    "@type":    "MessageCard",
    "@context": "https://schema.org/extensions",
    "themeColor": "FF0000",
    "title": "${data.title}",
    "sections": [{
      "facts": [
        { "name": "자산", "value": "${metadata.asset_id}" },
        { "name": "값",   "value": "${data.value}"       },
        { "name": "시각", "value": "${metadata.ts}"      }
      ]
    }]
  }
Branch
themeColorintoFF0000(red)/FFA500(orange)/00C853(green) to visualize priority.
Jira — Automatic Issue Creation
URL:    https://{org}.atlassian.net/rest/api/3/issue
Method: POST
Headers:
  Authorization: Basic {base64(email:apitoken)}
  Content-Type:  application/json
Body:
  {
    "fields": {
      "project":    { "key": "OPS" },
      "summary":    "[자동] ${data.title}",
      "description": {
        "type": "doc",
        "version": 1,
        "content": [{
          "type": "paragraph",
          "content": [{ "type": "text", "text": "자산: ${metadata.asset_id}\n값: ${data.value}" }]
        }]
      },
      "issuetype":  { "name": "Bug" },
      "priority":   { "name": "High" }
    }
  }
- The issue key like
OPS-1234comes into the response body'sdata.response_body.key, so make use of it in subsequent nodes - Failure: 400 (invalid field) / 401 (auth) / 403 (no project permission)
GitHub Issues — Automatic Issue Creation
URL:    https://api.github.com/repos/{owner}/{repo}/issues
Method: POST
Headers:
  Authorization: Bearer {pat_token}
  Accept:        application/vnd.github+json
Body:
  {
    "title":  "[자동] ${data.title}",
    "body":   "자산: ${metadata.asset_id}\n값: ${data.value}\n시각: ${metadata.ts}\ntrace: ${metadata.trace_id}",
    "labels": ["automation", "ops"]
  }
ERP (SAP S/4HANA OData) — Issuing a Work Order
URL:    https://{host}/sap/opu/odata/sap/API_MAINTNOTIFICATION/MaintenanceNotification
Method: POST
Headers:
  Authorization:   Basic {base64(user:pass)}
  X-CSRF-Token:    fetch          ← 별도 GET 으로 토큰 받기
  Content-Type:    application/json
Body:
  {
    "NotificationType":         "M2",
    "MaintenanceNotificationType": "M2",
    "TechnicalObject":          "${metadata.asset_id}",
    "NotificationText":         "${data.title}",
    "MalfunctionStartDate":     "${data.start_date}",
    "Priority":                 "${data.priority}"
  }
The CSRF token must first be obtained via GET, then POST'd with the same session cookie. Wire two
flow_http_requestnodes so the token from the first node's response header propagates as the second node's header.
MES (Direct External DB INSERT) — flow_jdbc_query
Directly inserts a row into an external MES system's work order table.
INSERT INTO mes.work_order
  (order_no, asset_id, product_id, qty, status, due_date, created_by)
VALUES
  (:order_no, :asset_id, :product_id, :qty, 'NEW', :due_date, 'flow')
| Node Option | Value |
|---|---|
datasource_id | mes_db (pre-registered in system settings) |
query | Above SQL |
binds | {"order_no":"${data.order_no}","asset_id":"${metadata.asset_id}",...} |
flow_jdbc_querysupports INSERT/UPDATE/DELETE in addition to SELECT. Transactions are automatically committed/rolled back per node.
Grafana — Automatic Dashboard Refresh Notification
URL:    https://{host}/api/annotations
Method: POST
Headers:
  Authorization: Bearer {api_key}
  Content-Type:  application/json
Body:
  {
    "dashboardUID": "...",
    "panelId":      4,
    "time":         ${metadata.ts},
    "tags":         ["alarm", "${metadata.asset_id}"],
    "text":         "${data.title}"
  }
A marker automatically appears on the graph when an alarm occurs — very useful for post-hoc analysis.
Telegram — Bot Messages
URL:    https://api.telegram.org/bot{token}/sendMessage
Method: POST
Body:
  {
    "chat_id": "-1001234567890",
    "text":    "🚨 *${data.title}*\n자산: `${metadata.asset_id}`\n값: ${data.value}",
    "parse_mode": "Markdown"
  }
REST Authentication Pattern Quick Table
| Auth Method | Header |
|---|---|
| API Key (header) | X-API-Key: {token} |
| API Key (query) | ?api_key={token} at the end of the URL |
| Bearer Token | Authorization: Bearer {token} |
| Basic Auth | Authorization: Basic {base64(user:pass)} |
| OAuth2 (Client Credentials) | issue a token → Bearer header (renew via a separate node) |
| HMAC Signature | compute a body/time-based signature via a script into the X-Signature header |
Response Parsing Pattern
Use data.response_body in a following node after a flow_http_request response:
// 응답에서 ID 추출
data.created_id = data.response_body.id;
data.status     = data.response_body.status;

// 응답 배열에서 첫 행만
data.first_item = (data.response_body.items || [])[0] || null;

// 응답이 문자열이면 JSON 파싱
if (typeof data.response_body === 'string') {
  try { data.response_body = JSON.parse(data.response_body); } catch (e) {}
}
msg
Security Recommendations When Calling External Systems
| Item | Recommendation |
|---|---|
| Don't leave tokens as plain text in the graph | Register in System Settings → Credential Store, then reference like ${creds.slack_webhook} |
| If the response body contains sensitive information, mask it | Remove PII/tokens with flow_script_transform before passing to the next node |
| A separate retry policy per external system | Wire separate flow_retry + flow_throttle for high-frequency calls |
| Store call results as an audit log | Add call history meta to the asset with flow_save_attributes |
Data Transformation Cookbook
A collection of transformation patterns you can directly copy into the flow_script_transform node. All examples use JavaScript and the data / metadata shortcut aliases.
Unit Conversion
// 섭씨 → 화씨
data.temp_f = data.temp_c * 9 / 5 + 32;

// 바 → kPa
data.pressure_kpa = data.pressure_bar * 100;

// rpm → rad/s
data.angular_velocity = data.rpm * 2 * Math.PI / 60;

// kWh → MJ
data.energy_mj = data.energy_kwh * 3.6;

// 바이트 → MB (소수 1자리)
data.size_mb = Math.round(data.bytes / 1024 / 1024 * 10) / 10;

msg
Date/Time Conversion
const d = new Date(metadata.ts);

// ISO 8601 — 2026-05-12T12:34:56.789Z
data.iso = d.toISOString();

// 사람용 — 2026-05-12 21:34:56 (KST)
data.local = d.toLocaleString('ko-KR', { hour12: false });

// 날짜만 — 2026-05-12
data.date = d.toISOString().slice(0, 10);

// 시간만 — 21:34:56
data.time = d.toTimeString().slice(0, 8);

// 분 단위로 내림 (스파크라인 키)
data.minute_key = Math.floor(metadata.ts / 60000) * 60000;

// 시간 단위로 내림
data.hour_key = Math.floor(metadata.ts / 3600000) * 3600000;

// 한국 시간 (UTC+9) 직접 더하기 (서버 시간이 UTC 인 경우)
data.kst_hour = new Date(metadata.ts + 9 * 3600000).getUTCHours();

msg
String Normalization
// 공백 trim + 소문자화
data.normalized = (data.text || '').trim().toLowerCase();

// 한글·영문 외 제거 (특수문자/공백 정리)
data.clean = (data.text || '').replace(/[^가-힣a-zA-Z0-9]/g, '');

// camelCase → snake_case
data.snake = (data.text || '').replace(/([A-Z])/g, '_$1').toLowerCase().replace(/^_/, '');

// 전화번호 정규화 (숫자만)
data.phone_digits = (data.phone || '').replace(/\D/g, '');

// 한국 휴대전화 자동 포맷 (010-1234-5678)
const p = (data.phone || '').replace(/\D/g, '');
data.phone_formatted = p.length === 11 ? p.replace(/(\d{3})(\d{4})(\d{4})/, '$1-$2-$3') : p;

msg
Flattening Nested Objects
// data.location.address.city → data.city
function flatten(obj, prefix, out) {
  out = out || {};
  for (var k in obj) {
    var v = obj[k];
    var key = prefix ? prefix + '_' + k : k;
    if (v && typeof v === 'object' && !Array.isArray(v)) flatten(v, key, out);
    else out[key] = v;
  }
  return out;
}
data = flatten(data);
msg
Flat Object → Nested
// data.user_name + data.user_email → data.user = {...}
function unflatten(obj) {
  var out = {};
  for (var k in obj) {
    var parts = k.split('_');
    var cur = out;
    for (var i = 0; i < parts.length - 1; i++) {
      cur[parts[i]] = cur[parts[i]] || {};
      cur = cur[parts[i]];
    }
    cur[parts[parts.length - 1]] = obj[k];
  }
  return out;
}
data = unflatten(data);
msg
CSV Row Generation
// 외부 시스템에 CSV 한 줄 보낼 때
function csvEscape(v) {
  if (v === null || v === undefined) return '';
  v = String(v);
  return /[,"\n]/.test(v) ? '"' + v.replace(/"/g, '""') + '"' : v;
}
data.csv_row = [
  csvEscape(metadata.ts),
  csvEscape(metadata.asset_id),
  csvEscape(data.value),
  csvEscape(data.quality)
].join(',');
msg
Array Aggregation
var arr = data.values || [];

// 합·평균·최소·최대
data.sum = arr.reduce(function(a, b) { return a + b; }, 0);
data.avg = arr.length ? data.sum / arr.length : 0;
data.min = arr.length ? Math.min.apply(null, arr) : null;
data.max = arr.length ? Math.max.apply(null, arr) : null;

// 중앙값
var sorted = arr.slice().sort(function(a, b) { return a - b; });
var mid    = Math.floor(sorted.length / 2);
data.median = sorted.length === 0 ? null
            : sorted.length % 2 ? sorted[mid]
            : (sorted[mid - 1] + sorted[mid]) / 2;

msg
Conditional Field Addition (Schema Evolution)
// 알람 우선순위에 따라 색상·아이콘 자동 부여
var p = data.priority || 'INFO';
data.color   = { ERROR: '#d32f2f', WARN: '#f57c00', INFO: '#1976d2' }[p] || '#9e9e9e';
data.icon    = { ERROR: '🔴',       WARN: '🟠',       INFO: '🔵' }[p] || '⚪';
data.urgency = p === 'ERROR' ? 3 : p === 'WARN' ? 2 : 1;
msg
Masking Part of the Payload
function maskEmail(e) {
  if (!e || e.indexOf('@') < 0) return e;
  var parts = e.split('@');
  return parts[0].slice(0, 2) + '***@' + parts[1];
}
function maskPhone(p) {
  return (p || '').replace(/(\d{3})\d{4}(\d{4})/, '$1-****-$2');
}
data.user_email = maskEmail(data.user_email);
data.user_phone = maskPhone(data.user_phone);
msg
Multi-Language (i18n) Templates
// 메시지 본문을 사용자 로케일에 따라 분기
const tpl = {
  'ko-KR': '🚨 ${asset} 온도 ${value}°C 임계 초과',
  'en-US': '🚨 ${asset} temperature ${value}°C exceeds threshold',
  'ja-JP': '🚨 ${asset} 温度 ${value}°C 閾値超過'
};
const locale = metadata.user_locale || 'ko-KR';
const template = tpl[locale] || tpl['ko-KR'];
data.notification = template
  .replace('${asset}', metadata.asset_id)
  .replace('${value}', data.value);
msg
Safe JSON Path Lookup
// data.deep.nested.field 처럼 깊은 경로를 안전하게 조회
function get(obj, path, dflt) {
  var keys = path.split('.');
  var cur  = obj;
  for (var i = 0; i < keys.length; i++) {
    if (cur === null || cur === undefined) return dflt;
    cur = cur[keys[i]];
  }
  return cur === undefined ? dflt : cur;
}
data.city = get(data, 'location.address.city', 'Unknown');
msg
Message Merging (flow_merge Post-processing)
// flow_merge 가 data.merged 배열로 모은 메시지들을 1건으로 합침
var items = data.merged || [];
data.summary = {
  count:     items.length,
  first_ts:  items[0]?.metadata?.ts,
  last_ts:   items[items.length - 1]?.metadata?.ts,
  assets:    Array.from(new Set(items.map(function(m) { return m.metadata?.asset_id; }))),
  max_value: Math.max.apply(null, items.map(function(m) { return m.data?.value || 0 }))
};
delete data.merged;
msg
Reusable Script Collection
A script library you can directly copy into flow_script_filter / flow_script_transform / flow_switch nodes. All scripts use JavaScript and the data / metadata shortcut aliases.
Transform Scripts
Unit Conversion/Labeling
// 섭씨 → 화씨 + 등급 라벨
data.temp_f = data.temp * 1.8 + 32;
data.grade  = data.temp > 80 ? 'HIGH' : data.temp < 0 ? 'LOW' : 'OK';
msg
Time/Shift/Day-of-Week Meta Enrichment
const d = new Date(metadata.ts);
const h = d.getHours();
metadata.shift   = (h >= 6 && h < 14) ? 'A' : (h < 22) ? 'B' : 'C';
metadata.weekday = ['SUN','MON','TUE','WED','THU','FRI','SAT'][d.getDay()];
metadata.is_weekend = (d.getDay() === 0 || d.getDay() === 6);
msg
Average ± 3σ Alarm Band Calculation
const m = data.mean, s = data.stddev || 1;
data.tag_id = originator.id + '.TEMP';
data.hi     = m + 3*s;  data.lo    = m - 3*s;
data.hi_hi  = m + 4*s;  data.lo_lo = m - 4*s;
data.use_alarm = true;
msg
MES PO → Work Order Mapping
const po = data;
data = {
  master_id: 'WO-MES-' + po.po_no,
  asset_id:  po.line_id || 'UNASSIGNED',
  title:     po.product_name + ' (' + po.qty + ')',
  due_date:  po.delivery_date,
  qty:       po.qty,
  product_id: po.product_code
};
msg
External Payload Normalization (Unifying Various Field Names)
// 외부 시스템에 따라 키 이름이 다른 경우 — 한 줄로 정규화
data.value     = data.value ?? data.val ?? data.v;
data.timestamp = data.timestamp ?? data.ts ?? metadata.ts;
data.tag_id    = data.tag_id ?? data.tagId ?? data.id;
msg
Threshold Violation Count Accumulation (Stateful Pattern)
// 자산 attribute 와 함께 사용 — 상태는 메시지 자체에 적재
data.consecutive_fail = (data.consecutive_fail ?? 0) + (data.passed ? 0 : 1);
data.alert            = data.consecutive_fail >= 5;
msg
Message Statistics Summary (Processing Merge Results)
// flow_merge 후 data.merged 배열을 받아 요약
const arr = data.merged || [];
data.count   = arr.length;
data.values  = arr.map(m => m.data.value).filter(v => v != null);
data.mean    = data.values.reduce((a,b)=>a+b, 0) / (data.values.length || 1);
data.max     = Math.max(...data.values);
data.min     = Math.min(...data.values);
delete data.merged;
msg
Applying Thresholds Per Time Period
const h = new Date(metadata.ts).getHours();
const threshold = (h >= 8 && h < 18) ? 90 : 70;   // 주간 90, 야간 70
data.alarm = data.value > threshold;
data.threshold = threshold;
msg
Filter Scripts
Priority Whitelist
['ERROR', 'CRITICAL'].includes(data.priority)
Time Window (Weekdays Only)
const h = new Date(metadata.ts).getHours();
h >= 8 && h < 20
Asset/Tag ID Pattern
/^MOTOR-.*$/.test(originator.id)
// 또는
metadata.tag_id && metadata.tag_id.startsWith('LINE-A.')
Threshold + Stability (N Consecutive Times)
data.value > 100 && (data.consecutive_count ?? 0) >= 5
Business Hours/Holiday Check
const d = new Date(metadata.ts);
const h = d.getHours();
const wd = d.getDay();
// 평일 09-18시만 통과
wd >= 1 && wd <= 5 && h >= 9 && h < 18
Specific Site Only
['SITE-01', 'SITE-02'].includes(metadata.site_id)
Check All Required Fields Present
data.value != null && data.tag_id && metadata.ts
Blocking Self-Published Messages (Bidirectional Sync)
metadata.source !== 'flow'
Switch Case Scripts
By Priority Level
// case "Critical"
['CRITICAL', 'EMERGENCY'].includes(data.priority)

// case "High"
data.priority === 'ERROR'

// case "Normal"
['WARN', 'INFO'].includes(data.priority)
By Asset Status
// case "Running"
data.status === 'RUN'

// case "Stopped"
['STOP', 'IDLE', 'PAUSED'].includes(data.status)

// case "Faulted"
data.status === 'FAULT' || data.error_count > 0
By Work Order Lifecycle
// case "Start"
data.event_type === 'START_REQUEST'

// case "End"
data.event_type === 'COMPLETE' && data.qty_done >= data.qty_planned

// case "Abort"
data.event_type === 'CANCEL'
All the scripts above are collections of patterns commonly used in production environments. They also work if wired directly into the graph as-is, and you only need to adjust thresholds/field names to fit your domain.
Glossary
Flow Engine Terms
| Term | Meaning |
|---|---|
| entity_type | Type of subject entity for the message — Asset, Tag, Site, Order, Customer, Product, Employee, Calendar, etc. |
| originator | The subject entity the message refers to (entity_type + id). E.g., Asset/MOTOR-001 |
| type | The message classification label. Identifies what type of event the trigger received |
| data | The message body (payload) — mainly read/written by transform and action nodes |
| metadata | The message's context (time, site, shift, tag ID, etc.) — maintained through to the end of the flow even after transformation |
| relation | The label on a node's output wire. SUCCESS/FAILURE/TRUE/FALSE/MATCH/NO_MATCH/DEFAULT/THROTTLED/EXHAUSTED (all uppercase) |
*_field dynamic option | An input method reading a value from a path in the message payload (e.g., data.tag_id) instead of a static value |
| Glob pattern | The wildcard expression of the trigger's *_pattern option — * matches 0 or more characters, ? matches exactly 1 character |
| Snapshot | A version-level backup automatically stored on graph save. Used to revert to a previous state in an incident |
| Partial update (fetch+merge) | The way an Update node looks up the existing record then merges only the entered fields. Empty values are ignored |
| SKIPPED | Handling in which messages not matching the trigger pattern don't flow to subsequent nodes and are also excluded from the counter |
| EXHAUSTED | The branch fired when a flow_retry node exceeds the maximum retry count |
| THROTTLED | The branch fired when a flow_throttle node blocks a message exceeding the limit within the window |
Domain/Abbreviation Glossary
A summary for quick reference within the manual of abbreviations frequently used in plant operating environments.
| Abbreviation | Meaning | In This Manual |
|---|---|---|
| MES | Manufacturing Execution System — work order/production performance management | External integration target (HTTP/MQTT/external DB) |
| ERP | Enterprise Resource Planning — enterprise resource/planning system | External integration target |
| SCADA | Supervisory Control and Data Acquisition — monitoring/control | External integration target / exit point of flow_publish_asset_command |
| OPC | Open Platform Communications — industrial communication standard | Target of the Edge category (flow_edge_opc_*) |
| OEE | Overall Equipment Effectiveness — availability × performance × quality | flow_on_oee_event trigger |
| RAM | Reliability·Availability·Maintainability | flow_on_ram_event trigger |
| EMS | Energy Management System | flow_on_ems_event trigger |
| EQL | Domain event rule expression | language: "EQL" option of flow_script_filter/flow_script_transform |
| CEP | Complex Event Processing | EQL-based rule engine. Alarms must occur only through the CEP path to maintain consistency |
| PO | Purchase Order — purchase/production order | Unit converted into a work order during MES integration |
| WO | Work Order | flow_*_work_order node group |
| CMMS | Computerized Maintenance Management System | External integration target |
| MTTF/MTTR | Mean Time To Failure / To Repair | Key indicators of RAM events |
| HMI | Human–Machine Interface | Operating screens such as SCADA |
Version Notes
The introduction timing of the major feature groups covered by this manual as of the current point. If you're operating a previous version, some features may behave differently.
V2026.05 — Domain Automation Expansion
- New Edge category, 11 types — OPC server/tag CRUD + monitoring automation
- 5 work order status transition types —
flow_start/end/pause/resume/abort_work_order - 2 tag alarm band partial update types — updates only entered fields of numeric/boolean alarm bands
- New
flow_retryflow control — backoff + max attempts + EXHAUSTED branch - 5 new trigger types —
flow_on_asset_health_status/_connection_status/_oee_event/_ram_event/_ems_event - Update node partial update (fetch+merge) — merges only entered fields after looking up the existing record
- Relations standardized to uppercase —
SUCCESS/FAILURE/... all uppercase, existing graphs auto-converted - SKIPPED handling — excludes messages not matching the trigger pattern from the counter
- Redeploy All operational tool — bulk-reload active flows
- Reset All Counters — bulk-reset node + flow-level statistics
V2026.03 — Release Stability
- Auto-snapshot stored on graph save
- Live debug panel (2-second refresh at the bottom of the inspector) + node lighting/duration display
- Import/export (graph JSON file)
- Introduced a load watchdog — issues a diagnostic log line if load persists
Before That
- M1 — engine/UI skeleton, graph CRUD, visual canvas
- M2 — domain action nodes (asset, tag, work order, production domain, etc.)
- M3 — trigger diversification, 8 filter/transform/external integration types, script engine
- M4 — debug loading/execution history screen, statistics, deploy/undeploy, import/export
- M5 — domain trigger integration, bulk scenario verification
All features and behaviors covered by this manual are based on the above V2026.05 point in time.
Related Screens
- CEP (Complex Event Processing): EQL-based domain event rule engine
- Alarm: Alarm occurrence/history
- Data Point: Tag data lookup/analysis
- Developer Guide: Flow Engine: engine architecture, node interfaces, DB schema