Dashboard (Platform Summary / Site Map)
Table of Contents
- Overview
- Screen Layout
- Top Page Header
- Global Site Map
- Data Pipeline Card
- Site Scale and Connection Status Summary
- Right Health Rail
- Platform Key Metrics
- Bottom Operation Widgets
- Key Drill-downs
- Response by Anomaly Signal
- FAQ
- Related Screens
Overview
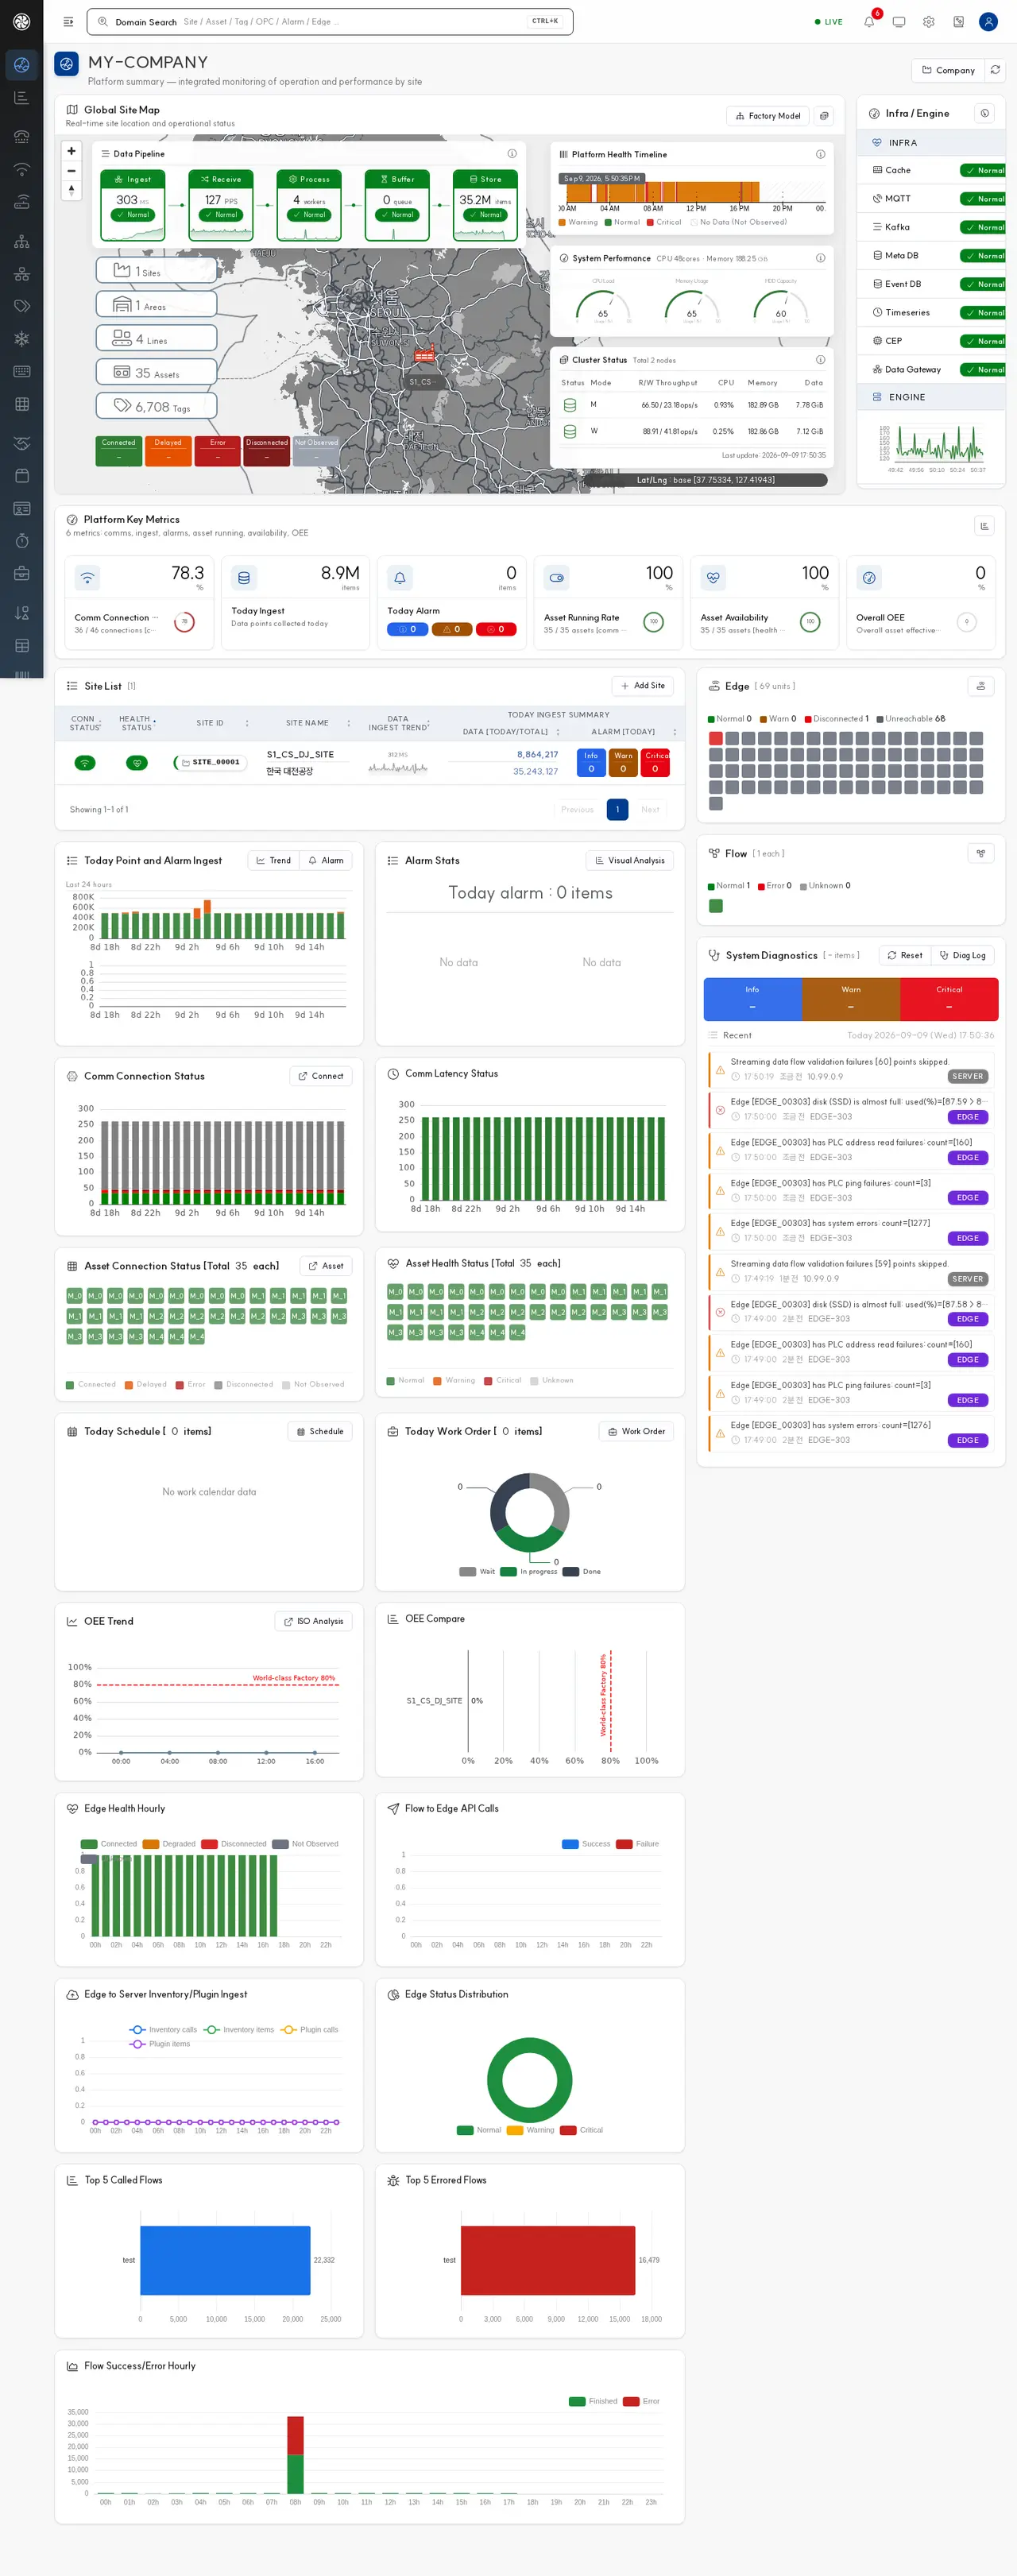
The dashboard is the primary operation home screen encountered immediately after login. In the left menu, it is displayed as OVERVIEW > Dashboard, and its internal URL is /map/index.
This screen consolidates the site map, data pipeline, infrastructure health, cluster status, and key KPIs into a single view, enabling operators to quickly answer the following questions:
- Which site or line is generating anomaly signals?
- Is the data collection, reception, processing, or storage pipeline blocked?
- Are the cache, WS, MQTT, Kafka, Event DB, and time series engines functioning normally?
- Are today's collection volume, alarms, equipment utilization, and OEE within the normal range?
The first screen previously referred to as "Summary" in older documentation has been reorganized as the Dashboard in the current UI. The URL remains
/map/index.
Screen Layout
┌────────────────────────────────────────────────────────────────────┐
│ 상단 바: 메뉴 토글 / 도메인 검색 / LIVE / 알람 / 전체화면 / 설정 / 매뉴얼 / 사용자 │
├────────────────────────────────────────────────────────────────────┤
│ 한국핵심산업                                                        │
│ 플랫폼 요약 - 사이트별 운영·성능 통합 모니터링                       │
├──────────────────────────────────────────────────────────┬─────────┤
│ 글로벌 사이트 맵                                         │ 우측     │
│  ┌ 데이터 파이프라인: 수집 → 수신 → 처리 → 버퍼 → 저장 ┐  │ 헬스     │
│  │ 사이트 마커 / 지도 확대·축소 / 좌표 표시              │  │ 레일     │
│  │ 사이트·구역·라인·설비·태그 카운트                    │  │         │
│  │ 연결 상태 칩: 정상·지연·이상·끊김·안됨                │  │         │
│  └────────────────────────────────────────────────────┘  │         │
├────────────────────────────────────────────────────────────────────┤
│ 플랫폼 핵심 지표: 통신 연결률 / 금일 수집 / 금일 알람 / 가동률 / 가용률 / OEE │
├────────────────────────────────────────────────────────────────────┤
│ 하단 위젯: 사이트 목록 / 포인트·알람 / OPC / 설비 / 생산 / 엣지 / 플로우 / 진단 │
└────────────────────────────────────────────────────────────────────┘
| Area | Content |
|---|---|
| Top Page Header | Company name, [Company Settings] button, "Platform Summary - Integrated Site Operation and Performance Monitoring" description |
| Global Site Map | Site locations, marker status, map controls, coordinate display |
| Data Pipeline | Throughput and status for collection, reception, processing, buffer, and storage stages |
| Site Scale Summary | Number of sites, zones, lines, equipment, and tags |
| Connection Status Summary | Counts for normal connection, connection delay, connection anomaly, connection disconnected, and not connected |
| Right Health Rail | Platform health timeline, system performance, cluster status, infrastructure/engine status |
| Key KPI | Communication connection rate, today's collection, today's alarms, equipment utilization, equipment availability, overall OEE |
| Bottom Operation Widgets | Site list, point/alarm trends, OPC/equipment status, production schedules/work orders, Edge/Flow/Diagnostics |
Top Page Header
The company name is prominently displayed at the top of the body. A company represents the top layer of the equipment hierarchy and there is only one per installation.
| Item | Description |
|---|---|
| Company Name | Example: 한국핵심산업 |
| Company Settings | Opens a window to edit the company name, legal information, country, timezone, logo, etc. |
| Auxiliary Description | 플랫폼 요약 - 사이트별 운영·성능 통합 모니터링 |
| Real-time Notifications | Equipment status changes, diagnostic events, etc., are displayed as toasts in the top right |
For information on using the global search and notifications at the top, refer to Console Navigation and Common Screens.
Global Site Map
The map simultaneously displays the locations and operational status of registered sites. Site markers are represented by factory icons, and marker labels show the site ID or a short name.
Map Controls
| Action | Method |
|---|---|
| Zoom In/Out | Map left + / - buttons or mouse wheel |
| Pan | Drag the map |
| View Site | Click a site marker |
| Check Coordinates | Latitude/Longitude display at the bottom of the map |
Marker Interpretation
| Status | Meaning | Next Step |
|---|---|---|
| Normal | Major connections and data ingress for the site are normal | Check only KPIs and collection volume |
| Caution | Some connection delays or equipment warnings | Connection Status, Alarm |
| Anomaly | Connection anomaly, critical alarms, or possible sharp drop in data | Diagnostics, Edge Gateway |
| Unconfirmed | Insufficient coordinates or collection history | Factory Management, Data Point |
Data Pipeline Card
The platform's data processing flow is displayed as cards above the map.
수집 ─→ 수신 ─→ 처리 ─→ 버퍼 ─→ 저장
| Stage | Representative Metric | Normal Interpretation |
|---|---|---|
| Collection | Hz | Whether the field collection loop is alive |
| Reception | PPS | Number of points the server receives per second |
| Processing | Number of Workers | Whether pipeline workers are operating normally |
| Buffer | Waiting Queue | Whether there is no queue accumulation |
| Storage | Storage Count | Whether time series and event storage are accumulating |
The small sparklines at the bottom of each card show recent trends. If values drop to 0 or if only the buffer continues to increase, suspect a data ingress or storage bottleneck.
Site Scale and Connection Status Summary
The current model scale and connection status are summarized at the bottom left of the map.
Model Scale
| Item | Meaning |
|---|---|
| Site | Number of registered factories or business sites |
| Zone | Number of operational zones under a site |
| Line | Number of production lines |
| Equipment | Number of registered equipment |
| Tag | Number of collection, formula, and status tags |
If the model scale differs from the expected value, check the registration status of sites, assets, and tags in Factory Management.
Connection Status Chips
| Chip | Meaning | Priority |
|---|---|---|
| Normal Connection | Recent data reception is normal | Reference |
| Connection Delay | Reception delay occurred | Check daily trend |
| Connection Anomaly | No reception or error beyond the reference time | Immediate inspection |
| Connection Disconnected | No reception for a long period | Check field, Edge, or network |
| Not Connected | No reception history yet | Check registration and commissioning status |
The exact status criteria are based on the Status Code Definitions.
Right Health Rail
The right rail of the dashboard provides a quick view of the platform's own health status. Operators use this to distinguish between site anomalies and system anomalies.
Platform Health Timeline
| Item | Description |
|---|---|
| Recent Time | Last aggregation time |
| Color Timeline | Normal, caution, and anomaly states by time slot |
| Purpose | Check if the system state fluctuated during a specific time period |
If orange or red sections are concentrated in the timeline, check the Diagnostics logs and System logs for the same time period.
System Performance
| Gauge | Meaning | Inspection Criteria |
|---|---|---|
| CPU Load | Server CPU utilization | Check cause of load if 80% or higher for a long period |
| Memory Usage | JVM/System memory utilization | Check for memory pressure if continuously rising |
| HDD Occupancy | Data store utilization | Review cleanup or expansion if 85% or higher |
Cluster Status
| Item | Meaning |
|---|---|
| Status | Cluster node roles and normality |
| Mode | Operational mode such as Single, Master, or Worker |
| Read/Write Latency | Storage response delay |
| CPU / Memory / Data | Cluster resource usage |
| Last Update | Cluster status aggregation time |
Infrastructure and Engine Status
| Area | Items |
|---|---|
| Infrastructure | Cache, WS, MQTT, Kafka, Event DB, Time Series |
| Engine | Real-time metrics related to collection, processing, delay, and storage |
If any infrastructure item is abnormal, it is more likely to be a common platform issue than a site-specific problem. First, check System and Diagnostics.
Platform Key Metrics
Six KPI cards necessary for operational judgment are displayed at the bottom of the dashboard.
| KPI | Meaning | Drill-down Screen |
|---|---|---|
| Communication Connection Rate | Number of normal connections / Total number of connections | Connection Status |
| Today's Collection | Number of data points collected today | Data Point, Daily Statistics |
| Today's Alarms | Total number of alarms generated today | Alarm |
| Equipment Utilization | Ratio of equipment with normal data ingress | Equipment, Connection Status |
| Equipment Availability | Ratio of equipment with normal health diagnostics | Equipment, Diagnostics |
| Overall OEE | Overall equipment efficiency | Production Management, ISO Analysis |
KPI cards are not intended for viewing a single value. If a value falls outside the normal range, navigate to the related screen on the card to narrow down which site, line, equipment, or tag is the cause.
Bottom Operation Widgets
Below the map and KPIs are widgets that show the daily operational flow of the entire platform, rather than a selected site.
| Widget | Display | Navigation |
|---|---|---|
| Site List | Connection status, health status, site ID/name, 24-hour data trend, today's data/alarms | Asset tree upon clicking site name |
| Data Points and Alarms | Point reception and alarm trends for the last 24 hours | Trend, Alarm |
| Alarm Statistics | Total alarms for today, distribution by priority and ON/OFF | Alarm Analysis |
| OPC Trend | Communication connection status, communication delay status | Connection Status |
| Equipment Status | Equipment connection heatmap, equipment health heatmap | Asset, Equipment |
| Production Info | Today's shift schedule, today's work orders, OEE trend/comparison | Production Management, ISO Analysis |
| Edge | Hourly Edge health, Edge API calls, Edge push reception, Edge status distribution | Edge |
| Flow | Top 5 calls, Top 5 errors, hourly execution trend | Flow |
| Diagnostic Sidebar | Edge heatmap, Flow health heatmap, INFO/WARN/ERROR diagnostic list | Diagnostics, System Logs |
Bottom widgets are useful for narrowing the "scope" of a problem. For example, if today's collection volume has decreased, following the sequence of Site List → OPC Trend → Equipment Heatmap allows you to quickly identify which layer the data stopped at.
Key Drill-downs
| Starting Point | Next Screen | Purpose |
|---|---|---|
| Map Marker | Factory Management, Equipment | Verify site, line, and equipment structure |
| Connection Status Chip | Connection Status | Identify disconnected or delayed data sources |
| Edge Anomaly | Edge Gateway | Check Edge device resources and PLC collection status |
| Alarm Toast | Alarm | Verify tag, asset, and time of alarm occurrence |
| Diagnostic Toast | Diagnostics | Track causes of system events |
| Sharp Drop in Collection | Daily Statistics, Data Point | Compare which site or tag has reduced data |
| OEE Decline | Production Management, ISO Analysis | Decompose causes by work order, utilization, performance, or quality |
Response by Anomaly Signal
| Symptom | Primary Check | General Action |
|---|---|---|
| Sharp Drop in Connection Rate | Connection status chip, Connection Status | Identify disconnected OPC/Edge, check network and collection process |
| Today's Collection is 0 or drops sharply | Data pipeline collection/reception cards | Check Edge collection, MQTT/Kafka, and storage in order |
| Increase in Buffer Queue | Pipeline buffer card, right engine metrics | Check storage delay, external system call delay, and worker count |
| Infrastructure Item Abnormal | Right infrastructure rail | Check Cache/WS/MQTT/Kafka/DB status in System |
| Increase in Critical Alarms | Alarm KPI, alarm toast | Sort by tag, asset, and priority in Alarm |
| Decline in Equipment Availability | Equipment availability card | Check equipment health status, diagnostic logs, and recent maintenance history |
| OEE Decline | Overall OEE card | Identify which axis (utilization, performance, or quality) dropped in ISO Analysis |
FAQ
Q. The numbers on the dashboard seem to have stopped. A. Check if the LIVE status at the top is green. If it is gray or the time is frozen, reconnect by refreshing the browser. If the issue persists, check Diagnostics.
Q. Site markers are not appearing on the map. A. Latitude and longitude must be registered for the site. Check the site coordinates and model registration status in Factory Management.
Q. The connection rate is low, but the Edge appears normal. A. The HTTP status of the Edge device may differ from the tag data reception status. Identify the actual targets of reception delay or disconnection in Connection Status.
Q. All infrastructure in the right health rail is normal, but only one site is abnormal. A. This is more likely a network, Edge, or OPC/PLC connection issue for that specific site rather than a common platform failure. First, check the site marker and Connection Status.
Q. The alarm toast has disappeared. Can I see it again?
A. In Alarm, narrow the recent time range to 10M or 30M to verify. If it is a system event, search for the same time period in Diagnostics.
Related Screens
- Console Navigation and Common Screens — Left menu, top search, common patterns
- Daily Statistics — Daily operational statistics and comparative analysis
- Connection Management — Protocols, connection status, Edge Gateway
- Alarm — Real-time alarms and history search
- Equipment Management — Equipment list and equipment-level dashboards
- Data Point — Raw data inquiry by tag
- Diagnostics — System diagnostic events
- System — Infrastructure health, logs, settings, environment information
- Status Code Definitions — Connection, health, alarm, and production status codes